Shanghai team releases full RSI pretraining report, 801-30B base model and SFT data
Shanghai Innovation Institute and Xinqi Intelligence jointly released the first fully public pretraining-level RSI technical report, the 801-30B base model, and high-quality SFT data. The team claims that only two groups worldwide publicly apply RSI to pretraining from scratch: US startup Recursive and this Shanghai classroom. The model, trained in under three months, reportedly ranks among the top open-source base models of its size.
Coverage timeline
机器之心机器之心
超智能这场竞赛的胜负手不在后训练,而在谁先跑通 RSI 预训练。 负责人表示:预训练和后训练不是一个量级的事:算力、经验、工程,每一样都高出一个数量级。但很不幸,它也是最重要的事,是我们对智能进行加工的第一性基础。正因如此,RSI 必须落到预训练上,智能制造才开始复利:没跑通的一方只能眼看着代差一代代拉大。 一间教室,和一家 40 亿美元的公司 过去一年,「RSI」(Recursive Self-Improvement,递归自我改进)几乎成了大模型圈最热的词:让 AI 自己提出改进、自己执行、自己评估,再在结果之上继续改进,循环往复,越改越强。但如果追问一句:有谁把 RSI 用到了 从零开始的前沿预训练上 ,并且公开了出来?据我们所知,答案只有两个。 一个在美国。Recursive 是一家明星创业公司,创始团队来自 Google、Meta 和 OpenAI,《纽约时报》称其为一项「40 亿美元级」的项目。两周前,他们发布了从零训练的模型 Flint。 另一个在上海的一间教室里。门牌号是 801 ,也是这个模型的名字。 我们是唯一公开全部技术细节的一家。 今天,上海创智学院与新序智能联合 发布首份完整公开的预训练级 RSI 技术报告、base 模型(801-30B)、高质量 SFT 数据。 不只是一次试水:用时不到三个月,这间教室交出的模型,站进了同尺寸开源基座的第一梯队。 技术报告:https://github.com/GAIR-NLP/801-30B/blob/main/report.pdf 模型与数据:https://github.com/GAIR-NLP/801-30B 801(红色)与开源模型对比:上排为 base 模型评测,下排为 SFT 后评测(标 † 的评测中,对比模型为厂商发布的完整后训练版本) 为什么要用 RSI 做预训练? 为什么这件事为什么值得做?答案是:RSI 的终点不在后训练,而在预训练。 预训练决定一切能力的上限 一个大模型的知识和推理能力,绝大部分在预训练阶段形成。后训练做的是把这些能力「激发」出来,很难凭空创造出预训练没有给的东西。预训练因此是整条 AI 能力链的源头:之后所有的 agent、应用和产品,都建立在它之上。打个比方:后训练是装修,预训练是盖房子的地基和主体结构。装修再好,也改变不了房子能盖几层。 只有进入预
Related stories
Chinese AI startups HyperVolve and Apexin announce funding and model releases
Chinese AI startup HyperVolve announced tens of millions RMB in angel funding led by Lanchi Ventures, with participation from SenseTime Guoxiang Capital, Lenovo Star, Inno Fund, and Tsinghua alumni seed fund, to build research foundation models using recursive self-improvement. Separately, Apexin, founded by 27-year-old Tsinghua assistant professor Chen Yongchao, released Apex-35B-V1.0, a 35B model claiming SOTA results on 21 benchmarks against comparable models.
2 reports · 1 sources
Recursive releases Flint, 40B coding model built largely by its Eureka Machine AI system
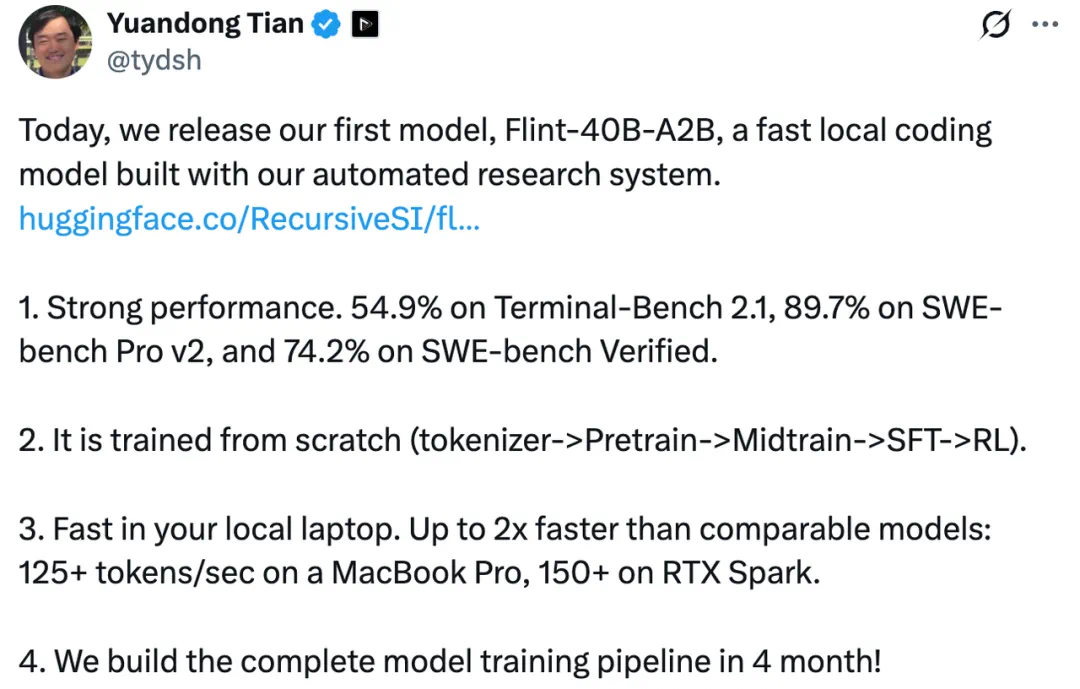
Startup Recursive has released Flint, an open-weight, 40B-parameter mixture-of-experts coding model with 2.5B active parameters per token, built in under four months with heavy automation from its Eureka Machine AI research system. The model outperforms sub-50B MoE models on coding benchmarks like SWE-Bench Pro v2 and runs at over 125 tokens per second on a MacBook Pro M4 Pro, with weights available on Hugging Face under Apache 2.0.
Anthropic files S-1 for Nasdaq IPO under ticker ANT
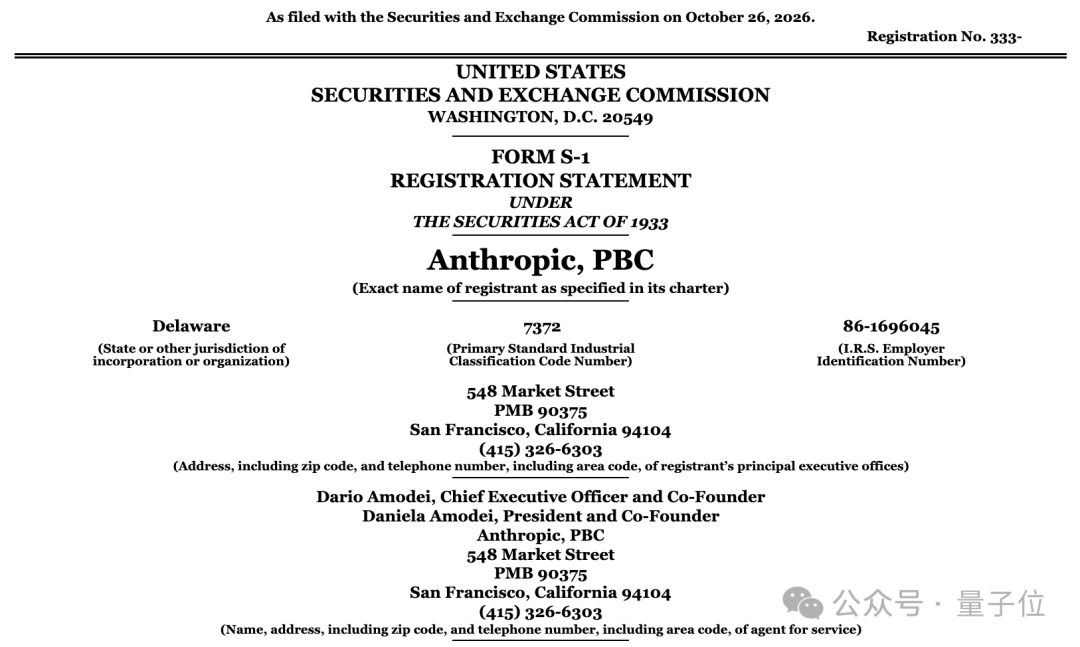
Anthropic publicly filed its S-1 with the SEC on October 26, 2026, for a Nasdaq listing under the ticker ANT, with share count and price range undetermined. The 335-page prospectus reveals H1 2026 revenue of $16.29 billion, an $80.75 billion net loss, over 11,900 customers spending $100K+ annually, and long-term compute commitments exceeding $500 billion, alongside an unusual governance structure preserving founder control.
33 reports · 8 sources1703 points · 1674 comments
Meta FAIR veteran Yuandong Tian: My research work could be automated within five years
In a podcast interview, Yuandong Tian, a veteran of Meta FAIR and co-founder of Recursive Superintelligence, said he realized his research work could be replaced within five years after completing a project with results from an internal OpenAI model. He co-founded the startup in May with a $6.5 billion valuation and over $650 million in funding, choosing to proactively build a company toward that direction rather than passively lose his job.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe