Princeton's QUEEN: 4B Chess Model Plays at Grandmaster Level and Explains Moves
Princeton University's Chen Danqi team released QUEEN, an open-source chess model with about 4 billion parameters that plays at the level of a typical grandmaster and explains its moves in natural language. The model, detailed in an arXiv paper, aims to bridge the gap between strong but silent chess engines and fluent but weak language models.
Coverage timeline
机器之心机器之心
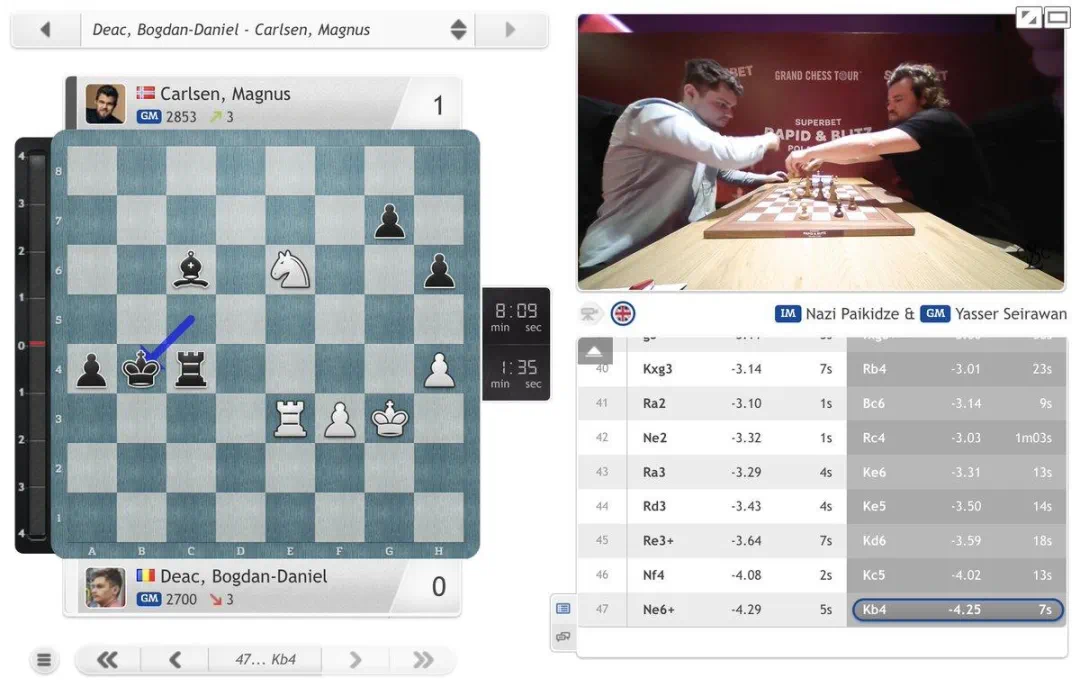
编辑|Panda 9 月 27 日,第 46 届国际象棋奥林匹克团体赛在撒马尔罕落幕。东道主乌兹别克斯坦在最后一轮以 2.5 比 1.5 击败乌克兰,第二次捧起公开组金牌,中国女队则第七次登上女子组最高领奖台。下一场焦点大战也近在眼前:11 月底,两位 20 岁的棋手古克什(Gukesh D)与辛达罗夫(Javokhir Sindarov)将在日内瓦争夺世界冠军头衔,这将是史上最年轻的一场世界冠军对决。 看过近几年顶级棋赛直播的人,大概都熟悉画面一侧那根上下浮动的评估条。引擎会告诉你此刻白方领先半个兵,或者某步棋让胜率一落千丈,但它从不解释原因——这仍要靠坐在解说席上的特级大师。 棋盘最左边那根黑白相间、上下浮动的竖条就是评估条 这其实是 AI 领域一个普遍困境的缩影。最强的专家模型往往是沉默的,而最会说话的语言模型,在专业领域里又常常不够强。国际象棋引擎早已把人类远远甩在身后,却说不出一句人话。前沿大模型能写出头头是道的分析,可它推荐的着法本身未必站得住,解释也就成了无本之木。 近日,普林斯顿大学陈丹琦团队在 arXiv 发布了一项成果,尝试把这两端接起来。 他们训练的模型名叫 QUEEN ,总参数量约 4B,棋力接近一位典型特级大师,同时能用自然语言讲清楚自己为什么这样走。 论文标题:Language Models that Play Chess and Explain Their Moves 论文地址:https://arxiv.org/abs/2610.03695v1 模型地址:https://huggingface.co/collections/princeton-nlp/queen-chess-models 开源代码:https://github.com/queen-project/queen 会下的不会说,会说的下不好 国际象棋与 AI 的缘分可以追溯到 1950 年。那一年,克劳德·香农(Claude Shannon)估算了国际象棋的计算复杂度,并设想了下棋机器的样子。 此后七十多年,从依靠手工评估函数的「深蓝」,到靠自我对弈成长起来的 AlphaZero,再到基于 Transformer 的 Leela Chess Zero(Lc0),引擎一代比一代强。但它们输出的始终只是一个着法和一串胜率数字。 语言模型这边的问题恰好相反。论文梳理发现,此前专门
Related stories
StarSkirmish Bench refreshed with flagship LLM results for StarCraft BW coding
A developer refreshed StarSkirmish Bench, a benchmark where LLMs play StarCraft: Brood War by writing code, adding results from flagship models of OpenAI, Anthropic, Google, and Muse. The update provides a new comparison point for code-driven game-playing capabilities across major AI labs.
1 reports · 1 sources249 points · 111 comments
Zhizhi Innovation open-sources IQuest-Q1, 320B-param sparse MoE coding model
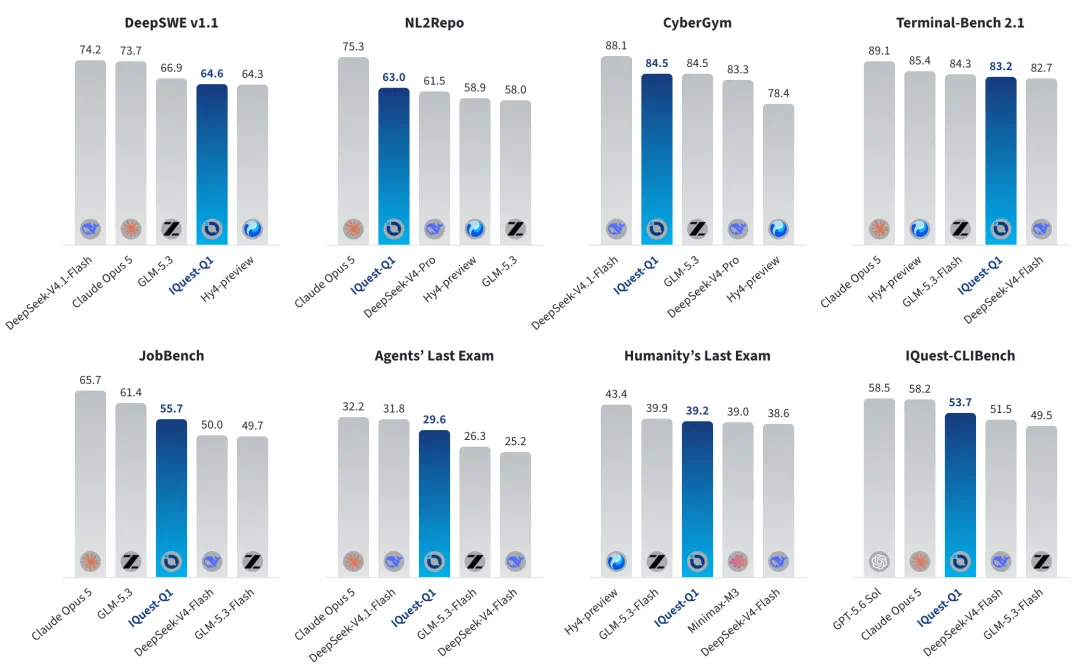
Chinese research institute Zhizhi Innovation released IQuest-Q1, a sparse MoE model with ~320B total parameters and ~15B active parameters, focused on coding, software engineering, and complex agentic tasks. The model shows balanced performance across benchmarks including NL2Repo, CyberGym, Terminal-Bench 2.1, DeepSWE v1.1, and JobBench, with weights and blog published on GitHub and Hugging Face.
1 reports · 1 sources
Alibaba CEO outlines machine intelligence vision, plans 5T-10T parameter Qwen models
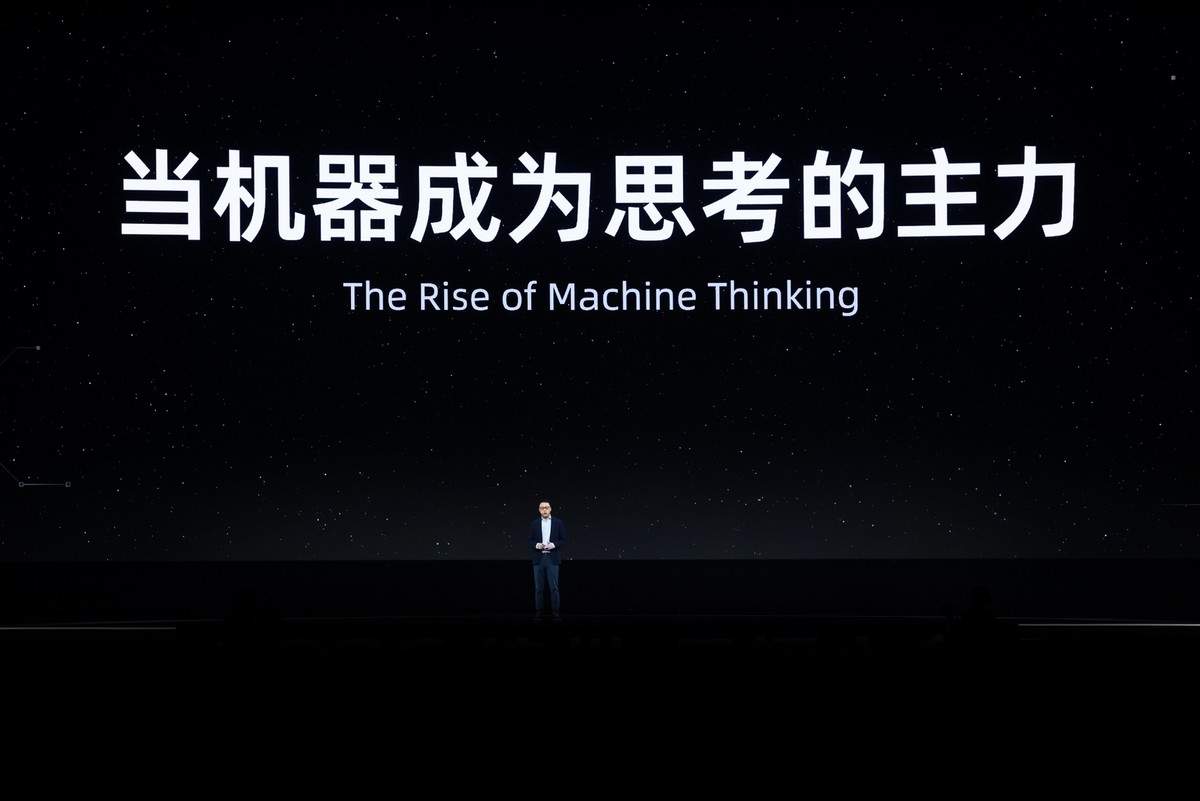
At the 2026 Yunqi Conference, Alibaba CEO Eddie Wu said machine thinking will scale to 1000 times human thinking, positioning AI models, chips, and cloud as the three pillars of the machine intelligence era. The company announced plans to train a new Qwen model with 5-10 trillion parameters, progress in recursive self-improvement (RSI), and the release of the Zhenwu V900 AI chip with 3x the compute of its predecessor.
5 reports · 2 sources
Alibaba open-sources Qwen-Image-2.1, a 7B image model with unified generation and editing
Alibaba's Qwen team open-sourced Qwen-Image-2.1, a 7B-parameter image generation model that unifies text-to-image and image editing in a single pipeline. It natively supports transparent image generation and accepts up to ten reference images, with enhanced local editing and portrait/product fidelity. According to the team, it scores 60.28 on the Qwen-Image-Bench, the highest among open-source models and ahead of Nano Banana 2.0 (59.82) and GPT Image 1.5 (59.65).
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe