Diffusion Intelligence Unveils 350B-Parameter MoE Diffusion Language Model Clover-35B-A3B-Preview
Diffusion Intelligence released Clover-35B-A3B-Preview, a 350B-parameter MoE diffusion language model with about 3B active parameters per token, supporting thinking mode. In the WindTunnel web agent benchmark across 49 tasks with 3 attempts each, Clover achieved a median execution time of 1.52 seconds and a success rate of 98.6%, compared to 3.21 seconds and 95.9% for the Jev + Mercury 2.5 combination. The model can handle coding, web operations, tool calls, and HTML generation, and is positioned as faster than autoregressive models at similar scale.
Coverage timeline
量子位量子位
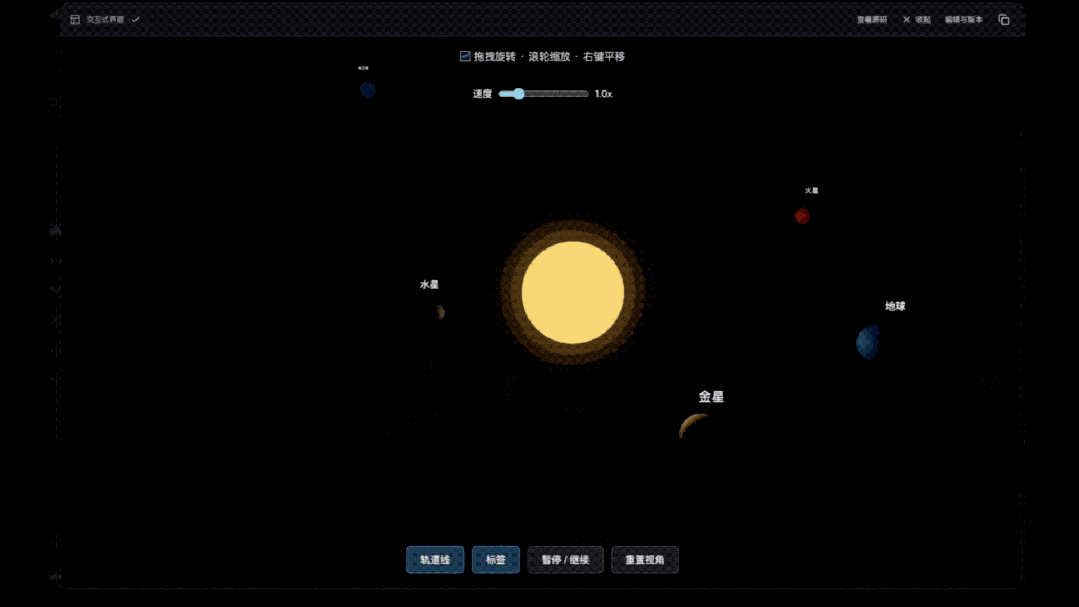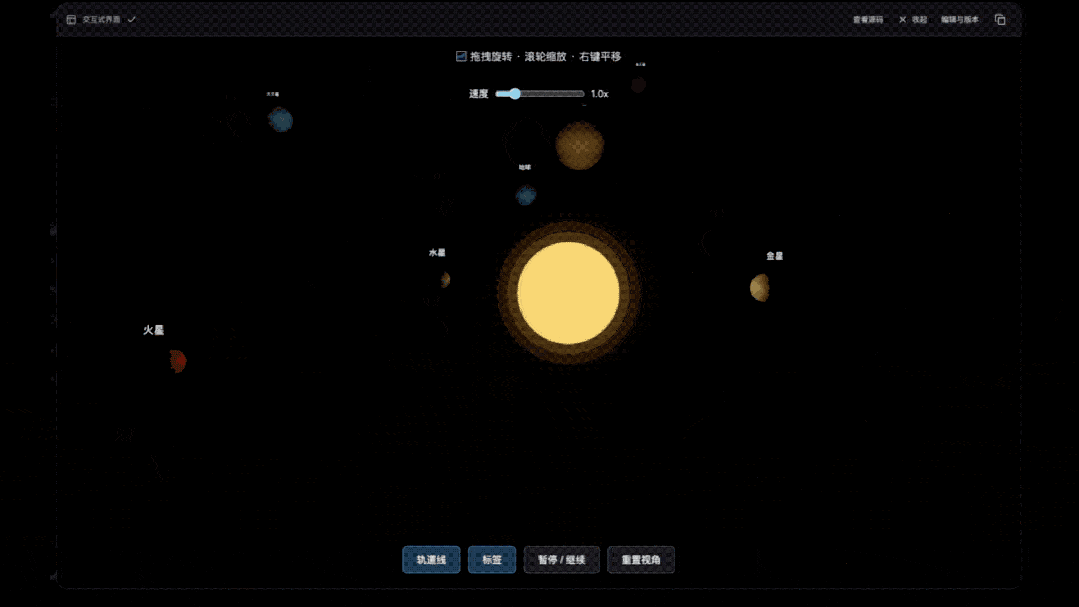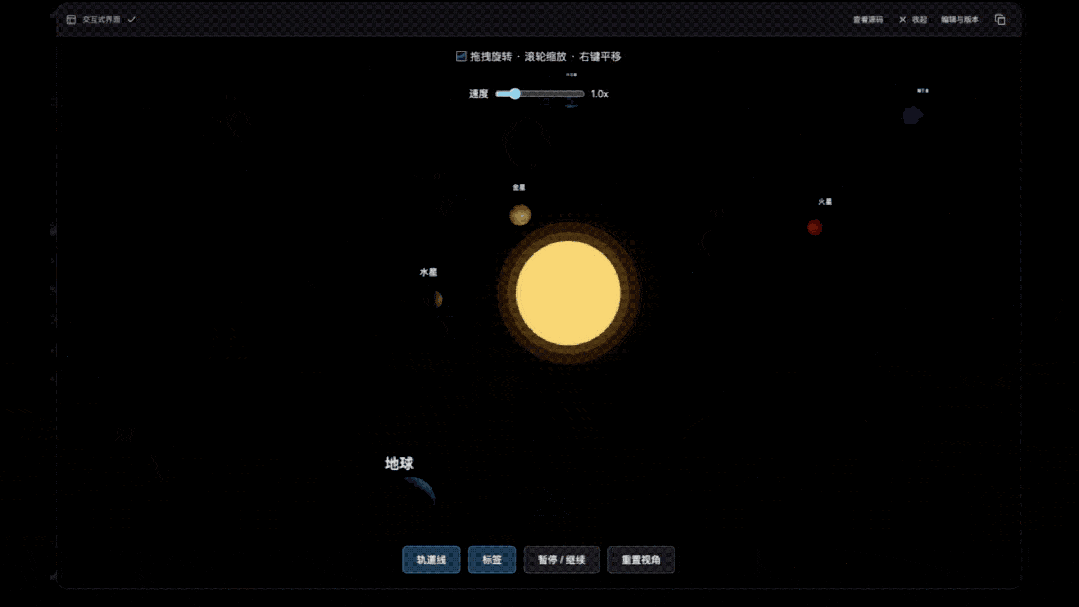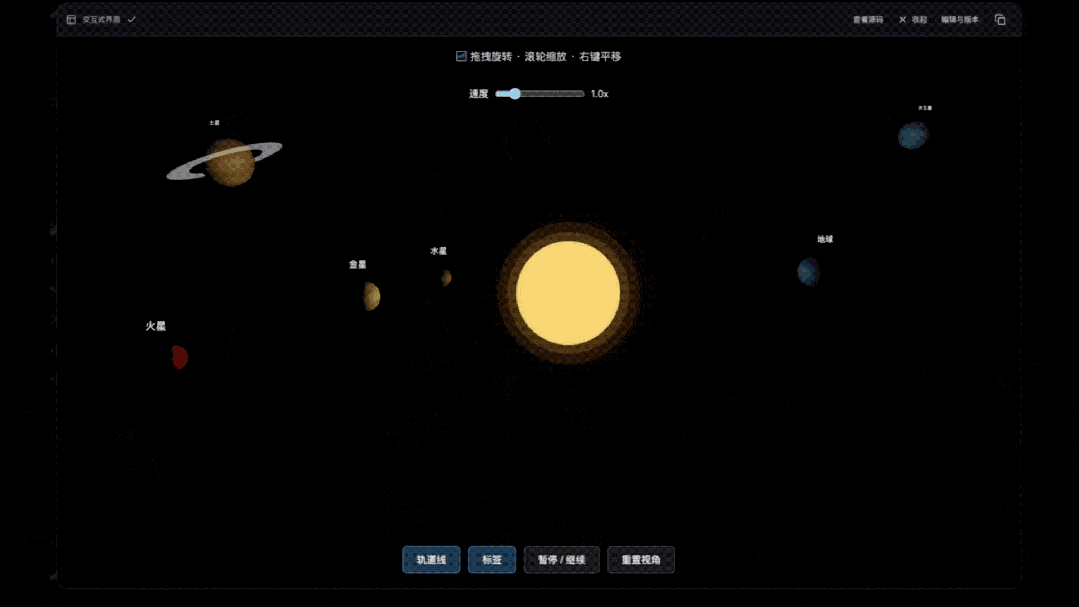
刚刚,扩散模型杀进Agent主场!350亿参数,速度比Jev快一倍 henry 2026-10-29 10:18:28 来源: 量子位 用扩散模型怎么做做Agent? henry 发自 凹非寺 量子位 | 公众号 QbitAI 服了!天天在AI一线冲浪,竟然也会跟不上版本。 谁能想到,印象中用来生图、生视频的 “扩散模型” ,竟然也能写代码、生成网页、调用工具,当Agent了! 就在刚刚, 扩散智能 发布了全新的 扩散语言模型 —— Clover-35B-A3B-Preview 。 虽然名字里多了“扩散”两个字,但实际体验下来,无论是写代码、操作网页、调用工具,还是生成HTML,用法都和我们熟悉的大语言模型差不多。 我个人用下来的第一感受就是一个字:“快”。 比如,让它生成一个太阳系模拟器,Clover就思考了约1秒,然后也就4-5秒,一个能交互的太阳系模拟器就出来了。 再比如,我给它丢了一堆简历信息,让它整理成LaTeX格式的简历代码,也就十来秒,搞定~ 有一说一,用过GPT的朋友,应该都懂盯着“正在思考”等半天是什么感觉,要不然最近也不会有主打快速决策的Jev什么事儿~ 而说到Jev,Clover这次还真和它比了一把速度。 在网页Agent评测WindTunnel的49个任务中,每个任务尝试3次,Clover的中位执行时间为 1.52秒 ,Jev+Mercury 2.5组合为 3.21秒 ,用时少了一半多。 尝试成功率也略高,分别为 98.6%和95.9% 。 对比同表中的Gemini,速度更是快了好几倍! 好好好,你个扩散模型,要把自回归逼疯?(doge) 会做Agent任务的扩散模型 说回模型,Clover-35B-A3B-Preview这次采用MoE架构,总参数350亿,每个token激活约30亿参数,支持思考模式。 它进一步将团队的扩散语言模型,从此前Dream 7B的 70亿 参数,推进到了 350亿 总参数规模。 更关键的是,参数量上来后,Clover的速度并没有因此变慢,它在同尺寸对比中超过自回归模型。 除了前面的交互页面和代码生成,官方演示里,Clover还进一步展示了复杂任务、WebUI生成等Agent能力。 Clover可以通过WebMCP,连续处理六项任务,涉及开票、课程报名、金额汇总、活动状态查询、以及客户信息查询和发票信息查询。 从下面
Related stories
Liquid AI releases LFM2.5-24B-A2B, an open-weight 24B reasoning model with 2B active parameters
Liquid AI announced LFM2.5-24B-A2B, an open-weight 24B reasoning model with 2B active parameters, designed for fast, private on-device agents. The company claims it outperforms Qwen3.6-35B-A3B on the LiveClaw benchmark.
2 reports · 2 sources287 points · 80 comments

Ant Group open-sources Ling-3.1-flash, a 560B-parameter MoE model with 1M context
Ant Group's Ling-3.1-flash, a 560B-parameter mixture-of-experts model with 25B active parameters and a 1M-token context window, was released open-source on October 15. The model targets long-horizon complex task execution, using a hybrid linear attention design with KDA layers and Gated MLA to manage computational costs on long sequences.
1 reports · 1 sources
Cloudflare releases open-weight multimodal decision models Clef and Clef-flash
Cloudflare has introduced Clef and Clef-flash, open-weight multimodal decision models based on Qwen3.8-27B and Qwen3.5-9B respectively. The company claims these models outperform Jev in both intelligence and speed, and they are available on Hugging Face for local deployment.
1 reports · 1 sources
Chinese AI startups HyperVolve and Apexin announce funding and model releases
Chinese AI startup HyperVolve announced tens of millions RMB in angel funding led by Lanchi Ventures, with participation from SenseTime Guoxiang Capital, Lenovo Star, Inno Fund, and Tsinghua alumni seed fund, to build research foundation models using recursive self-improvement. Separately, Apexin, founded by 27-year-old Tsinghua assistant professor Chen Yongchao, released Apex-35B-V1.0, a 35B model claiming SOTA results on 21 benchmarks against comparable models.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe