IBM Granite 4.1 3B and 8B Add LLMON Markup Language for Structured Output
IBM's Granite 4.1 3B and 8B models now include LLMON, an LLM-native markup language designed for structured output. The language aims to improve reliability and control when generating structured data from language models.
Coverage timeline
Hugging Face Blog
Related stories
Liquid AI Unveils LFM3 Open-Weight Model Family Across Modalities
Liquid AI announced LFM3, a new open-weight model family with 2B-class variants for text, vision, audio, omni, and decision tasks. The models are designed for fine-tuning and fast on-device inference across various devices.
1 reports · 1 sources171 points · 67 comments
LoopVL open-source VLM shows data efficiency with 260x less training data
Researchers from Renmin University, Baidu, and others released LoopVL, an open-source vision-language model based on the Loop Transformer. Despite using only 0.14T training tokens versus about 36T for Qwen3.5-2B and InternVL3.5-2B, LoopVL matches or exceeds them on benchmarks like LogicVista, MMMU-Pro, and MathVision, demonstrating high data efficiency. The team also observed cross-loop visual attention reorganization, termed 'Visual Aha Moment'.
1 reports · 1 sources
Google launches Gemini 4 Carbon to public, adds swarm feature in Antigravity
Google DeepMind has made Gemini 4 Carbon, its self-described strongest model, available to the general public via consumer, developer, and enterprise channels, two weeks after an initial release to cybersecurity defenders. The model is priced at $2 per million input tokens and $10 per million output tokens, with a scheduled increase to $4/$20 on December 1st. Google also previewed a 'swarm' feature in its Antigravity IDE, and highlighted a research case where Carbon-powered agents formally verified Signal's encryption code.
6 reports · 6 sources295 points · 165 comments

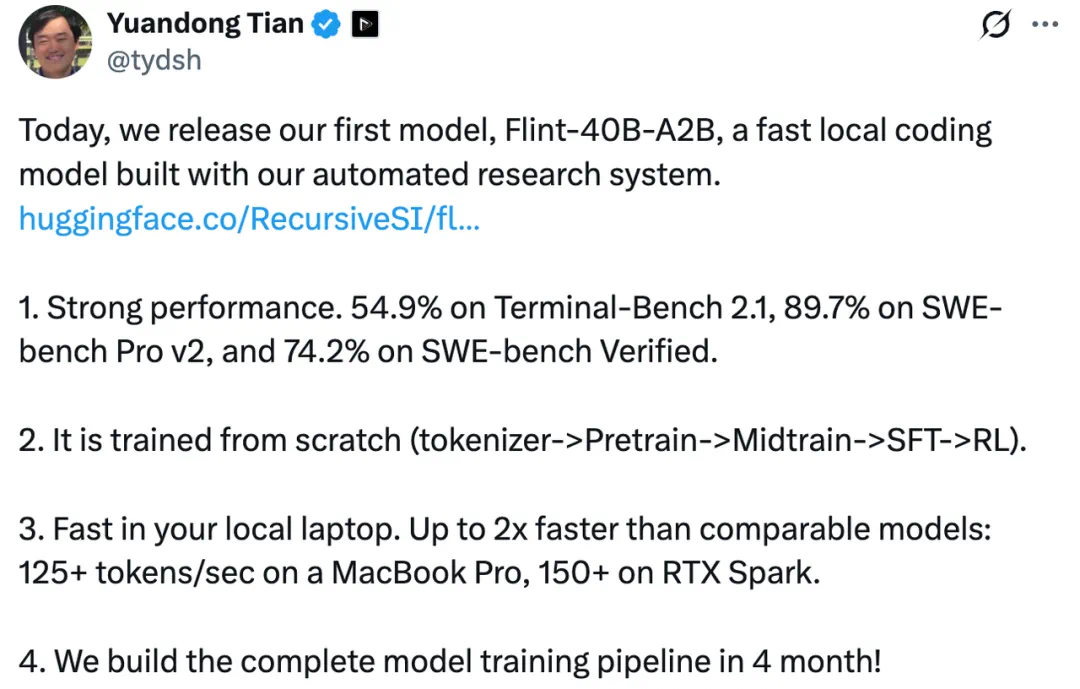
Recursive releases Flint, 40B coding model built largely by its Eureka Machine AI system
Startup Recursive has released Flint, an open-weight, 40B-parameter mixture-of-experts coding model with 2.5B active parameters per token, built in under four months with heavy automation from its Eureka Machine AI research system. The model outperforms sub-50B MoE models on coding benchmarks like SWE-Bench Pro v2 and runs at over 125 tokens per second on a MacBook Pro M4 Pro, with weights available on Hugging Face under Apache 2.0.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe