PKU Researchers Propose MapFlow to Reuse Attention Maps Across LLMs, Cutting Prefill Latency 15-20%
Researchers at Peking University's PKU-DAIR lab propose MapFlow, a method that reuses attention maps as intermediate states across different LLMs to avoid recomputing context when switching models. In evaluations, MapFlow reduces prefill latency by 15-20% and boosts throughput by up to 25% under a P90 first-token latency constraint in multi-turn routing scenarios, while maintaining generation quality. The paper has been accepted at SIGMOD 2027 and the code is open-sourced.
Coverage timeline
机器之心机器之心
模型 A 负责规划,模型 B 负责细化和总结;复杂问题交给强模型,简单问题交给轻量模型——多模型协作,为 AI Agent 应用提供了兼顾效果与成本的路径。 但 Agent 或者说模型之间的交接,隐藏着一笔重复计算的开销。 上一轮,大模型刚刚处理完一份长文档;下一轮,小模型接手时,却往往需要把相同的内容再计算一遍。数据库结构、工具说明、对话历史、任务背景……这些反复出现的上下文,在切换模型后,又变成了新的 prefill 负担。 一个模型已经完成的计算,能否帮助另一个模型更快地处理同一份上下文? 北京大学数据与智能实验室(PKU-DAIR)苗旭鹏助理教授团队提出的 MapFlow ,为这个问题提供了一条新路径:将注意力图作为跨模型复用的中间状态,通过轻量映射、稀疏压缩和融合 GPU 内核,让不同规模的模型共享已经计算出的 token 依赖关系。 在论文评测中,MapFlow 在保持所测任务生成质量的同时,将 prefill 延迟降低 15%–20% ;在多轮对话路由场景下,相同 P90 首 token 延迟约束下的吞吐量最高提升 25% 。相关论文已被 SIGMOD 2027 录用,代码已开源。 论文标题:Accelerating Cross-Model LLM Inference via Attention Map Reuse 论文链接:https://arxiv.org/abs/2610.14688 项目代码:https://github.com/PKU-DAIR/MapFlow 换了模型,为什么缓存就难以接着用? 对大模型来说,开始回答之前,需要先处理输入上下文,这一阶段称为 prefill。输入越长,计算开销通常越大,也就越容易拉长用户等待第一个 token 的时间。 前缀缓存已经能够减少一部分重复计算:当同一个模型再次遇到相同前缀时,可以复用此前生成的 KV Cache。多轮对话中的历史消息,以及多个请求共享的系统提示词,都能从中受益。 然而,跨模型场景会遇到新的障碍。KV Cache 与模型自身的参数和内部表示紧密相关。两个模型即使处理完全相同的文字,也可能拥有不同的层数、注意力头数量和隐藏维度,产生的 KV 状态也并不天然兼容。 因此,多模型系统虽然可以在任务层面分工,却仍然难以共享底层计算结果。尤其当小模型接手大模型积累的长上下文时,模型切换带来的重
Related stories
LoopVL open-source VLM shows data efficiency with 260x less training data
Researchers from Renmin University, Baidu, and others released LoopVL, an open-source vision-language model based on the Loop Transformer. Despite using only 0.14T training tokens versus about 36T for Qwen3.5-2B and InternVL3.5-2B, LoopVL matches or exceeds them on benchmarks like LogicVista, MMMU-Pro, and MathVision, demonstrating high data efficiency. The team also observed cross-loop visual attention reorganization, termed 'Visual Aha Moment'.
1 reports · 1 sources
Lev: Recurrent Decision Model Adapts Compute per Problem, No Chain-of-Thought
Researchers from Lehigh University, UBC, and Vector Institute propose Lev, a decision model that uses recurrent computation instead of chain-of-thought to adaptively spend more compute on hard problems. Lev reads out option probabilities after each recurrent pass, trains jointly across depths, and uses a lightweight stopper to decide how many passes to run, enabling a single set of weights to answer at arbitrary depth. The authors describe this as System 1.5, preserving the direct interface of System 1 while allowing extra compute on difficult cases like System 2.
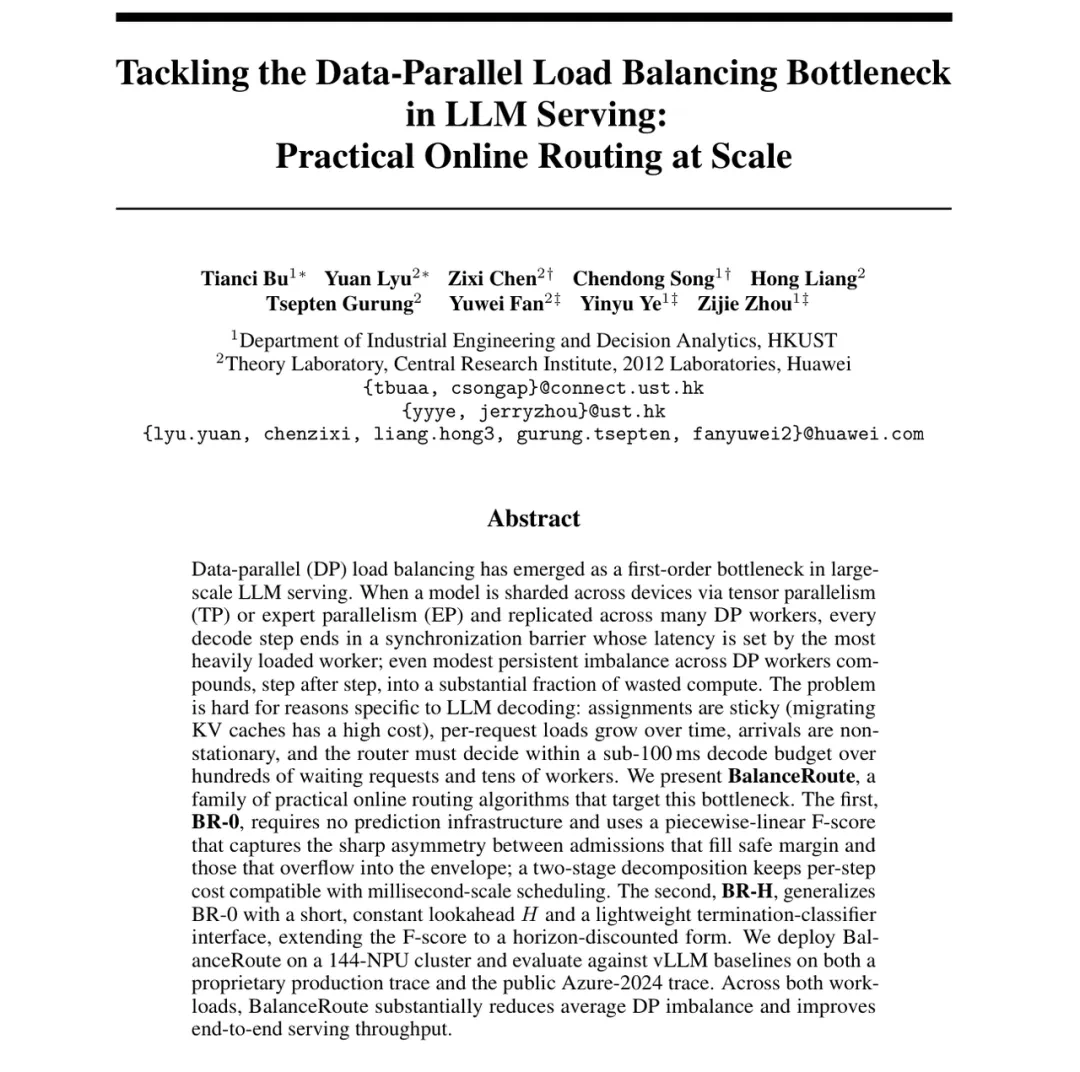
HKUST and Huawei propose BalanceRoute to cut MoE LLM serving load-balancing bottleneck
Researchers from HKUST and Huawei's 2012 Lab propose BalanceRoute, an online routing method that models synchronous waiting in MoE LLM serving and converts short-term load prediction into routing decisions. In a 96-GPU test, the predictor-based variant BR-H improves decode throughput by about 15% over the strongest baseline. The work is accepted by NeurIPS 2026 and deployed in the jointly built MaaS system MathBot-Pie.
Tsinghua and Qujing Introduce KTransformers-FineTune for CPU-GPU MoE Fine-Tuning
Tsinghua University's MADSys lab and Qujing Technology, with LlamaFactory, introduced KTransformers-FineTune (KT-FT), a CPU-GPU co-computation method for fine-tuning mixture-of-experts (MoE) models. It claims 2.5-21.2x throughput gains over traditional offloading by having the CPU compute expert weights directly instead of transferring them to the GPU. The approach includes a semantic-aware proactive layout engine and dynamic thread scheduling for routing skew, and is fully open-sourced.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe