ClawBench: AI agents fail most real-website tasks; 44.4% unsolved by any model
Researchers from MMLU-Pro authors, University of Waterloo TIGER Lab, UBC NAIL Group, UniPat AI, and CMU introduced ClawBench, a benchmark testing AI agents on 144 real production websites across 153 tasks in 15 everyday categories. Top models performed poorly: Claude Sonnet 4.6 failed two out of three tasks, GPT-5.4 completed only 10 of 153 tasks (6.5%), and 68 tasks (44.4%) were unsolved by any model. Unlike sandboxed benchmarks like WebArena or OSWorld, ClawBench uses live websites, highlighting the gap between lab performance and real-world agent utility.
Coverage timeline
机器之心机器之心
论文标题:ClawBench:Can AI Agents Complete Everyday Online Tasks? GitHub: https://github.com/TIGER-AI-Lab/ClawBench 项目主页: https://claw-bench.com/ 论文链接: https://arxiv.org/abs/2604.08523 Hugging Face: https://huggingface.co/collections/TIGER-Lab/clawbench 如果你觉得 AI agent 离帮你订机票、填报销单、投简历只有一步之遥,那 MMLU-Pro 的作者联合滑铁卢大学 TIGER Lab,UBC NAIL Group 和 UniPat AI,CMU 等机构刚刚放出的这项研究,可能会让你冷静下来。 ClawBench,一个让 AI agent 在 144 个真实生产环境网站 上执行日常任务的新评估框架,结果堪称惨烈: 最强的 Claude Sonnet 4.6,每三个任务就要翻车两个。GPT-5.4 更是只有 6.5%—— 在 153 个任务中仅完成 10 个。 而且, 153 个任务里有 68 个(44.4%)没有任何一个模型能做对。一个都没有。 不是 "AI 会不会用浏览器" 的问题,是 "AI 能不能替你干活" 的问题 现有的网页 agent 评测,大多长这样: WebArena :在自己搭的沙箱里测,网站是假的,页面是静态的,能出什么错? OSWorld :虚拟机里跑,就 9 个应用,翻来覆去测那几招。 Mind2Web :更省事,直接拿录好的操作轨迹考选择题 —— 连浏览器都不用开。 前沿模型在这些评测上能轻松拿到 65%-75% 的分数,看上去让 agent 执行现实任务指日可待。 但 ClawBench 干了一件不一样的事: 它让 AI 用浏览器直接接入真实网页 。不是沙箱,不是模拟器,是人们每天都在用的那些生产环境 ——Google Flights、DoorDash、Zillow、Instacart、Airbnb、LinkedIn、Doodle……144 个平台,153 个任务,覆盖了从购物、订票、投简历到填保险报价单等 15 个日常类别。 而且 AI 要解决的不是 "搜一下某个航班多少钱" 这种只读任务。Cla
Related stories
Alibaba releases Qwen3.8-Max, open weights due next week
Alibaba released Qwen3.8-Max, a 2.4-trillion-parameter MoE model with 95B active parameters, on August 3, 2026. It tops several benchmarks, including Artificial Analysis's Agentic Index (55.4) and OSWorld-Verified (86.1), and its API is now available on QwenCloud with open weights expected next week. The model also powers Alibaba's new agent product 'Qwen Office'.
4 reports · 3 sources1110 points · 608 comments

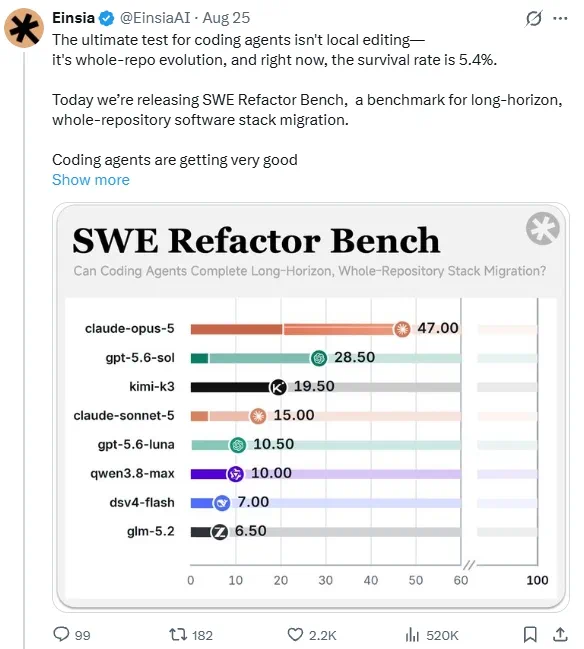
SWE Refactor Bench: Top Coding Agents Fail Long-Horizon Stack Migrations
Einsia AI's Navers Lab released SWE Refactor Bench, a benchmark testing coding agents on whole-repository stack migrations across 20 real open-source projects totaling 867,000 lines of code and 10,594 files. Tasks include language rewrites (e.g., C to Rust) and framework migrations, with top models' pass rates dropping sharply compared to bounded repair tasks like SWE-bench Verified.
1 reports · 1 sources
Anthropic Researchers Use Claude Mythos to Find Cryptographic Weaknesses
Anthropic researchers used Claude Mythos Preview to discover two new cryptographic attacks: one significantly weakens the post-quantum signature scheme HAWK, and another targets round-reduced AES. The work, detailed in a blog post and repository, reportedly cost about $100,000 in API usage over 60 hours. Neither attack currently affects production systems.
5 reports · 2 sources621 points · 926 comments
Unreleased Claude model improves Riemann zeta zero bound to 67.2%
Anthropic reported that an unreleased Claude research model, tasked with attempting the Riemann hypothesis, did not solve it but unexpectedly improved the proven lower bound on the proportion of zeta zeros on the critical line from 41.6% to 67.2%. The effort involved 60 sub-agents, 24 million output tokens, and 2,400 shell commands, and the result was verified by Anthropic mathematicians and reviewed by external number theorists.
5 reports · 4 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe