DaisyRose-27B: 1,200-task RL lifts Terminal-Bench 4.1 score from 5.6% to 12%
Hugging Face announced DaisyRose-27B, an open-weight model fine-tuned with reinforcement learning on 1,200 tasks. According to a Hacker News post, this training improved the model's Terminal-Bench 4.1 performance from 5.6% to 12%, highlighting post-training efficiency.
Coverage timeline
Hacker Newsde_sty
Hugging Face Blog
Related stories
BAAI AREX-2: 27B model beats larger rivals on ML, algorithm benchmarks
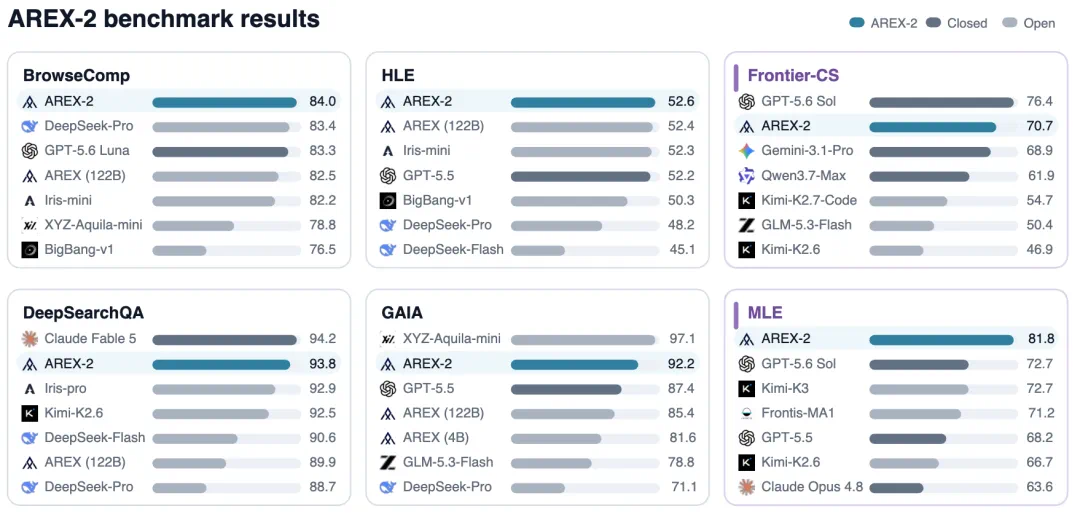
The AREX research group, involving BAAI, USTC, and Renmin University, released AREX-2, a 27B-parameter model built on Qwen3.8-27B and trained on long-horizon reflection data for machine learning and algorithm programming. It outperforms larger models on MLE-bench Lite and Frontier-CS, and sets open-weight records on BrowseComp and HLE, suggesting that long-horizon reflection training can foster cross-domain self-improvement capabilities.
1 reports · 1 sources
Hugging Face Introduces ThinkingBox for Post-Training Agents with Database Grading as RL Rewards
Hugging Face published a blog post describing ThinkingBox, a method for post-training agents by converting database grading into reinforcement learning (RL) rewards. The approach enables agents to be trained using feedback from database query evaluation, potentially improving their performance on tasks involving data manipulation.
MIT: GPT-6 Astra edits Qwen weights, boosting MATH-500 from 7.9% to 48.1%
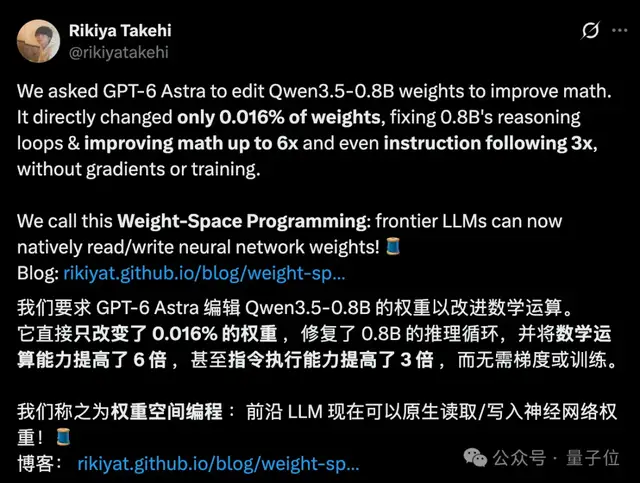
MIT CSAIL researchers demonstrated that GPT-6 Astra can directly read and modify the weights of Qwen3.5-0.8B, improving its MATH-500 score from 7.9% to 48.1% by altering only 0.016% of parameters, without training or gradient descent. The team named this capability Weight-Space Programming. However, spaCy author Matthew Honnibal publicly challenged the paper, arguing that the experimental conditions across the three claimed abilities differ significantly and that the presentation is misleading.
6 reports · 5 sources2949 points · 892 comments
Moonshot unveils Kimi K3.1 Pro, 3T open-weight model with 1M context, weights due Nov 4
Moonshot AI announced Kimi K3.1 Pro, a 3-trillion-parameter open-weight reasoning model with a 1M-token context window, alongside a faster Highspeed variant. Full weights are promised by November 4, 2026. The model scores 55 on the Artificial Analysis Intelligence Index, ranking 4th overall and first among open-weight models, with API pricing at $2/M input and $10/M output tokens.
6 reports · 4 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe