NVIDIA Vera Rubin NVL72 shows up to 7x token throughput per MW vs Blackwell on 1.6T DeepSeek model
SemiAnalysis reports that NVIDIA's Vera Rubin NVL72 inference tests show up to 7x better token throughput per MW vs. Blackwell on a 1.6T DeepSeek model. This exceeds Jensen Huang's earlier claim of 3x for 1T-3T LLMs, suggesting the new platform may offer greater efficiency gains than officially stated.
Coverage timeline
Techmeme
Bryan Shan / SemiAnalysis : Vera Rubin NVL72 inference tests show up to 7x better token throughput per MW vs. Blackwell on a 1.6T DeepSeek model, above Huang's 3x claim for 1T-3T LLMs — Jensen Sandbagging Performance Again, 2x more Annual Profit Per GigaWatt, The More you Buy, The More you Earn, AgentX, InferenceX, Extreme Co-Design

Related stories
vLLM Boosts DeepSeek-V4.1-Flash: 1.9x Low-Concurrency Speed, 5x Agentic Throughput
According to a vLLM blog post dated October 7, 2026, within three weeks of DeepSeek-V4.1-Flash's release, vLLM optimizations made the model 1.9x faster at low concurrency and increased its throughput 5x on the SemiAnalysis AgentX benchmark. The improvements are attributed to SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.
1 reports · 1 sources
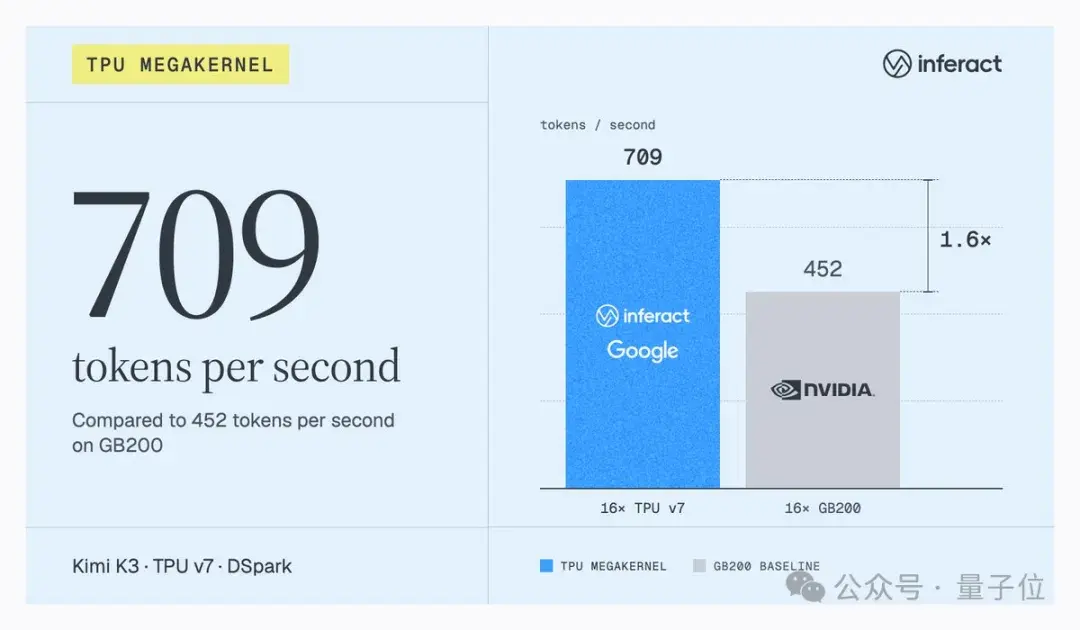
Inferact runs Kimi K3 on 16 Google TPU v7 at 709 tokens/s, 57% faster than GB200
Inferact, a startup founded by the original vLLM team, reported that 16 Google TPU v7 chips ran Kimi K3 at 709 tokens per second, 57% faster than 16 Nvidia GB200 GPUs under identical conditions. The speedup comes from a custom megakernel inference kernel and DeepSeek's DSpark speculative decoding framework; the code has been open-sourced.
1 reports · 1 sources
vLLM reports PD serving results for Qwen3.8-2.4T on GB300 NVL72
vLLM's blog reports PD serving performance for the Qwen3.8-2.4T model on a GB300 NVL72 cluster with an 8K/1K workload. In high-throughput scenarios, vLLM achieved 5000 total token throughput per GPU, and 180 generated tokens per user in low-latency scenarios, both on the Pareto frontier. The post provides srt-slurm recipes and details the decision-making process for reproduction and optimization.
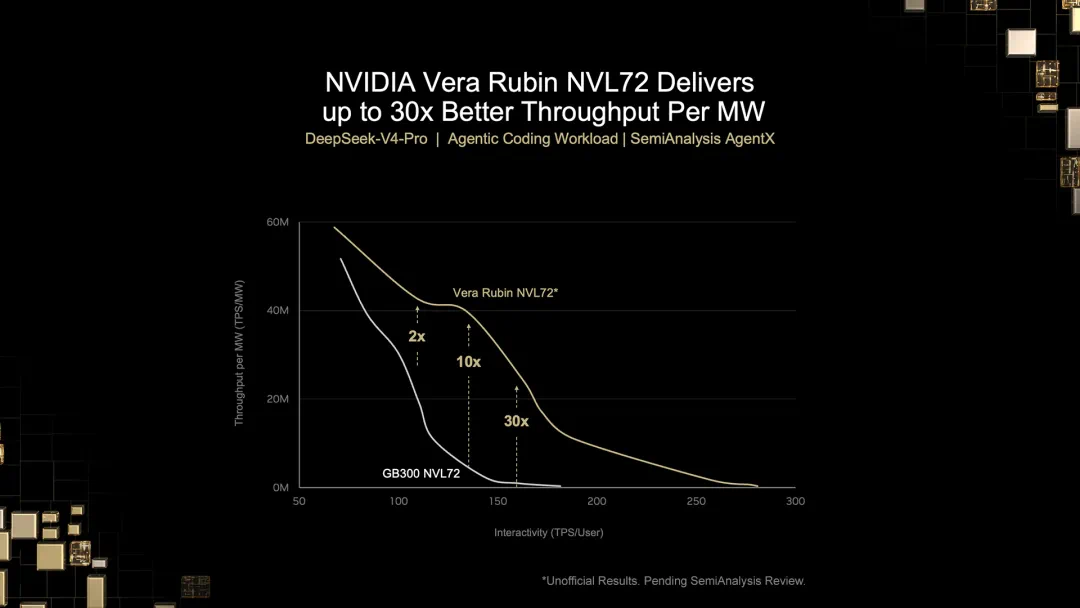
NVIDIA Reports Vera Rubin Real-Chip Results: Up to 30x Agent Throughput per MW vs GB300
NVIDIA released first real-chip performance results for Vera Rubin, showing up to 30x higher agent throughput per megawatt and up to 35x lower token costs versus the GB300 NVL72, based on SemiAnalysis' AgentX workload. Separately, SpaceXAI announced plans to deploy NVIDIA Vera CPUs and expand Grok's AI infrastructure on Vera Rubin, including exploring orbital computing environments.
1 reports · 1 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe