Thinking Machines releases open-weights Inkling 2 Mini, a 26.4B looped transformer
Thinking Machines Lab released Inkling 2 Mini, an open-weights 26.4B-parameter multimodal transformer that loops its middle layers three times per token, with 5.4B active parameters and a 1M-token context window. vLLM announced day-0 support, and Artificial Analysis reports it matches Qwen3.8 27B on its Intelligence Index with about 5x fewer active parameters.
Coverage timeline
vLLM BlogInferact, Thinking Machines and NVIDIA
vLLM supports Thinking Machines' Inkling 2 Mini from day 0: a looped MoE that runs its middle layers three times, with per-pass KV caches, gated messages between passes, fused kernels and DSpark speculative decoding.
Techmeme
Thinking Machines Lab : TML releases Inkling 2 Mini, an open-weights 26.4B-parameter transformer that loops middle layers three times per token for better reasoning with fewer tokens — Today we are releasing Inkling 2 Mini, a fast, powerful model that's small enough to run on your laptop.

Artificial Analysis : Artificial Analysis says Inkling 2 Mini, with 5.4B active parameters, matches Qwen3.8 27B (xhigh) on its Intelligence Index with ~5x fewer active parameters — Thinking Machines has released Inkling 2 Mini at 20 on the Artificial Analysis Intelligence Index, an open weights looped transformer …

机器之心机器之心
编辑|Panda 昨晚, 黎曼猜想的一份 AI 证明声明 ,把大模型的推理能力再次推到聚光灯下。Anthropic 数学家 Levent Alpöge 宣称,自己与 Claude 合作找到了证明,并公布了形式化材料。虽然这项声明仍待独立核验,但已经让人们重新追问:AI 究竟能完成多复杂的工作? 而刚刚,Thinking Machines Lab(TML)发布并开放了 Inkling 2 Mini 的权重。 这是一个总参数 26B 的多模态模型,采用 循环 Transformer(looped transformer) 架构,支持文本和图像输入,最大上下文窗口为 100 万 token。权重已按 Apache 2.0 许可发布,开发者可以下载部署,也能通过 Tinker 进行推理和微调。 模型卡与权重:https://huggingface.co/thinkingmachines/Inkling-2-Mini 官方博客:https://thinkingmachines.ai/news/inkling-2-mini/ 官方宣称能在笔记本上运行,并且能胜任智能体工作。看起来,它要展示的是个人电脑上的模型能做到哪一步。 在 TML 公布的演示中,研究人员带着一台 MacBook Pro 登上飞机,断开网络,让 Inkling 2 Mini 在几分钟内写出了一个可玩的飞行模拟器。演示使用的是配备 48GB 内存的 M5 Pro 机型,推理在本地完成。 他们还构建了一个由 Inkling 2 Mini 搭建的微型像素小镇 Thinkyville。其中,同一模型在一台离线 MacBook 上驱动全部 20 位村民。他们规划一天的生活、闲聊八卦、举办烘焙比赛,还会回复你留在他们门上的便条。 模型发布后,社区反映非常热烈。有人将其接入了 DeepSeek Harness,跑出了飞快的速度。 还有人让它玩通了一个电子游戏,并且发现它还能反复游玩并优化策略,并学会速通。 生成动画 MV 也没有问题: 让同一组权重,多算几轮 Inkling 2 Mini 的技术看点,在于它采用了 循环 Transformer 架构。 普通 Transformer 在生成每个 token 时,会让信息依次经过一组固定的网络层。Inkling 2 Mini 则把中间一段网络重复利用:全模型共 24
Related stories
Thinking Machines Lab debuts Inkling 2 Small, 594B-param MoE; weights due next week
Thinking Machines Lab introduced Inkling 2 Small, a mixture-of-experts model with 594B total and 17B active parameters, initially available as a proprietary model via its Tinker platform and Tinker Playground. The company plans to release the weights next week after safety testing. Artificial Analysis reports the model matches Gemini 3.8 Flash (high) in its index and would be the top open model outside China once weights are released.
2 reports · 1 sources
vLLM Adds Day-0 Support for Thinking Machines' Inkling 2 Small
vLLM announced day-0 support for Thinking Machines' Inkling 2 Small model. The integration includes attention residuals, a new decode kernel for relative-bias attention, all-reduce fused with surrounding operations, and DSpark speculative decoding.
Alibaba launches Qwen4-Max, a 2.4T-parameter MoE model with 1M context
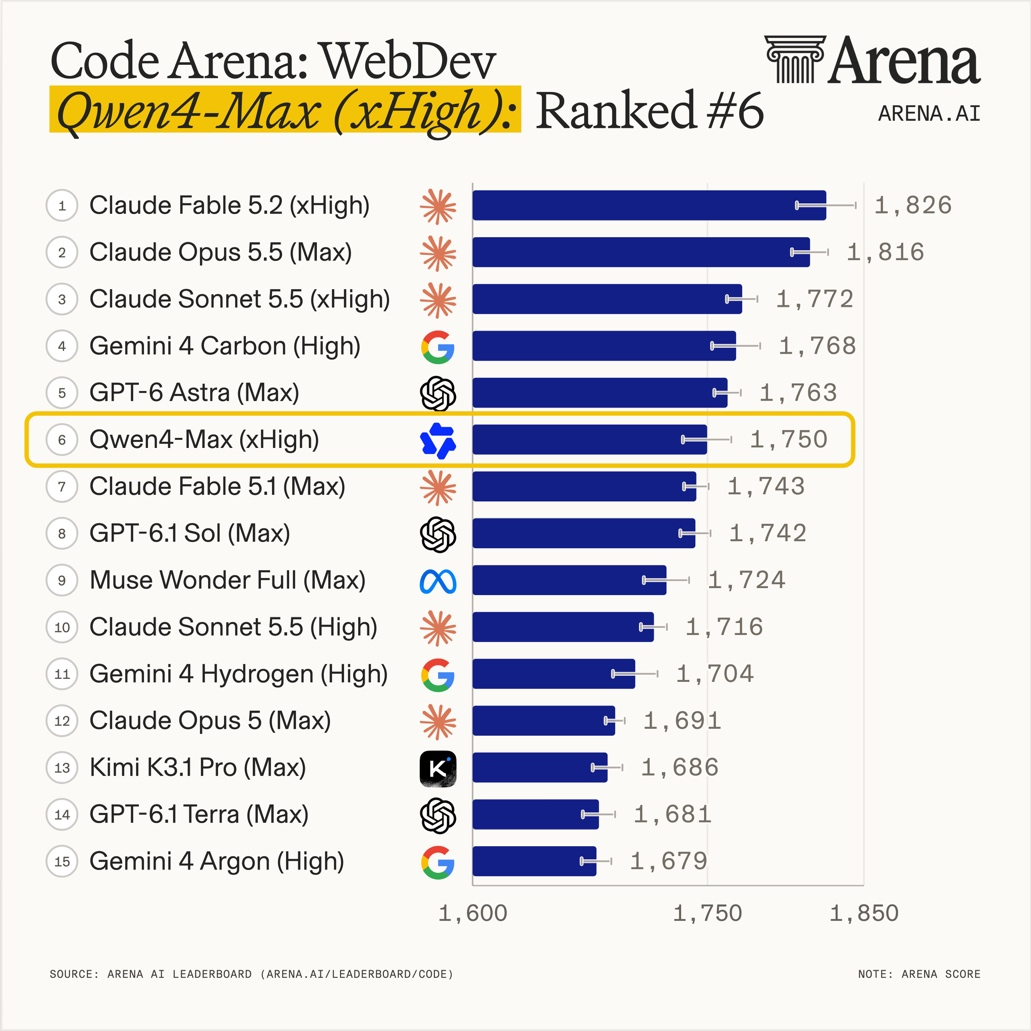
Alibaba released Qwen4-Max, a new flagship 2.4T-parameter mixture-of-experts model with native vision and a 1M-token context window, available via API on the Qwen AI platform. The company claims it outperforms Qwen3.8-Max with up to ~50% fewer tokens per task and lower costs, while smaller open-weight versions are planned. Independent benchmarks show it scores 43 on the Artificial Analysis Intelligence Index, trailing Kimi K3.1 Pro but at lower cost per task.
7 reports · 4 sources879 points · 485 comments
MiniCPM-V 4.7 open-sourced: 35B MoE multimodal model runs on iPhone at 30+ tokens/s
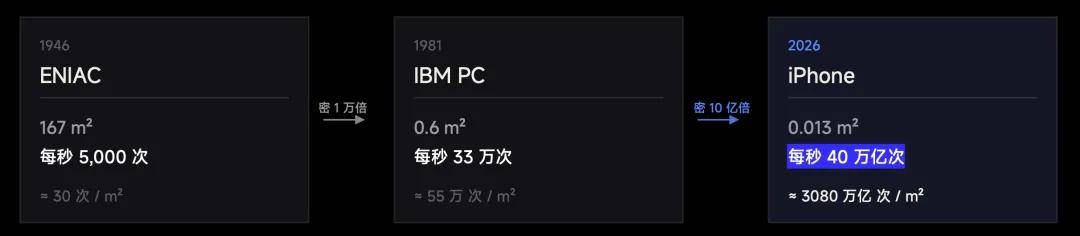
面壁智能 and OpenBMB have open-sourced MiniCPM-V 4.7, including a 35B-A3B MoE multimodal model that runs fully on-device, occupying about 3GB of memory and exceeding 30 tokens per second on the iPhone 18 Pro Max. The team calls this a milestone toward edge intelligence, with co-founder 刘知远 stating that GPT-6-level intelligence on phones within two years is feasible.
1 reports · 1 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe