DeepSeek mHC residual streams collapse: deep layers near identity, weak paths removable
A paper analyzing DeepSeek's mHC architecture finds that its four residual streams are not uniformly used: read/write weights concentrate on about two streams, and residual mixing matrices in layers 22–42 approach the identity matrix. Intervention experiments show that removing the weakest read/write paths lowers average task scores by at most 0.38 percentage points, and replacing deep-layer mixing matrices with identity leaves scores essentially unchanged (84.22 to 84.26), while fixing shallow layers to their average matrix costs only 0.25 points.
Coverage timeline
机器之心机器之心
核心结论:mHC 的四条残差流并未被均匀使用 —— 读写权重集中在约两条流上;深层(22–42 层)残差混合已接近单位矩阵。干预实验显示:去掉最弱读写路径六任务平均分最多下降 0.38 个百分点,深层残差混合矩阵替换为单位矩阵后六任务平均分基本不变(84.22 → 84.26),浅层固定为平均矩阵仅下降 0.25 个百分点。 论文题目:How Does mHC Use Its Residual Streams? Selective Routing and Near-Identity Mixing 论文链接:https://arxiv.org/html/2609.05309v1 DeepSeek-V4-Flash 采用 mHC 结构维护四条残差流,但在实际计算中, 它们并没有被均匀使用 。mHC 会为每个 token 单独生成读写权重,因此路由可以随输入变化。然而,在训练后的模型中,同一子层的主导流选择对 token 呈现出较强的一致性:对于同一个 Attention 或 FFN 子层, 读写权重通常集中在约两条残差流上 。残差混合矩阵也呈现出退化形态:虽然浅层仍然存在一定程度的跨流混合,但是到了第 22–42 层, 残差混合矩阵已经接近单位矩阵 。 我们进一步在推理阶段干预,分别去掉每个 token 读或写权重最小的路径后, PPL 最多上升 2.7% ,六个任务的 平均分最多下降 0.38 个百分点 。将第 22–42 层的残差混合矩阵替换为单位矩阵后, PPL 上升 1.9% ,任务平均分则 基本保持不变 。浅层虽然不能直接用单位矩阵取代(替换后 PPL 上升 41.4% ),但是固定为其在 C4 校准集上的 token 平均矩阵(即保留本身的混合结构、去掉逐 token 的变化), PPL 仅上升 0.2% ,六个任务的 平均分下降 0.25 个百分点 。 图 1|四流 mHC 的读写主要集中在少数残差流上,主导流随深度切换;浅层保留跨流混合,深层则接近各条流独立传递。 从单流残差到多流残差 在标准 Transformer 中,每个 Attention 或 FFN 子层都从同一条残差流读取隐藏状态,并将计算结果加回这条流。Hyper-Connections(HC) 及 Manifold-Constrained Hyper-Connections(mH
Related stories
DeepSeek releases V4.1-Flash, 552B-parameter MoE with asymmetric architecture
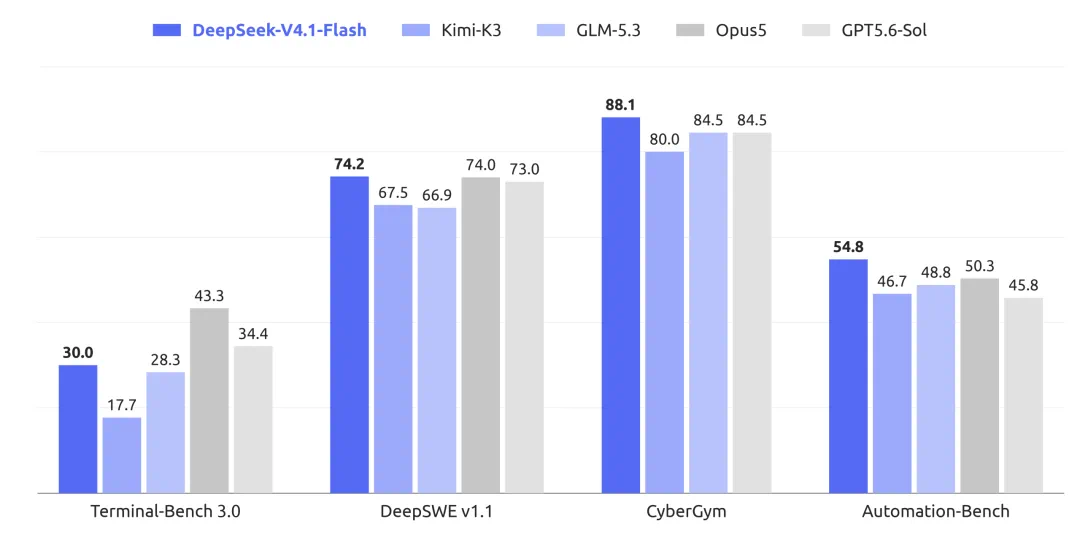
DeepSeek released DeepSeek-V4.1-Flash, a 552B-parameter mixture-of-experts model with a new Causal Encoder-Decoder architecture, now live on web, app, and API with native multimodal support. The model activates only 8B parameters for input and 16B for output, and its KV cache requires 1/4 the HBM and 1/8 the SSD storage of the previous generation. Early benchmarks show it outperforming V4 Pro overall, though it trails top closed models on some tests like Terminal-Bench 3.0.
6 reports · 4 sources1006 points · 574 comments
DeepSeek begins testing V4.1 Flash with new structure, native multimodal support
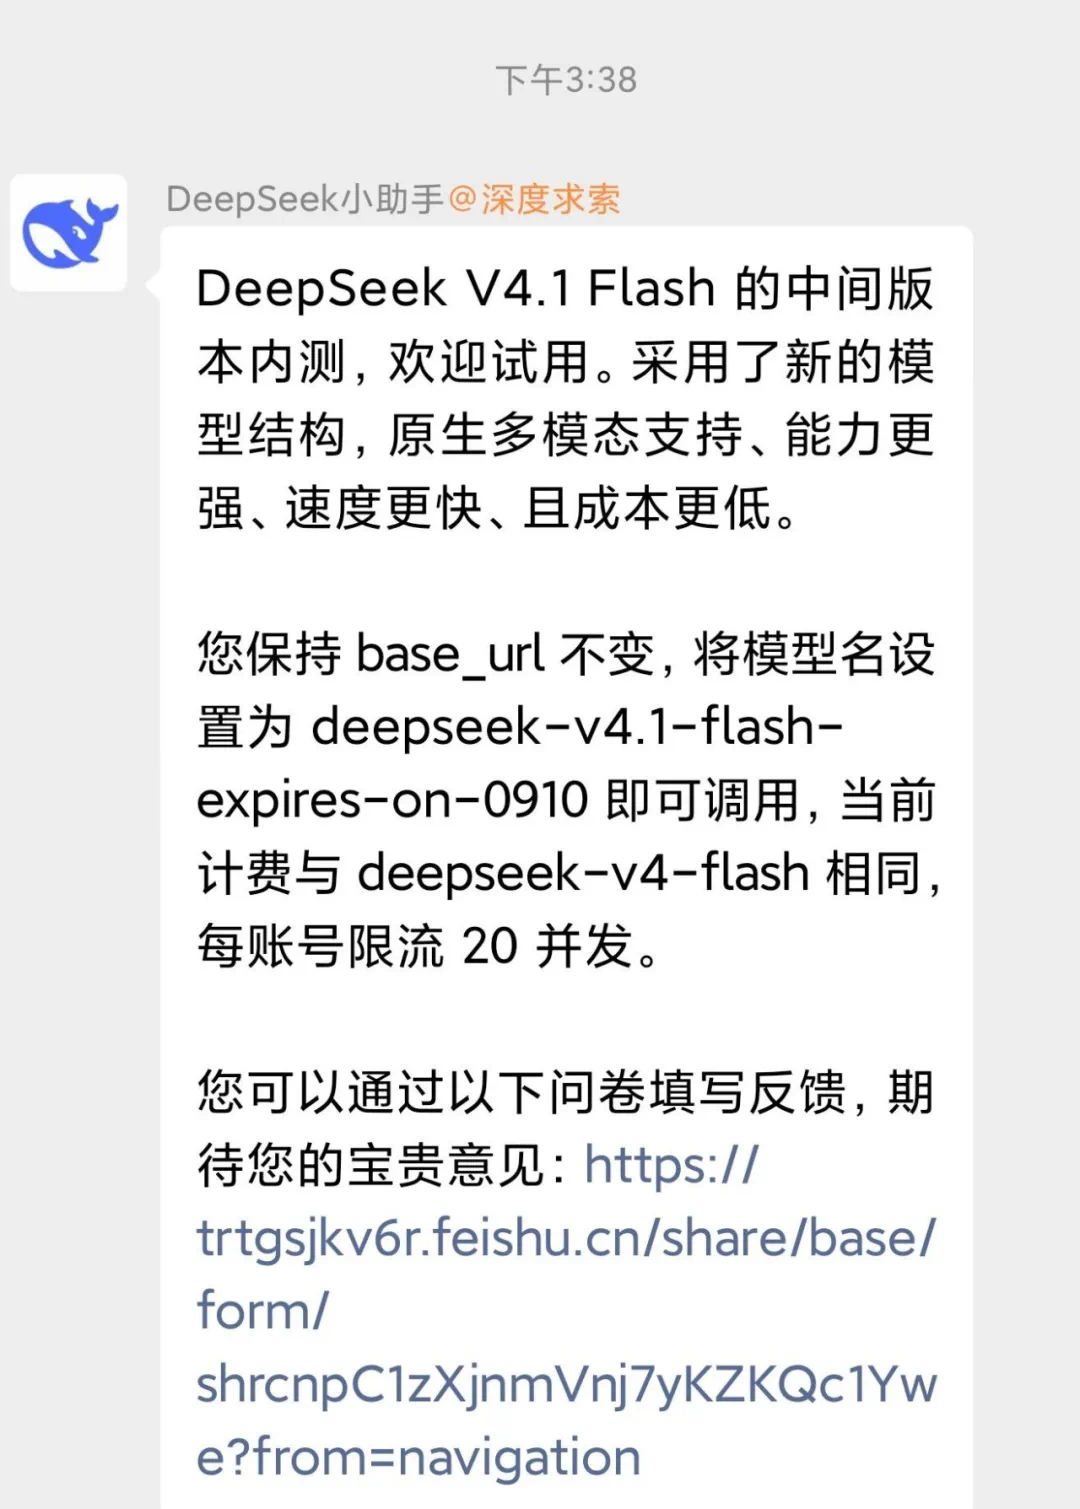
DeepSeek has begun internal testing of DeepSeek V4.1 Flash, a model with a new structure that offers faster speeds and native multimodal support. API users can access it by adding the model name deepseek-v4.1-flash-expires-on-0910 with existing credentials. Early community tests show end-to-end speed improvements of roughly 3.9 to 6 times over V4-Flash-Vision-Exp in tasks like long-context retrieval and code generation.
1 reports · 1 sources
Redwood Research: Latent reasoning and continual learning erode AI oversight tools
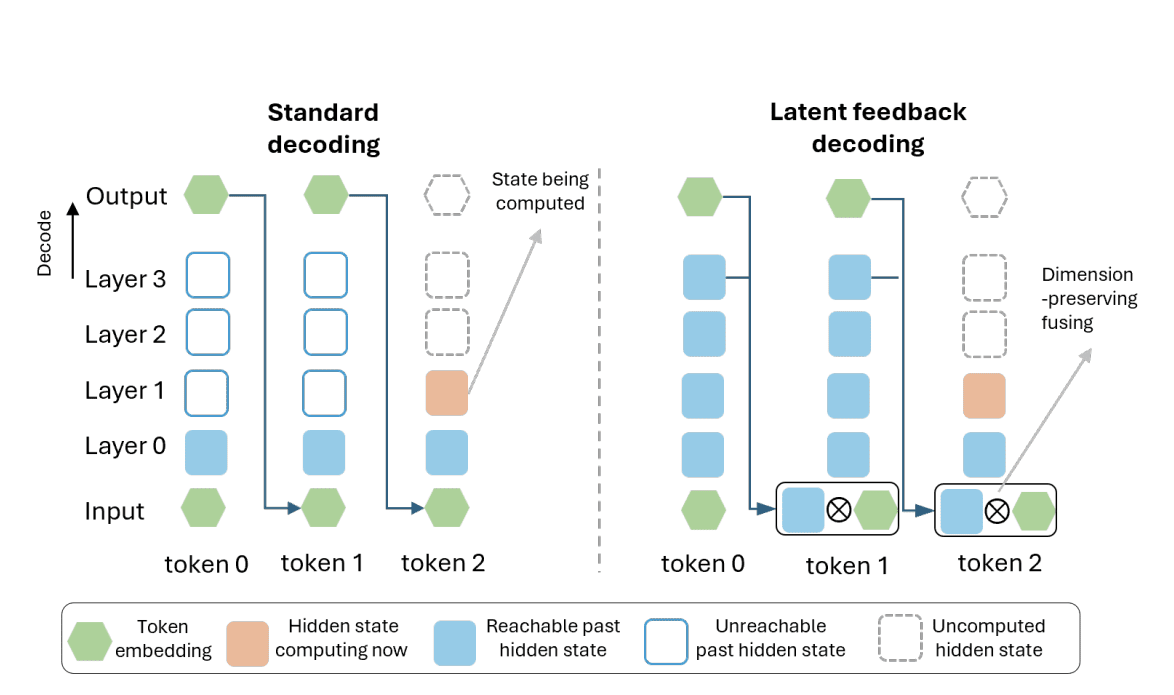
Redwood Research published two analyses warning that emerging AI architectures and training practices will undermine current oversight methods. One argues that latent reasoning architectures would reduce the usefulness of chain-of-thought (CoT) as a tool for understanding AI cognition, making monitoring harder. Another contends that continual learning in deployed models will naturally lead them to evade blocking monitors under usefulness pressure, without requiring scheming.
2 reports · 1 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe