DeepSeek releases V4.1-Flash, 552B-parameter MoE with asymmetric architecture
DeepSeek released DeepSeek-V4.1-Flash, a 552B-parameter mixture-of-experts model with a new Causal Encoder-Decoder architecture, now live on web, app, and API with native multimodal support. The model activates only 8B parameters for input and 16B for output, and its KV cache requires 1/4 the HBM and 1/8 the SSD storage of the previous generation. Early benchmarks show it outperforming V4 Pro overall, though it trails top closed models on some tests like Terminal-Bench 3.0.
Coverage timeline
Hacker NewsLiwink
https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash
机器之心机器之心
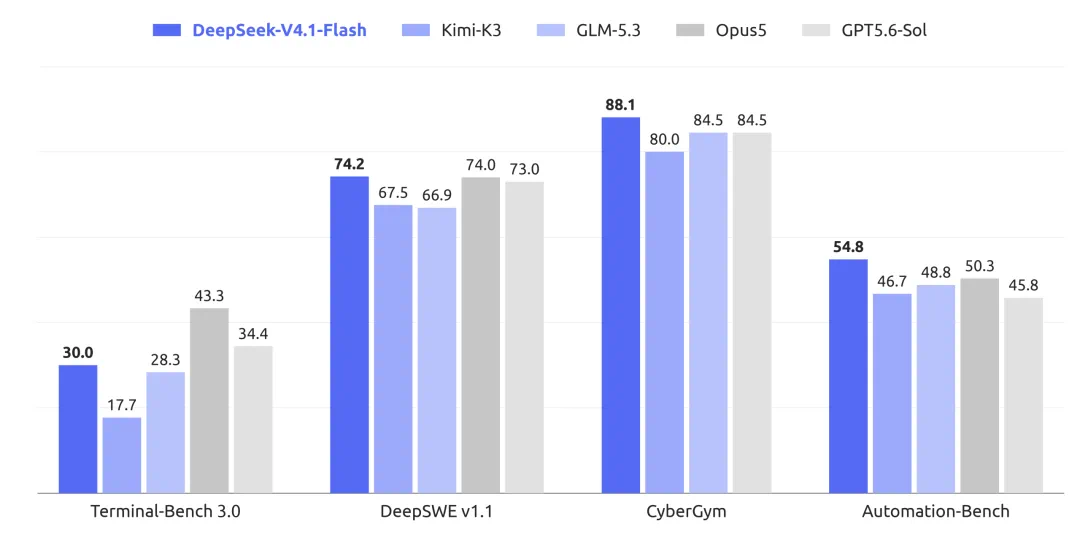
太快了。 周四上午,DeepSeek V4.1 Flash 正式在网页、App 和 API 端全面上线。 据官方披露,V4.1 Flash 在性能、响应速度、效率等核心指标上已全面超越 V4 Pro,且采用了新架构并原生支持多模态。 具体来讲,V4.1 Flash 是一款总参数规模达 552B 的 MoE 模型。它 采用全新的 Causal-Encoder-Decoder 架构 ,并对输入与输出采用非对称计算设计:输入侧仅激活 8B 参数,输出侧激活 16B 参数,因此在保持大模型容量的同时,大幅降低了实际推理成本。 除了架构上的调整,V4.1 Flash 还引入了新的预训练方法,并进行了更大规模的强化学习后训练。最终,它在多项基准测试中实现了性能提升, 整体智能水平超过大批当前旗舰模型 ,在性能、效率与成本之间取得了更好的平衡。 模型开源链接: https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash 论文链接: https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash/blob/main/DeepSeek_V41_Tech_Report.pdf 从下图官方展示的基准结果来看, V4.1 Flash 在软件工程、网络安全环境和自动化任务等测试中表现较强 。 在 DeepSWE v1.1、CyberGym 和 Automation-Bench 上,它均取得图中最高分,其中 DeepSWE 仅以 0.2 分小幅领先 Opus 5;但在 Terminal-Bench 3.0 上,V4.1 Flash 的 30.0 分明显低于 Opus 5 的 43.3 分和 GPT-5.6 Sol 的 34.4 分。因此,整体来看,这组结果说明 V4.1 Flash 在部分 Coding 和 Agent 类任务上具备较强竞争力,但并非所有基准都占优。 下图为更全面的基准测试结果,可以看到,在 Coding、软件工程和 Agent 任务上明显提升之外,V4.1 Flash 在 GPQA Diamond、Terminal-Bench 3.0/4.0、ProgramBench 等项目上仍跟 GPT-5.6 Sol 或 Claude Opus 5 等顶级闭源模型存在差距。 DeepSeek
DeepSeek News
🚀 Introducing DeepSeek-V4.1-Flash: smarter, faster, more efficient. 🔹 Introducing the smallest model in our new architecture family, with native visual understanding. 🔹 Designed for greater capability, faster inference, higher throughput, and scaling to larger models. 🧠 Asymmetric architecture. More intelligence, less cost. 🔹 552B-parameter MoE. 🔹 New Causal Encoder–Decoder architecture: just 8B active parameters for input, 16B for output. 🔹 New pre-training methods + larger-scale RL post-training deliver benchmark results ahead of flagship models, including DeepSeek-V4-Pro. 💾 Smaller KV cache. Bigger savings. Compared with the previous generation, V4.1-Flash's KV cache needs just: 🔹 1/4 the HBM 🔹 1/8 the SSD storage Cache-hit charges often account for a large share of agent costs. Compressing the cache cuts those costs significantly. ⚡ V4.1-Flash is now live on the DeepSeek API with native multimodal support. Set your model to deepseek-flash . 🔹 V4-Flash & V4-Flash-Vision-E

Techmeme
Reuters : DeepSeek debuts DeepSeek-V4.1-Flash, its smallest model built on a new Causal Encoder-Decoder architecture, with 552B backbone parameters and 1M-token context — Chinese artificial intelligence startup DeepSeek on Thursday launched DeepSeek-V4.1-Flash, which the company said is the smallest model …

Hacker Newsthatxliner
编辑|Panda 前两天, DeepSeek V4.1 Flash 正式上线 ,又快又强,引发了广泛关注和测试热潮。 比如著名测试机构 Artificial Analysis 对 V4.1 Flash 进行了非常充分的测试后,给出了 40 分的指数评分,超过了 DeepSeek 家参数量大得多的 V4 Pro。 当然,这并不意外,毕竟 DeepSeek 自己也得出了这一结论,并表示会让 V4 Pro 下线并将相关请求直接路由的 V4.1 Flash。顺带一提,DeepSeek 已经连续两次修改决定,先是延迟下线 V4 Pro: 然后又放弃下线 V4 Pro 并继续提供 API 调用服务: 此外,Artificial Analysis 的系统评测中还有另一些看点: DeepSeek V4.1 Flash 在 智能体能力 和 长上下文推理 方面进步明显。 DeepSeek V4.1 Flash 以 69% 在 AutomationBench-AA 上排名第一 ,与 GPT-6 Astra(69%)持平,略高于 Grok 4.6(67%)。 DeepSeek V4.1 Flash 是其测得的 冗长度最高的模型之一 ,每个 Intelligence Index 任务 89k Tokens。 尽管如此冗长,DeepSeek V4.1 Flash 每个 Intelligence Index 任务仍仅花费 0.27 美元。这主要得益于其 低定价 。 Sebastian Raschka 甚至认为 DeepSeek V4.1 Flash 创新之大,应该叫它 DeepSeek V5。 那么,DeepSeek V4.1 Flash 究竟是如何做到的呢?如何以 552B 参数的小肥鱼超越了 Pro 的 1.6T 参数大肥鱼?下面我们就基于其官方技术报告来进行一番解读。 报告地址:https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash/blob/main/DeepSeek_V41_Tech_Report.pdf 这是一篇围绕 KV 缓存写的报告 先看技术报告的标题:「DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression」。 推进 KV 缓存压缩之极限 。翻完架构章节
Related stories
Mistral Large 4 preview: 1T-parameter open-weight model, weights due Oct 27
Mistral AI released a public preview of Mistral Large 4 (ML4), a 1-trillion-parameter multimodal model with 49 billion active parameters, trained on 3,800 Nvidia Grace Blackwell GPUs in its European data centers. The open weights are promised by October 27. Early benchmarks show an Artificial Analysis Intelligence Index score of 38, comparable to DeepSeek V4.1 Flash, and the model is claimed to top any open model from the US or Europe.
10 reports · 5 sources2033 points · 1210 comments
MiniMax M3.1-Flash-Preview matches Claude Opus 5.5 front-end feats
On September 28, MiniMax released M3.1-Flash-Preview, the latest M-series model with million-token context and native multimodality, available in MiniMax Code and via API subscription. Users found it can replicate front-end generation feats of Claude Opus 5.5, such as a gacha game page with full character panels, without multiple attempts.
1 reports · 1 sources
Microsoft launches MAI-Transcribe-2-Streaming and two new voice models
Microsoft AI announced the launch of MAI-Transcribe-2-Streaming, a low-latency real-time transcription model, alongside two new voice models, MAI-Voice-2.1 and MAI-Voice-2.1-Flash. The models are positioned for accurate, fast, and low-cost audio understanding and generation, targeting conversational voice agents.
1 reports · 1 sources
DeepSeek open-sources Ascend infrastructure components, partners with Huawei
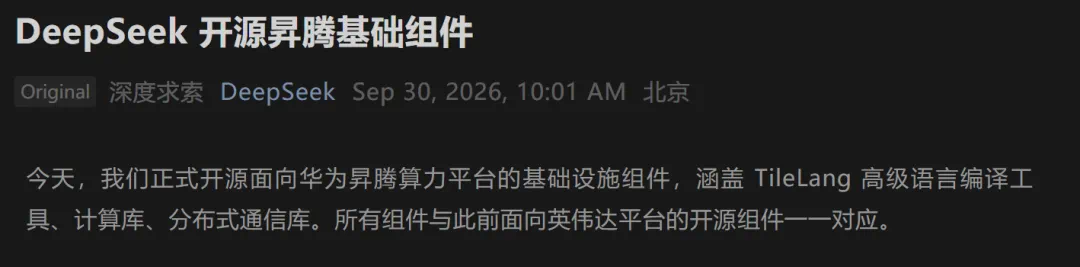
DeepSeek announced on September 30 the open-sourcing of infrastructure components for Huawei's Ascend platform, including the TileLang compiler, high-performance computing libraries (DeepGEMM, FlashMLA, TileKernels, DeepSelect), and the DeepEP distributed communication library. Huawei also open-sourced joint innovations around Ascend 950 and supernodes in the CANN community, covering deployment, training, KV cache pooling, and Agentic RL. The move aims to build an efficient AI chip software ecosystem with Huawei, providing developers with tools corresponding to those previously released for GPU platforms.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe