DeepSeek begins testing V4.1 Flash with new structure, native multimodal support
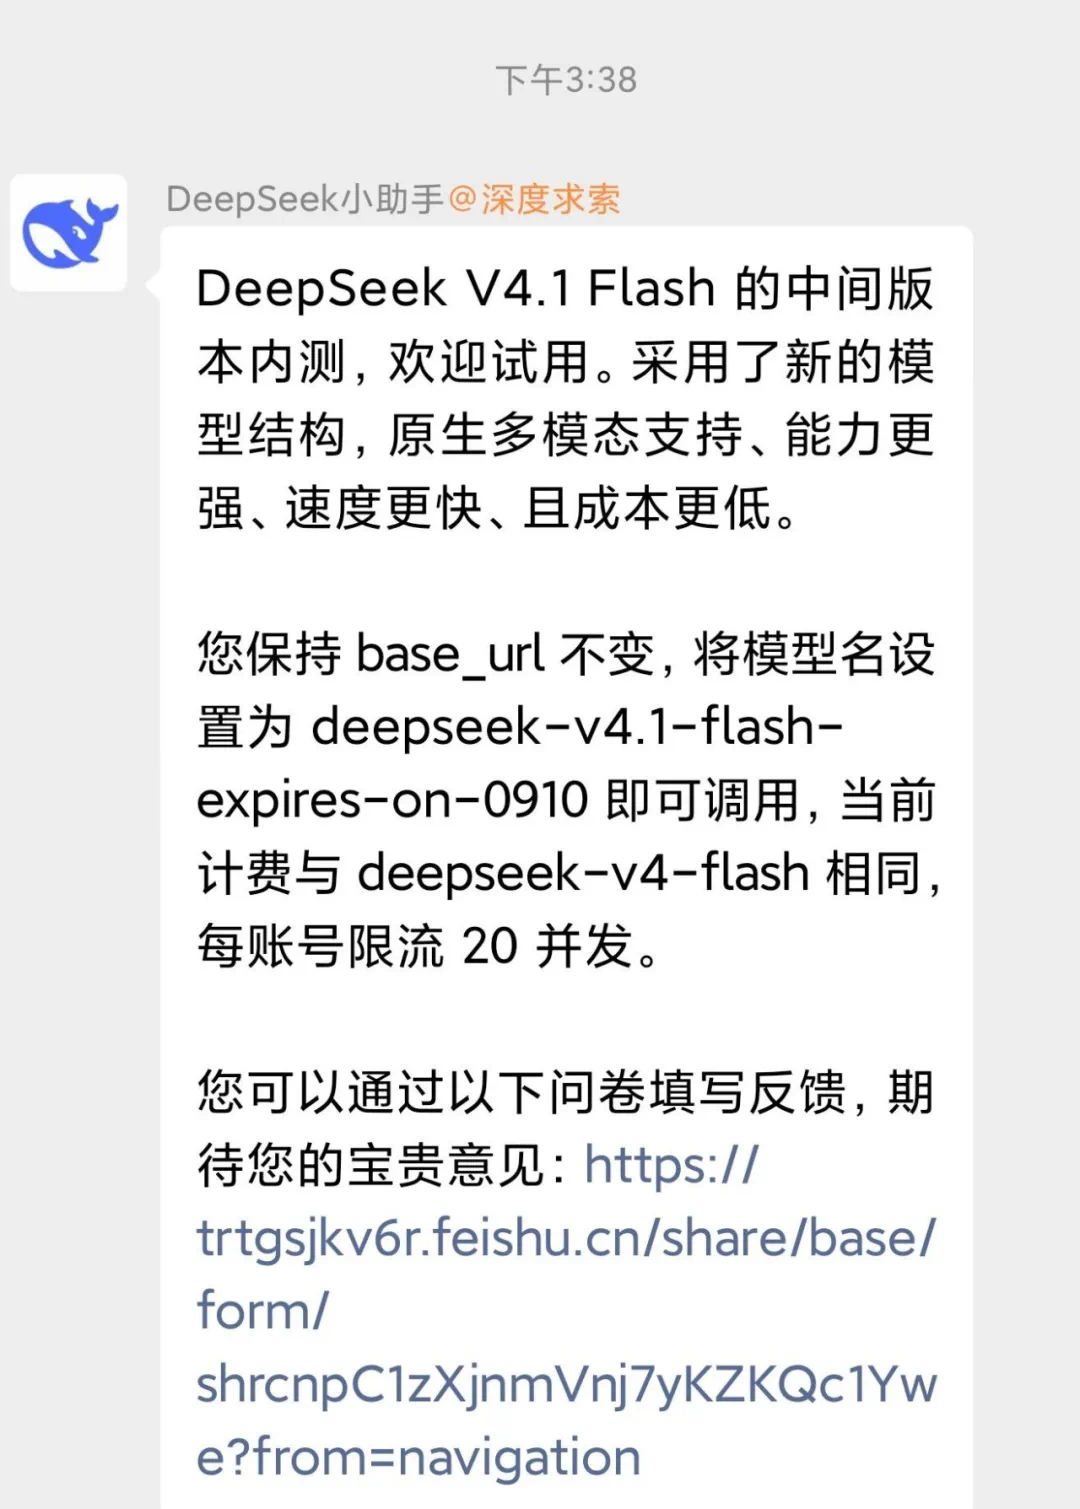
DeepSeek has begun internal testing of DeepSeek V4.1 Flash, a model with a new structure that offers faster speeds and native multimodal support. API users can access it by adding the model name deepseek-v4.1-flash-expires-on-0910 with existing credentials. Early community tests show end-to-end speed improvements of roughly 3.9 to 6 times over V4-Flash-Vision-Exp in tasks like long-context retrieval and code generation.
Coverage timeline
机器之心机器之心
9 月的大模型会战,DeepSeek 应战了。 今天下午 3 点,DeepSeek 官方社区突然传来消息,DeepSeek V4.1 Flash 直接开始测试。 说是内测,不过对于使用 API 服务的用户来说,没有什么特殊的限制门槛,在现有 DeepSeek 服务商下 手动添加模型:deepseek-v4.1-flash-expires-on-0910,保留原来的 API Key 和 base_url,再在新对话中选择它,就能直接用了 。 最近,「不加班」的 DeepSeek 也被全球的大模型浪潮裹挟着猛猛上新。此前 7 月底上线的 DeepSeek V4-Flash-0731 保持了原有模型结构,仅重新进行了后训练就取得了能力的大幅提升;8 月 13 日,DeepSeek V4 Pro 正式版与 DeepSeek Harness 共同问世,开始尝试通过布局生态来实现能力的最大化;8 月 21 日公开的 deepseek-v4-flash-vision-exp 则支持图文混合输入,结束了 DeepSeek 大模型没法看的历史。 值得注意的是,这次 V4.1 Flash 并不是一次简单的后训练更新。 V4-Flash-Vision-Exp 的一个官方示例:在 Agent 框架下生成商业定制西藏自驾游 PPT。 DeepSeek 明确提到 V4.1 Flash 使用了「新的模型结构」 ,不免让人有了更多期待。 目前因为只是内测,官方给出的信息不多。看起来,官方宣称的新结构虽然不至于是对于模型架构的推翻,但可改的还有注意力机制、专家网络、视觉模块等等。不过既然有了「原生多模态」,我们可以期待像之前 v4-flash-vision-exp 那样,新模型能在大部分任务能力上都有进一步的提升。 另一部分有趣的在于「速度更快」,社区里有人已经获得了 400 token/s 的水平,比 Gemini 3.8 Flash 还要快。 还有用户给出了更直观的对比:在相同任务下,V4.1 Flash 相比 V4-Flash-Vision-Exp,49k 长上下文检索快 5.2 倍、SVG 代码生成快 6 倍。 网友自测显示,V4.1 Flash 在长上下文检索、代码生成、算法题等任务中的端到端速度较 V4-Flash-Vision-Exp 提升约 3.9~6 倍。图源:X 用户 @NFT_
Related stories
DeepSeek mHC residual streams collapse: deep layers near identity, weak paths removable
A paper analyzing DeepSeek's mHC architecture finds that its four residual streams are not uniformly used: read/write weights concentrate on about two streams, and residual mixing matrices in layers 22–42 approach the identity matrix. Intervention experiments show that removing the weakest read/write paths lowers average task scores by at most 0.38 percentage points, and replacing deep-layer mixing matrices with identity leaves scores essentially unchanged (84.22 to 84.26), while fixing shallow layers to their average matrix costs only 0.25 points.
1 reports · 1 sources
DeepSeek quietly releases official desktop version of Harness GUI agent tool
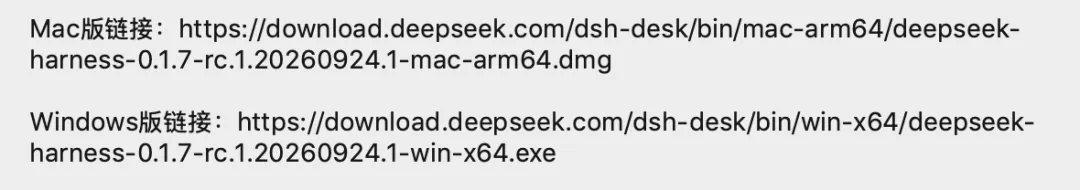
DeepSeek has released an official desktop version of its Harness GUI agent tool without a formal announcement, as confirmed by a hands-on test. The app lets users log in with a DeepSeek account or API key, select a local workspace, and assign tasks across modes like standard, PTC, minimal, and creative. It includes six built-in plugins, two of which are experimental, and emphasizes an 'Everything is a Plugin' architecture for extensibility.
DeepSeek releases V4.1-Flash, 552B-parameter MoE with asymmetric architecture
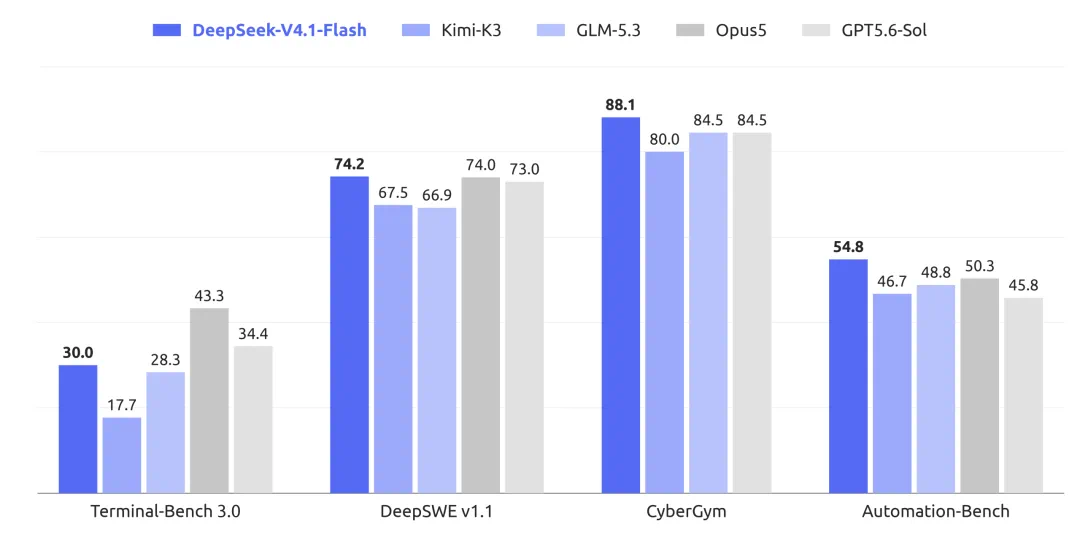
DeepSeek released DeepSeek-V4.1-Flash, a 552B-parameter mixture-of-experts model with a new Causal Encoder-Decoder architecture, now live on web, app, and API with native multimodal support. The model activates only 8B parameters for input and 16B for output, and its KV cache requires 1/4 the HBM and 1/8 the SSD storage of the previous generation. Early benchmarks show it outperforming V4 Pro overall, though it trails top closed models on some tests like Terminal-Bench 3.0.
6 reports · 4 sources1006 points · 574 comments
DeepSeek to release V4.1 Flash on Sept 10, claims it surpasses V4 Pro
DeepSeek announced plans to officially release its V4.1 Flash model around September 10, 2026 (Beijing Time), claiming it surpasses V4 Pro across all key metrics including performance, cost, speed, and task completion time. After the launch and before V4.1 Pro's release, all Pro model requests will be routed to V4.1 Flash and billed at Flash's price. Flash series pricing will be adjusted from 12:00 Beijing Time on September 10, with off-peak rates of $0.003 for input cache hits, $0.15 for input cache misses, and $0.6 for output; peak-hour prices will be double.
1 reports · 1 sources417 points · 218 comments
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe