vLLM Introduces REINFORCE Zero for Bit-Aligned Async RL on DeepSeek-V4.1-Flash and Kimi K3.1
The vLLM blog announced REINFORCE Zero, an asynchronous reinforcement learning method that aligns rollout and training kernels bit-for-bit to eliminate mismatch, using unclipped importance sampling to correct stale-weight lag. The approach is applied to DeepSeek-V4.1-Flash, Kimi K3.1, and AMD MI355X.
Coverage timeline
vLLM BlogAo Shen (Inferact), Jian Hu (NVIDIA Research), Yan Bai (NVIDIA DevTech), Shekhar Pandey (AMD), and the REINFORCE Zero authors
Asynchronous RL trains on stale weights. Align rollout and training kernels bit for bit, and unclipped importance sampling corrects that lag. Plus zero-mismatch RL for DeepSeek-V4.1-Flash, Kimi K3.1 and AMD MI355X.
Related stories
vLLM Adds Day-0 Support for Kimi K3.1 Pro with Sparse Attention and Packed KV Cache
vLLM announced day-0 support for Kimi K3.1 Pro, enabling sparse attention on a KDA hybrid, a packed KV cache with FP8 or NVFP4 latents and MXFP4 index keys, token-sharded prefill, decode context parallelism, and fused low-latency decode. This integration allows users to run the model immediately upon release with optimized performance.
vLLM Serves DeepSeek-V4.1-Flash at 954K Tokens/s per GPU on GB300 NVL72
vLLM's blog reports that using P/D disaggregation and Wide-EP on a GB300 NVL72 rack, it serves DeepSeek-V4.1-Flash on SemiAnalysis AgentX at 954K tokens/s per GPU, matching DeepInfer's performance. This result is 7.9x the aggregated single-node result, demonstrating significant scaling.
MiniMax unveils M3.1 Flash, claiming top agent scores and low cost
MiniMax released M3.1 Flash, the official version of the previously anonymous Space Bunny model, claiming a generational leap in agentic tasks, coding, computer use, and cybersecurity. The model scores 29.6% on Agents' Last Exam (ALE), the top for Chinese models, with pricing at 1 yuan per million input tokens and 4 yuan per million output tokens. Weights are due October 23, with day-0 support from vLLM on Blackwell, Rubin, and AMD MI350 GPUs.

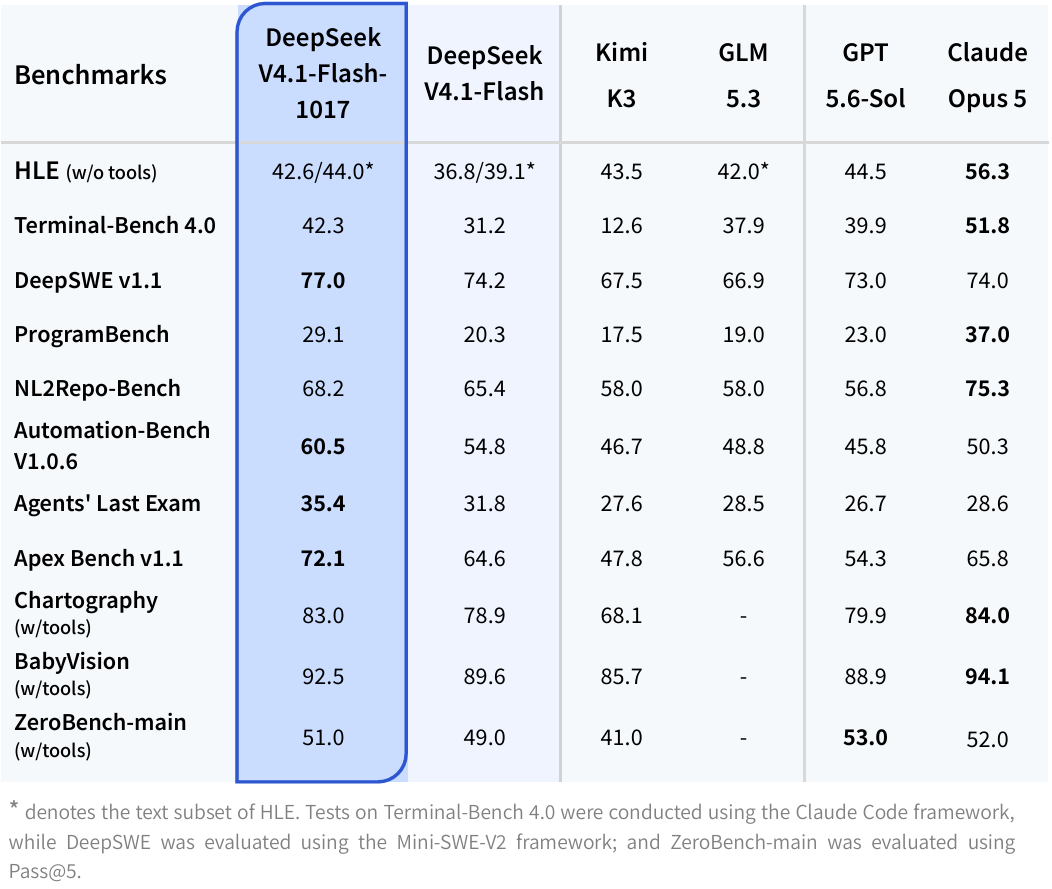
DeepSeek releases V4.1-Flash-1017 open-weight model with faster, cheaper agent tasks
DeepSeek released V4.1-Flash-1017, an open-weight model checkpoint with 763B parameters, now live on its website, app, and API. The update claims stronger benchmark performance, faster task completion, and shorter outputs than its predecessor, achieved via reinforcement learning with self-feedback for end-to-end project development. DeepSeek also opened its Search & Fetch APIs to everyone, priced at $0.75 per 1000 successful requests, and requires DeepSeek Harness v0.2.1-rc.1 or later for optimal use.
9 reports · 6 sources955 points · 717 comments
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe