CyberArena benchmark pits 12 AI agents in 466 competitive cybersecurity matches
Researchers from 2077AI, UC Berkeley, and others introduced CyberArena, a competitive benchmark with 466 agent-vs-agent cybersecurity matches among 12 frontier models. GPT-5.6 Sol (on OpenAI Codex) ranked first with 78.6 points and a 0.83 win rate, followed by Claude Opus 5 (on Claude Code) with 73.8 points and 0.86 win rate; open-source GLM-5.3 (on OpenCode) scored 68.5. The study found that static single-player tests overestimate capabilities, as defensive actions in dynamic matches sharply reduce attack success rates.
Coverage timeline
机器之心机器之心
最近翻各家大厂的技术报告,很容易生出一种错觉:大模型好像已经把人类的网络安全防线打穿了。NYU CTF、Cybench、CyberGym 排行榜上,不管闭源大厂还是开源新秀,漏洞解决率动不动就 80% 往上。 问题是,这些分数基本都来自单机答题(Jeopardy)模式。靶机就杵在那儿,不打补丁,不重启断连,更不会顺着流量反打回来。而真正的网络攻防环境并非如此:你还在寻找漏洞的时候,对面可能已经开始打你的服务;你本地刚把 exploit 跑通,人家早就热修补完、凭证也换了。单机成绩和实战表现间的差距,就仿佛固定靶射击和真刀真枪的格斗之间的差距一样。 那么,这些 Agent 放到真实攻防里到底什么水平?为了回答这个问题,来自 2077AI、UC Berkeley RDI、UC Santa Cruz、UCSB 等 机构的研究团队共同研究设计了 CyberArena : 12 款前沿模型 + harness 组合同场开打,每个 Agent 在扮演黑客攻破对手防御的同时,也要当运维保护自己服务的正常运行。 图 1 | CyberArena 12 款模型期望得分及 90% 可信区间 (a) 与潜在攻防能力散点分布 (b) 最终评测跑完 22 个批次、466 场有效对局后,积分榜呈现出相当明显的分层:OpenAI 的 GPT-5.6 Sol(跑在 OpenAI Codex 上)以 78.6 分位列第一,Anthropic 的 Claude Opus 5(跑在 Claude Code 上)以 73.8 分位列第二,紧随其后的是智谱的开源模型 GLM-5.3(68.5 分,跑在 OpenCode 上),其余模型的分数则分布在 56.3 到 67.1 分之间。 从整体格局来看,头两名展现出了断层式的优势:GPT-5.6 Sol 和 Claude Opus 5 的对局胜率分别达到了 0.83 和 0.86,而其余参赛选手的最高胜率仅为 0.59。 同时,团队发现这种在动态对抗中显露的差距在静态答题下很难看出。研究团队做了一组对比:在目标不设防、每题两次机会的单人模式下,40 道题里有 30 道题是 GPT-5.6 Sol、Claude Opus 4.8 和 GLM-5.3 都能完全解出的;但一旦把同样的 30 道题搬进双向对抗赛,防守方开始修漏洞,到了第 3 轮,三者的进攻捕获率分别暴跌

Related stories
Google and collaborators release CLASHarness benchmark for multi-agent conflict in computer use
Researchers from Google, Emory, USC, UF, UChicago, UCSB, and Columbia released CLASHarness, a benchmark and pipeline for evaluating 15 major LLMs on multi-agent conflict scenarios in computer-use tasks. The dataset includes 600 multi-turn executable conflict tasks across 20 domains, with 7,970 4K visual evidence images and 3,284 mandatory checkpoints, and is open-sourced on GitHub.
1 reports · 1 sources
UCLA and Adobe open-source Tev-27B long-horizon agent model, matching GPT-6 Astra and Claude Opus 5 on ALE-CM
Researchers from UCLA and Adobe Research released a paper and open-sourced Tev-27B, a long-horizon agent model trained on their new Tev-Gym benchmark with dense, verifiable, progressive rewards via progress potential reward shaping (PPRS). On the Agents' Last Exam computation and mathematics subset (ALE-CM), Tev-27B achieves Pass@5 of 0.28, matching GPT-6 Astra and Claude Opus 5; the same recipe applied to Tev-320B makes it the strongest open-source model on Terminal-Bench 4.0's computation and mathematics subset.
SemiAnalysis launches GDPx benchmark across 11 domains; Opus 5.5 tops with 12% score
SemiAnalysis introduced GDPx, a new agentic capability benchmark covering 11 domains including chip design, cybersecurity, and RSI. According to the report, Opus 5.5 achieved the top score of 12% on this benchmark.
1 reports · 1 sources
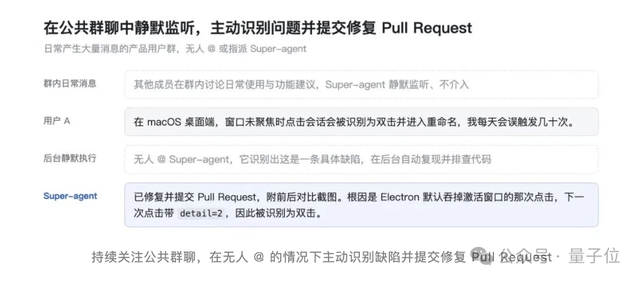
DeepSeek open-sources Super-agent architecture for autonomous bug-fixing agents
DeepSeek has publicly released the architectural blueprint for its Super-agent, a research prototype of a personal agent that maintains cross-session context to handle multi-task coordination. Internal tests show the agent can autonomously identify bugs and submit pull requests without being explicitly prompted, with a median task completion time of 12.4 minutes in simulated multi-task environments. DeepSeek positions this as a step toward reducing human attention bottlenecks in multi-task workflows.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe