Llama-modchip runs 284B DeepSeek model on 64GB RAM without GPU
A project called Llama-modchip demonstrates running a 284B-parameter DeepSeek model on a system with 64GB RAM and no GPU, using a modchip-like approach. The technique was discussed on Hacker News, highlighting a potential path for large-model inference on memory-constrained hardware.
Coverage timeline
Hacker Newsjoshcsimmons
Related stories
vLLM Serves DeepSeek-V4.1-Flash at 954K Tokens/s per GPU on GB300 NVL72
vLLM's blog reports that using P/D disaggregation and Wide-EP on a GB300 NVL72 rack, it serves DeepSeek-V4.1-Flash on SemiAnalysis AgentX at 954K tokens/s per GPU, matching DeepInfer's performance. This result is 7.9x the aggregated single-node result, demonstrating significant scaling.
1 reports · 1 sources
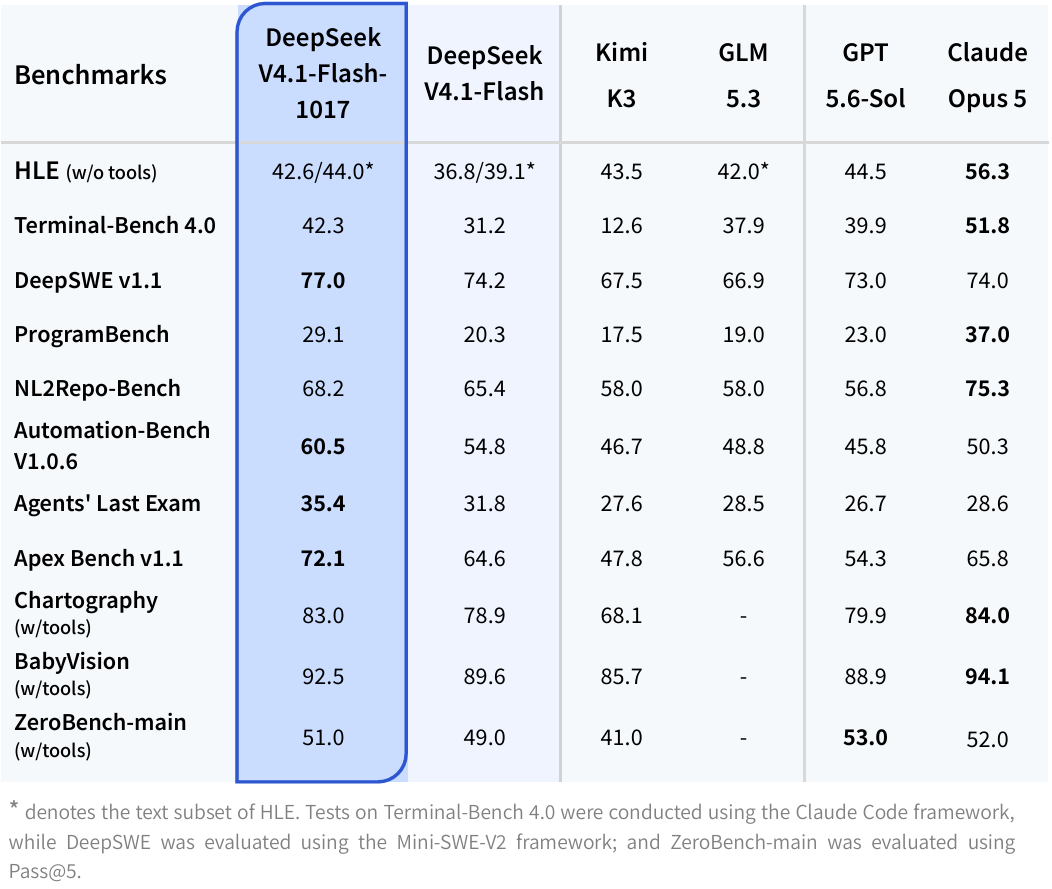
DeepSeek releases V4.1-Flash-1017 open-weight model with faster, cheaper agent tasks
DeepSeek released V4.1-Flash-1017, an open-weight model checkpoint with 763B parameters, now live on its website, app, and API. The update claims stronger benchmark performance, faster task completion, and shorter outputs than its predecessor, achieved via reinforcement learning with self-feedback for end-to-end project development. DeepSeek also opened its Search & Fetch APIs to everyone, priced at $0.75 per 1000 successful requests, and requires DeepSeek Harness v0.2.1-rc.1 or later for optimal use.
9 reports · 6 sources955 points · 717 comments
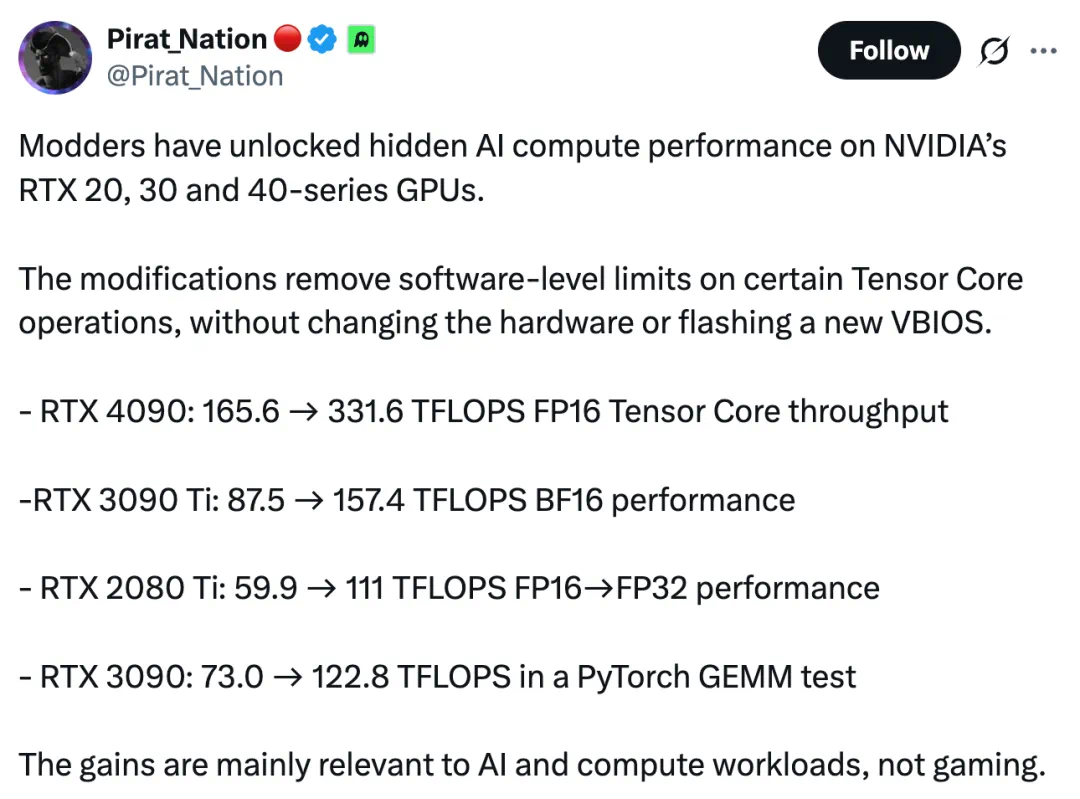
Open-source projects unlock hidden Tensor Core throughput on GeForce GPUs, doubling RTX 4090 performance
Open-source developers released projects on GitHub that unlock higher Tensor Core throughput on NVIDIA GeForce GPUs by modifying boot-time configuration, without driver swaps or BIOS flashes. Tests reportedly doubled the FP16/FP32 and BF16/FP32 throughput of an RTX 4090 from about 165 TFLOPS to over 330 TFLOPS, with gains also observed on RTX 3090 Ti, RTX 4070 Ti SUPER, and RTX 2080 Ti. The projects target RTX 20, 30, and 40 series, with some experiments done on Windows 11.
1 reports · 1 sources
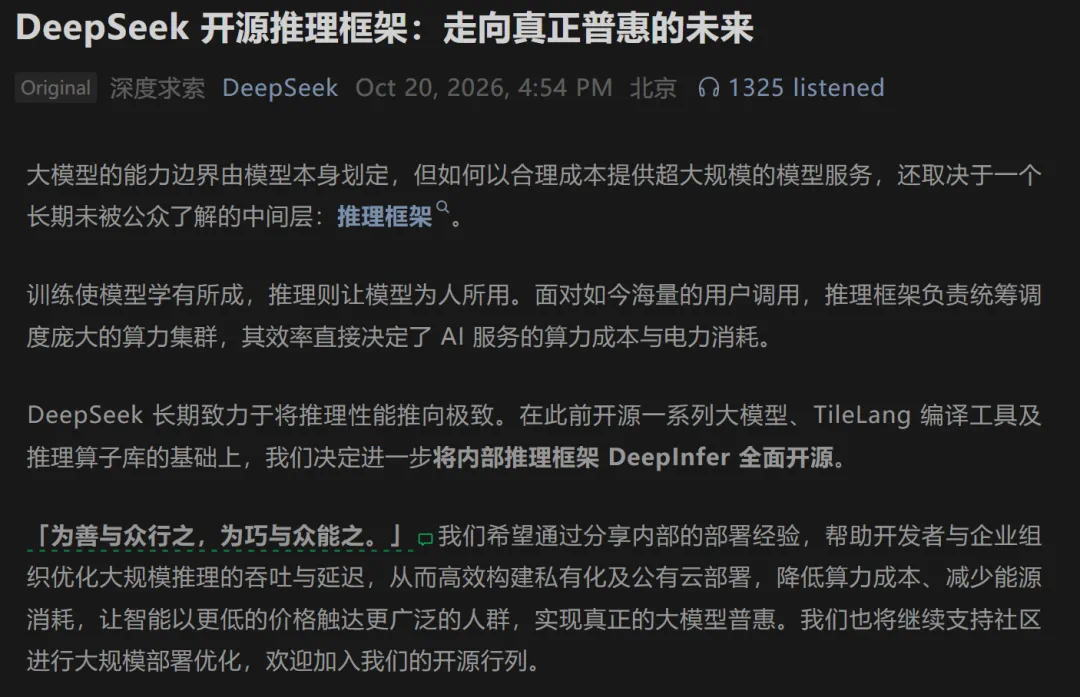
DeepSeek open-sources DeepInfer inference stack, reports 82% gross margin
DeepSeek released its internal inference framework DeepInfer under the Apache 2.0 license, along with the token codec component deepseek-recipe. The framework, which supports DeepSeek-V4.1-Flash and targets Nvidia SM100 GPUs and Huawei Ascend 950 NPUs, reportedly achieves a throughput of 155 trillion tokens per day per cluster, with API revenue of $38 per GPU-hour at off-peak pricing, implying a gross margin of 82% after GPU rental costs. The release sparked discussions about the profitability of AI inference services.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe