VAST open-sources EdenLive real-time world model, 24+ FPS at 720P on consumer GPU
VAST released and open-sourced EdenLive, a real-time world model that generates interactive visuals at over 24 FPS at 720P on a single Nvidia RTX 5090 consumer GPU. It supports arbitrary reference inputs, customizable art styles, and long-duration continuous generation, with end-to-end latency in the hundreds of milliseconds. The release includes model weights, inference code, a technical report, and an end-to-end demo.
Coverage timeline
量子位量子位
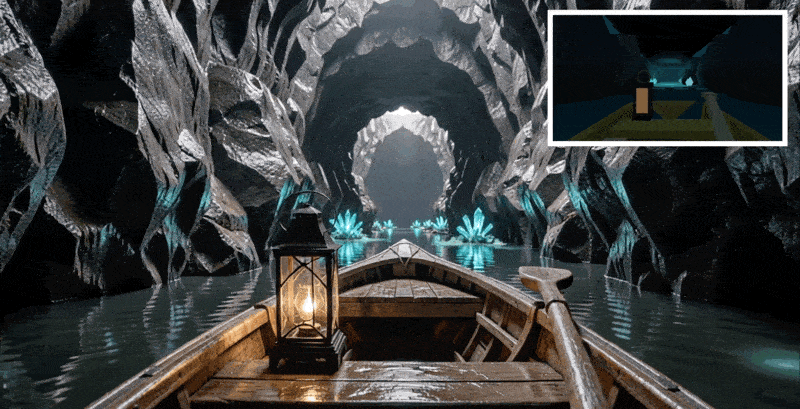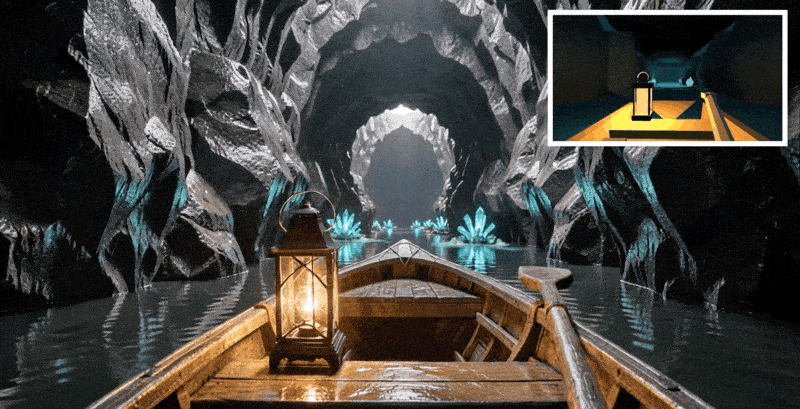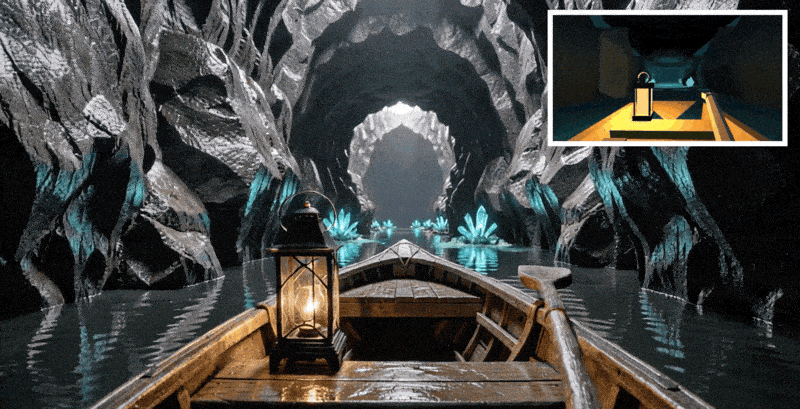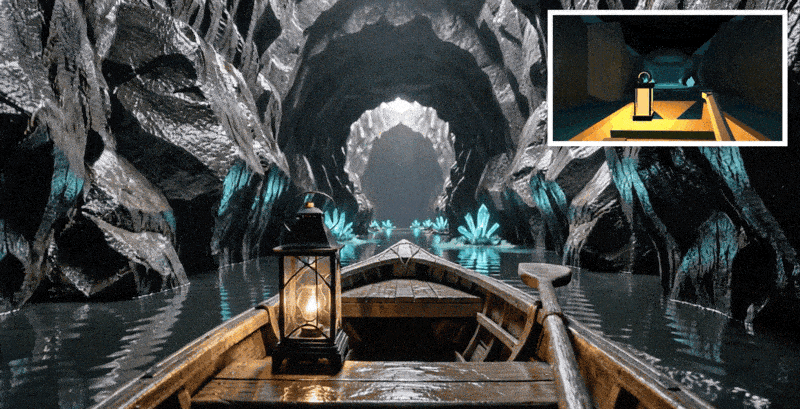
VAST开源实时世界模型EdenLive!单消费级显卡、720P超24FPS 听雨 2026-10-18 19:49:49 来源: 量子位 让人人都能自由创造并体验可交互世界 听雨 发自 凹非寺 量子位 | 公众号QbitAI VAST的世界模型,今天有了新成果。 实时世界模型 EdenLive ,正式发布并开源。 据VAST介绍,EdenLive首次实现了在实时生成的前提下,同时完成任意参考输入、任意画风生成和长时连续运行。 具体来说,给它简化场景或参考视频,再配上目标首帧和提示词,就能沿着参考的布局与运动,持续生成写实、二次元等不同画风的精细画面。 参考来源可以不同,生成画风可以指定,而这些变化都能在实时生成过程中呈现。 在单张消费级显卡Nvidia RTX 5090上、720P条件下,5B模型的生成速度 超过24FPS ,还能持续生成分钟级画面。 据VAST介绍,从用户输入操作到对应画面出现,这套系统目前的端到端延迟为百毫秒级。 画面持续变化的同时,交互规则和世界状态由上游交互系统维护。系统接收玩家操作、更新状态,EdenLive再根据对应的参考画面,将这些变化实时呈现出来。 最近,AI在3D场景搭建与交互创作上的能力,变得越来越直观。 GPT-6 Astra 就是一个典型例子:它已经能够在Blender里搭建房屋,再将其转入Unreal Engine 5,形成可以进入、漫游的场景。 当AI能够搭建场景、设计交互玩法,如何让这些内容获得精细且实时的视觉表现,也就成为接下来需要解决的问题。 在这样的背景下,一条技术路线逐渐成为行业共识: 由交互系统维护底层状态和运行规则,再由生成模型负责视觉渲染 。 而这套分工,VAST早在今年6月初就已经明确并对外发布成果。 当时公开的Project Eden研究预览,已将 「状态维护与视觉渲染解耦」 作为核心设计。 从时间上看,这一路线选择早于行业共识形成约3-4个月。 如今,EdenLive作为这条路线的阶段性成果发布,并开放模型权重和推理代码,同步公开技术报告与端到端Demo。 代码: https://github.com/VAST-AI-Research/EdenLive 项目主页: https://vast-eden.ai/?p=edenlive 技术报告: https://assets.vast-eden.ai/a
Related stories
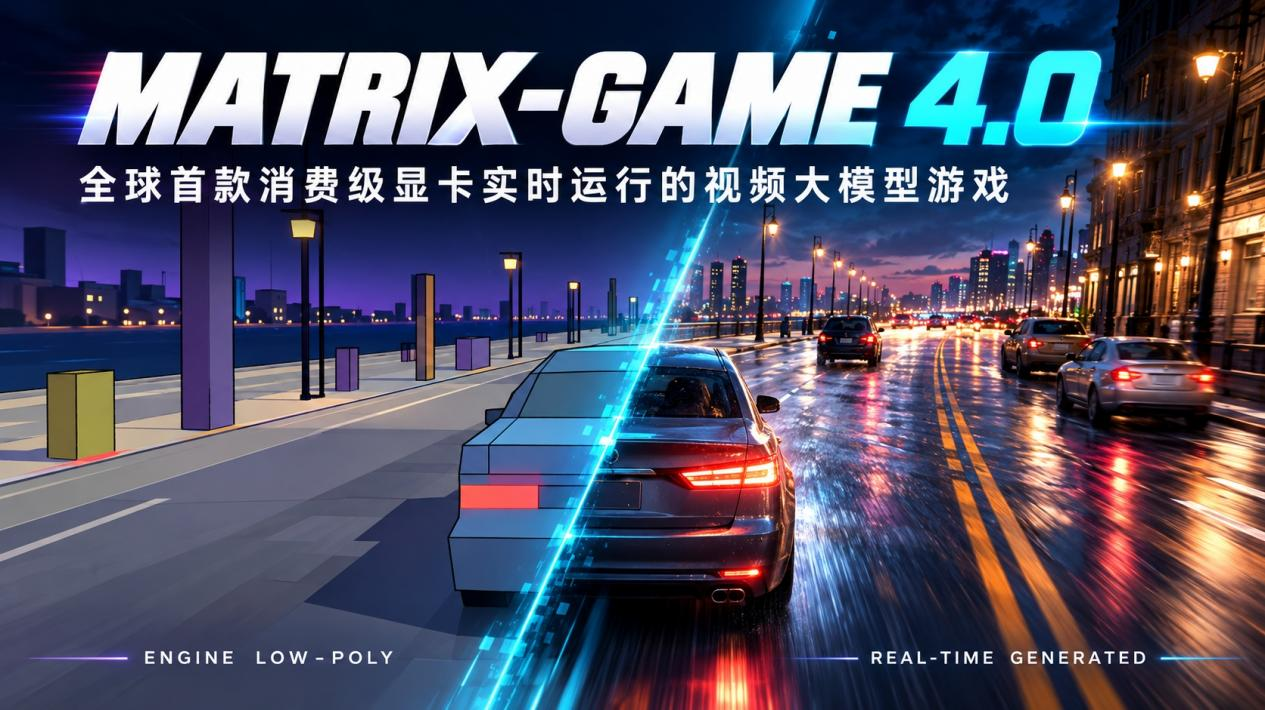
Kunlun Wanwei releases Matrix-Game 4.0, real-time 480p/60FPS game model on single RTX 5090
On October 15, 2026, Kunlun Wanwei released Matrix-Game 4.0, claiming it is the world's first video-model game running on a single consumer GPU. It delivers 480p, 60 FPS real-time gameplay on an NVIDIA RTX 5090 with end-to-end latency below 150 ms, and the code and technical report have been open-sourced.
1 reports · 1 sources
DeepSeek releases V4.1-Flash-1017 open-weight model with faster, cheaper performance
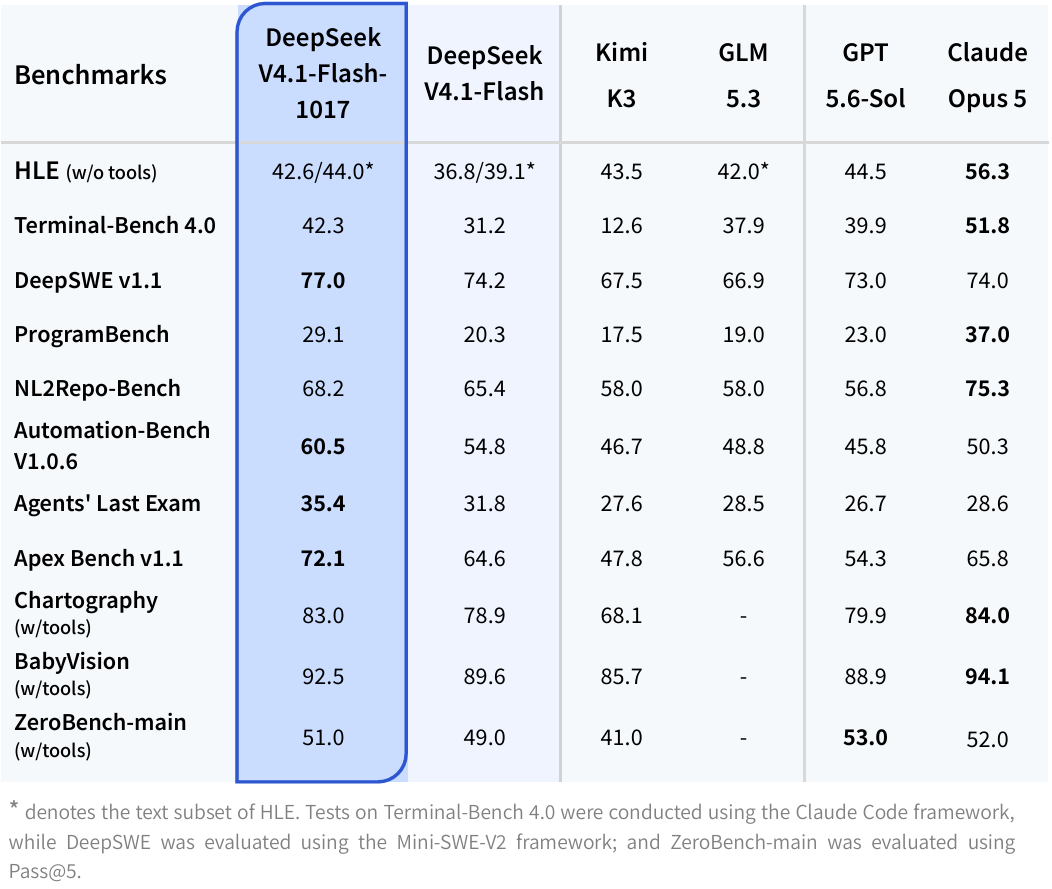
DeepSeek released V4.1-Flash-1017, an open-weight model checkpoint with 763B parameters, claiming stronger benchmark performance, faster task completion, and shorter outputs than its predecessor. The model is now live on the website, app, and API, and is optimized for DeepSeek Harness, Tencent CodeBuddy, and WorkBuddy. DeepSeek also opened its Search and Fetch APIs to everyone, priced at $0.75 per 1000 successful requests.
7 reports · 5 sources933 points · 703 comments
NVIDIA launches Nemotron 3.5 Super VL, 120B open model; vLLM adds Day 0 support
NVIDIA has launched Nemotron 3.5 Super VL, a 120B-parameter open model for enterprise agents, claiming it outperforms frontier models on specialized benchmarks. vLLM announced Day 0 support for the model, enabling multimodal agent workflows with image, document, and video understanding, OpenAI-compatible serving, and multi-token prediction.
Tsinghua, Infinigence-AI, SJTU Open-Source On-Device Inference Engine APXInf for Embodied Models
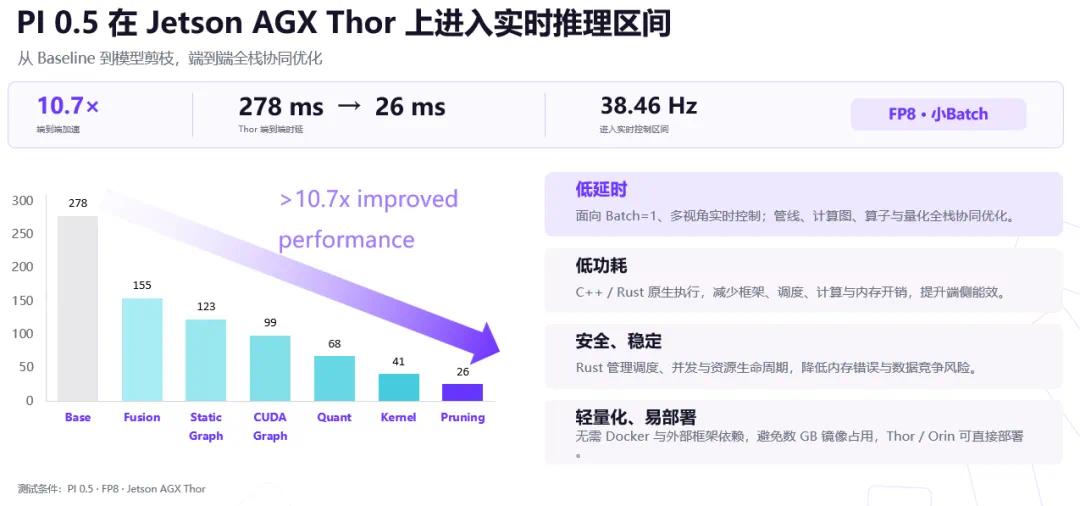
On September 15, Tsinghua University, Infinigence-AI, and Shanghai Jiao Tong University open-sourced APXInf, an on-device inference engine for embodied models. The engine reportedly achieves a 10.7x end-to-end speedup on robot hardware, reducing inference latency from 278ms to 26ms on Thor chips with FP8 configuration, enabling real-time control at 38.46Hz.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe