DeepSeek cuts V4-Flash API prices up to 60%, effective Sept 10
DeepSeek announced a price cut for its V4-Flash series API, with off-peak rates dropping up to 60% compared to the August 17 peak-period pricing. The new prices take effect at 12:00 Beijing time on September 10, with peak hours defined as Monday to Friday 9:00–12:00 and 14:00–18:00. The company also began internal testing of a V4.1 Flash intermediate model, named deepseek-v4.1-flash-expires-on-0910, with the same billing as V4 Flash.
Coverage timeline
机器之心机器之心
本周二晚间,DeepSeek 开放平台发布公告,计划再次调整大模型 API 定价,这次是喜闻乐见的降价。 闲时价格统一为:输入(缓存命中)0.02 元、输入(缓存未命中)1 元、输出 4 元(单位均为元 / 百万 token)。高峰时段价格仍为空闲时段的两倍,即缓存命中 0.04 元、缓存未命中 2 元、输出 8 元。 本次调整只涉及 V4-Flash 系列,定位更高的 V4-Pro 价格维持不变。新价格将在北京时间 9 月 10 日 12:00 生效。 官方同时明确,高峰时段为北京时间周一至周五 9:00–12:00、14:00–18:00,其余为空闲时段。 此前,DeepSeek 的涨价引发了人们的广泛讨论。官方给出的解释是为了更合理地调配资源,鼓励用户调整任务执行时间。外界则普遍认为是 DeepSeek V4 Flash 0731 性价比很高,吸引了全球用户的大量调用,以及 DeepSeek 缺乏足够算力。 纵向对比一下,8 月 17 日零时涨价前,Flash 是统一价 0.02 元(缓存命中)/ 1 元(未命中)/ 2 元(输出)。把这次的新价格摆进去: 也就是说,输入侧的两项价格回到了涨价前,输出仍是涨价前的两倍。若按高峰时段算差距则更大:新高峰价 0.04 / 2 / 8 元,对比涨价前的 0.02 / 1 / 2 元,分别是 2 倍、2 倍和 4 倍。 因此,用户能否真正回到过去「放开了用」的状态,取决于自身应用的三个变量:缓存命中率、输入输出比例、以及任务可错峰的程度。对长上下文、固定系统提示词、Agent 循环调用这类缓存命中率高的场景,降幅会很明显;对以生成输出为主的场景,感受有限。众所周知 DeepSeek API 的缓存命中率是比较高的,所以目前大家给出的反应比较乐观。 本次降价并非孤立事件,昨天下午,DeepSeek 在官方交流群宣布 V4.1 Flash 中间版本开启内测 :模型名为 deepseek-v4.1-flash-expires-on-0910,base_url 不变,每账号限流 20 并发,计费暂与 V4 Flash 相同。 新模型除了原生多模态、极快的推理速度之外,官方还表示通过架构的升级让成本更低。可见通过大模型本身的工程与技术优化,DeepSeek 一直在尝试改进推理成本的问题。 expires-on-0910 这个模型

Related stories
Nvidia Adds 64GB DGX Spark at $4,999, Priced Above 128GB Launch Model
Nvidia announced a 64GB unified-memory version of its DGX Spark mini PC, priced at $4,999. The price is $1,000 higher than the 128GB version at launch, a result of the ongoing memory shortage. The device is designed to run AI models locally.
1 reports · 1 sources
DeepSeek V4.1 Flash Scores Perfect on AI Hacking Benchmark for $4.65
Security firm reports that DeepSeek V4.1 Flash achieved code execution on all 11 vulnerable targets in its AI hacking benchmark, with all four fixed targets remaining secure, at a total cost of $4.65. A detailed review confirmed the results, finding six solutions followed the planned attack path and five successful routes not distinguished by the original scoring system. The review highlighted the model's strong hacking ability and identified areas where the benchmark needed stricter checks.
1 reports · 1 sources173 points · 67 comments
DeepSeek launches V4-Pro GA with agent upgrades, dynamic pricing
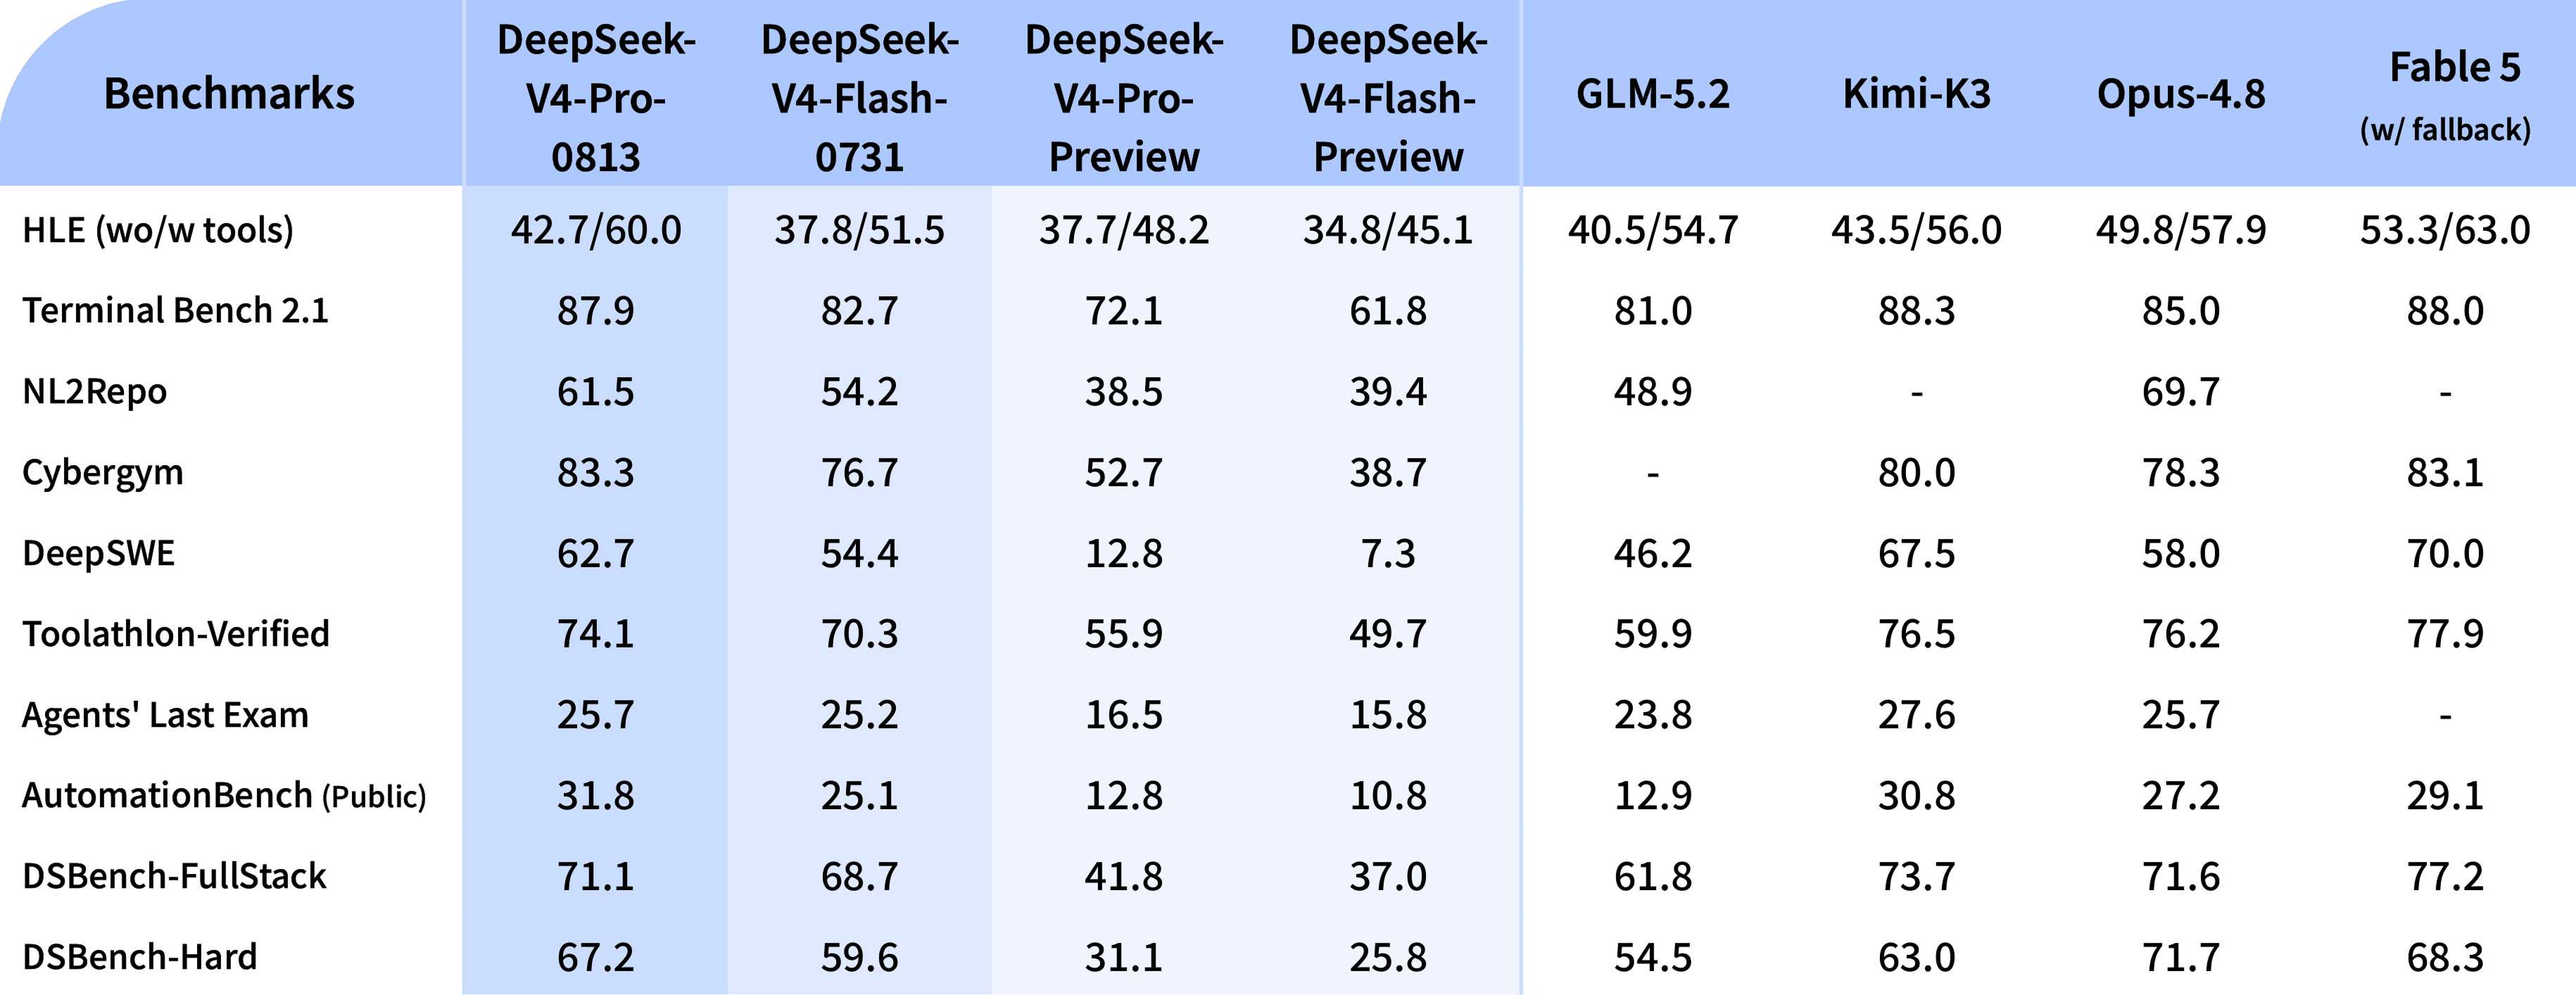
DeepSeek released the general availability version of its V4-Pro model, named DeepSeek-V4-Pro-0813, with agent-focused upgrades, flexible reasoning effort levels, and native OpenAI Responses API support for tools like Codex. The company also introduced peak/off-peak API pricing, with off-peak rates 50% lower, effective August 16, 2026, and raised prices for V4-Flash output tokens. The model is priced at $0.435 per million input tokens and $0.87 per million output tokens, with a 1M context window.
9 reports · 6 sources1031 points · 450 comments
DeepSeek releases V4.1-Flash, 552B-parameter MoE with asymmetric architecture
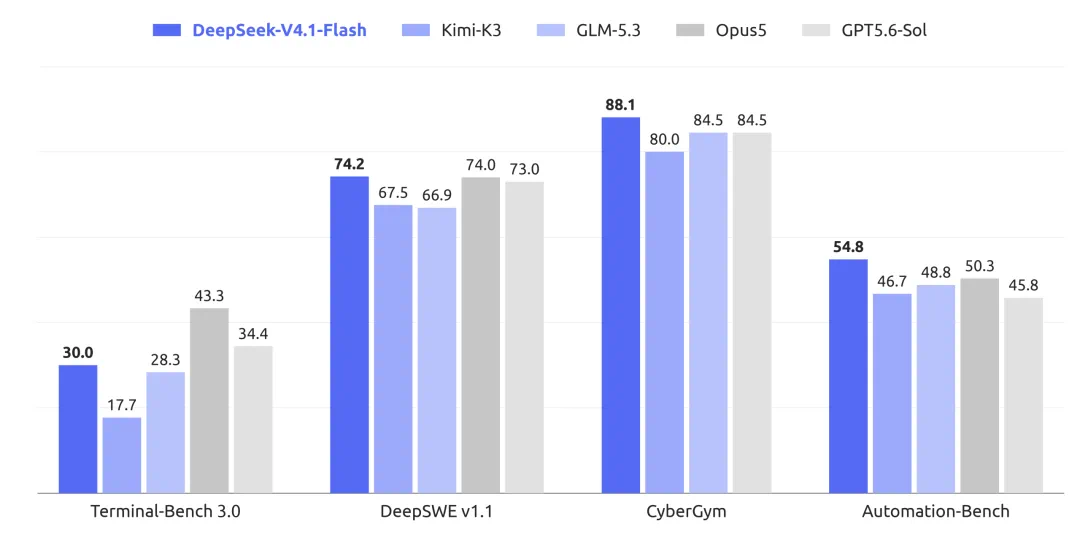
DeepSeek released DeepSeek-V4.1-Flash, a 552B-parameter mixture-of-experts model with a new Causal Encoder-Decoder architecture, now live on web, app, and API with native multimodal support. The model activates only 8B parameters for input and 16B for output, and its KV cache requires 1/4 the HBM and 1/8 the SSD storage of the previous generation. Early benchmarks show it outperforming V4 Pro overall, though it trails top closed models on some tests like Terminal-Bench 3.0.
6 reports · 4 sources1006 points · 574 comments
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe