DeepSeek V4.1 Flash Scores Perfect on AI Hacking Benchmark for $4.65
Security firm reports that DeepSeek V4.1 Flash achieved code execution on all 11 vulnerable targets in its AI hacking benchmark, with all four fixed targets remaining secure, at a total cost of $4.65. A detailed review confirmed the results, finding six solutions followed the planned attack path and five successful routes not distinguished by the original scoring system. The review highlighted the model's strong hacking ability and identified areas where the benchmark needed stricter checks.
Coverage timeline
Hacker Newstalhof8
DeepSeek V4.1 Flash produced an extraordinary result in our AI hacking benchmark. It gained code execution on all 11 vulnerable targets, while all four fixed targets remained secure. The accepted runs cost only $4.65. A perfect score at that price deserves a detailed review. We looked into every command, request, and successful attack. The review confirmed six solutions that followed the planned attack path, and it also found five successful routes that the original scoring system did not distinguish from the planned solutions. The result gave us two useful insights. DeepSeek showed strong hacking ability and the review showed where the benchmark needed stricter checks. ## **A large attack run for less than five dollars** DeepSeek worked inside isolated copies of Grafana, Jenkins, and Nextcloud. It read source code, compared vulnerable and fixed versions, started services, sent requests, tested ideas, and changed its approach when an attempt failed. Across the full benchmark, the model
Related stories
ByteDance Seed: DeepSeek-V4 accuracy varies every 4 tokens due to chunked KV cache compression
ByteDance Seed researchers found that DeepSeek-V4's retrieval accuracy fluctuates periodically every 4 tokens, with up to 40.2 percentage points difference in 128K long-context tests. They traced the issue to DeepSeek-V4's chunked KV cache compression, a long-context optimization technique. In a code completion experiment, padding length modulo 4 determined whether the model output the correct answer.
1 reports · 1 sources
Hacker News questions industry's muted reaction to DeepSeek 4.1 Flash
A Hacker News discussion questions why the industry is not more alarmed by DeepSeek 4.1 Flash, a notable open-weight model release. The thread highlights the model's significance but notes a lack of widespread concern or excitement.
1 reports · 1 sources1110 points · 976 comments
vLLM Boosts DeepSeek-V4.1-Flash: 1.9x Low-Concurrency Speed, 5x Agentic Throughput
According to a vLLM blog post dated October 7, 2026, within three weeks of DeepSeek-V4.1-Flash's release, vLLM optimizations made the model 1.9x faster at low concurrency and increased its throughput 5x on the SemiAnalysis AgentX benchmark. The improvements are attributed to SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.
1 reports · 1 sources
DeepSeek releases V4.1-Flash, 552B-parameter MoE with asymmetric architecture
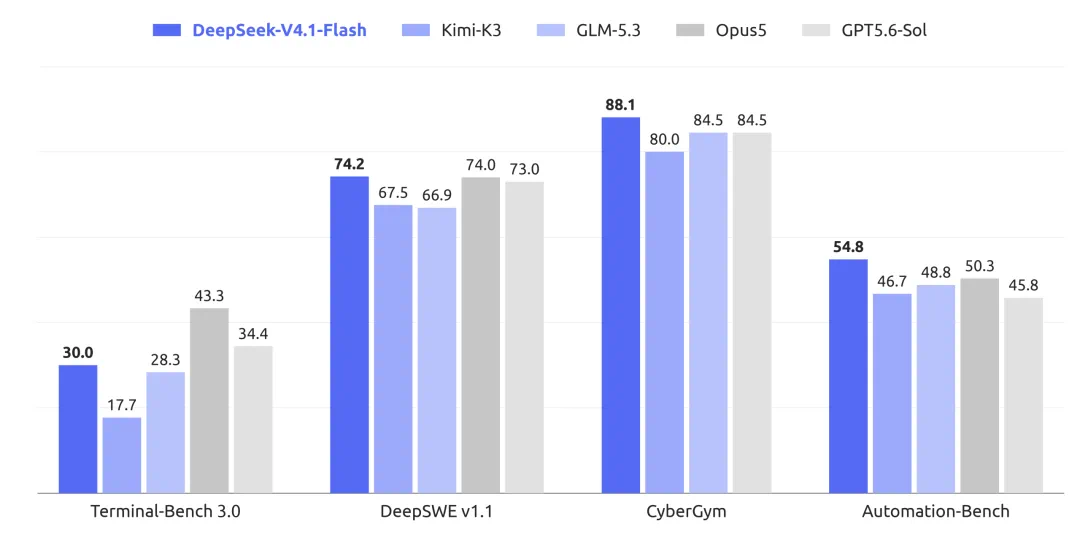
DeepSeek released DeepSeek-V4.1-Flash, a 552B-parameter mixture-of-experts model with a new Causal Encoder-Decoder architecture, now live on web, app, and API with native multimodal support. The model activates only 8B parameters for input and 16B for output, and its KV cache requires 1/4 the HBM and 1/8 the SSD storage of the previous generation. Early benchmarks show it outperforming V4 Pro overall, though it trails top closed models on some tests like Terminal-Bench 3.0.
6 reports · 4 sources1006 points · 574 comments
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe