Reflection AI unveils open-weight model Beam, claims lower compute and near-Qwen3.8-Max performance
Reflection AI, backed by Nvidia, has unveiled its first open-weight model, Beam, claiming it excels at coding and agentic tasks while using 3x-4x less compute than comparable models. The company says Beam's reasoning performance nears Qwen3.8-Max and rivals GLM-5.2 at lower inference compute, with weights expected to be released this month.
Coverage timeline
Techmeme
Semafor : Reflection unveils open-weight model Beam, saying it excels at coding and agentic tasks, uses 3x-4x less compute than comparable models, and nears Qwen3.8-Max — Reflection AI, the startup billing itself as America's answer to open-source Chinese AI, is releasing its first model, called Beam.

TechCrunch AIRebecca Bellan
Nvidia-backed Reflection AI unveils Beam, its first open-weight model, which it says rivals GLM-5.2 on reasoning with far less inference compute. Weights are due this month.
Related stories
NES 6502 CPU Emulator Runs Inside Qwen3.5-4B Model Weights
Drew Breunig built a working NES 6502 CPU emulator inside the weights of Qwen3.5-4B, inspired by qwenputer by Divyansh Agrawal. The emulator can run NES ROMs such as Super Mario Bros, albeit very slowly. Breunig shared the Opus 5.5 prompts used to create the system, which involved exploring chip and RAM emulation techniques and using NES CPU conformance tests.
2 reports · 2 sources293 points · 151 comments
Mistral releases open weights for 1T-parameter Le Chonk model
Mistral AI has released the open weights for Mistral Large 4, also known as Le Chonk, a 1-trillion-parameter multimodal model trained in Europe. The company claims it is the best open-weight model for coding and rivals top open models like GLM-5.3 on the Artificial Analysis Coding Agent Index. The model is now available on the Hugging Face platform, and Mistral says its open nature gives organizations control over cyber defenses that closed models cannot offer.
4 reports · 4 sources1709 points · 438 comments
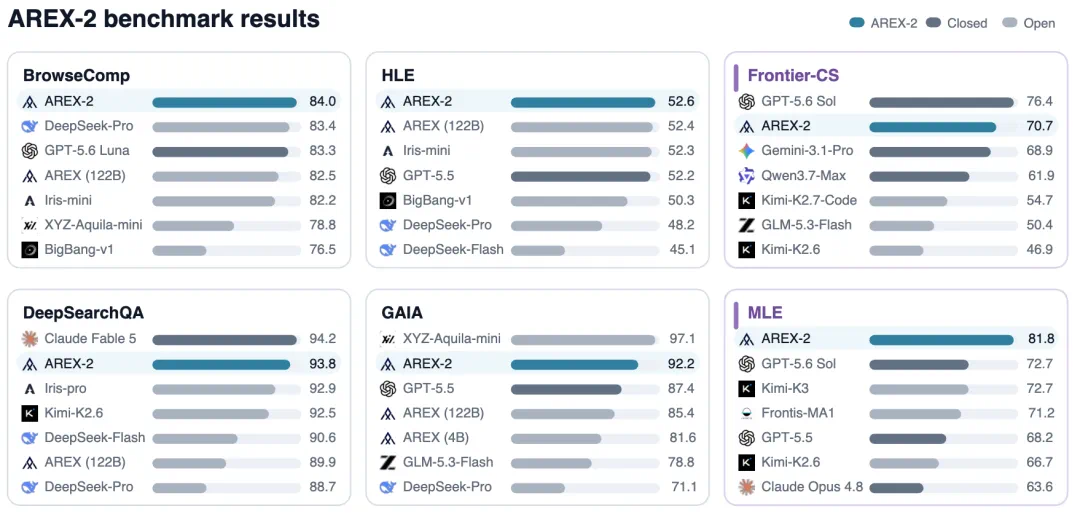
BAAI AREX-2: 27B model beats larger rivals on ML, algorithm benchmarks
The AREX research group, involving BAAI, USTC, and Renmin University, released AREX-2, a 27B-parameter model built on Qwen3.8-27B and trained on long-horizon reflection data for machine learning and algorithm programming. It outperforms larger models on MLE-bench Lite and Frontier-CS, and sets open-weight records on BrowseComp and HLE, suggesting that long-horizon reflection training can foster cross-domain self-improvement capabilities.
1 reports · 1 sources
ByteDance Seed's Recycler recycles hidden states to boost reasoning efficiency
ByteDance Seed introduces Recycler, a model architecture that recycles hidden states across decoding steps to improve reasoning efficiency with negligible overhead. The design, motivated by the observation that a multitoken prediction head with only ~2% of backbone parameters achieves loss comparable to a standalone model ~25% its size, feeds both token embeddings and previous hidden states through a lightweight adapter into the next step. Experiments show strong parameter efficiency, particularly in reasoning and mathematics.
1 reports · 1 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe