ToolSpace: Tool-Centric Environment Synthesis Framework Trains 744B Model to Match Claude Opus 5
Researchers from Renmin University, Fudan, and Shanghai Jiao Tong propose ToolSpace, a tool-centric framework for synthesizing cross-environment training data for long-horizon agents. It extracts tools from execution traces, builds tool composition graphs, and generates verifiable cross-environment tasks via state-aware random walks. Training with ToolSpace data improved a 744B model's composite benchmark score from 44.6 to 56.6, matching Claude Opus 5, and the team also built upgraded benchmarks AutomationBench Pro and τ³-Bench Banking Pro.
Coverage timeline
机器之心机器之心
给智能体造训练环境,一定要先从数据库开始吗?现有的环境合成方法通常以数据为中心,先生成数据库和业务场景,再据此构造工具与任务。但沿着这条路线, 工具接口和参数逻辑可能偏离真实定义,工具组合也可能缺少执行依据,任务往往局限于单个环境 。现实中的工作却需要跨越这些边界,要让智能体熟悉跨环境的工具调用,训练任务就需要覆盖不同环境之间的数据传递、状态衔接与工具编排。 为此,中国人民大学,复旦大学和上海交通大学的研究团队提出 ToolSpace,面向工具中心的跨环境智能体环境合成框架 。该方法包含两个核心环节。 (1) 工具空间探索 :从执行轨迹提取工具,构建工具组合图,并按工具关系组织环境与底层数据,使工具组合具备可追溯执行依据。 (2) 跨环境可验证任务合成 :沿工具图做状态感知随机游走,将走通的调用链转化为自然语言任务与验证脚本,并按难度与跨环境范围筛选可回放样本。 图 1 ToolSpace 总览。从工具及其执行依赖出发组织环境,合成跨环境任务,用于训练数据生成和 Pro 基准构建。(论文图 1) 下面的视频展示了 ToolSpace 的完整流程。 研究团队从训练与评测两方面验证: 七项长程工具基准全面提升 : ToolSpace 合成数据在训练后带来稳定提升。ToolSpace-744B-A40B 综合性能由 44.6 升至 56.6,与 Claude Opus 5 持平。 构建更具挑战的升级基准 : 构建 AutomationBench Pro 与 τ³-Bench Banking Pro,相比于标准版本更能检验智能体在更复杂工作流中的连续执行能力。 论文标题:ToolSpace: Scaling Tool-Centric Environment Synthesis for Long-Horizon Agents 论文链接:https://arxiv.org/pdf/2611.05036 项目主页:https://toolspace-agent.github.io/ 代码仓库:https://github.com/dongguanting/ToolSpace 模型合集: https://huggingface.co/collections/dongguanting/toolspace ToolSpace:将工具连成宇宙,按需合成环境! 一、工具空
Related stories
UCLA and Adobe open-source Tev-27B long-horizon agent model, matching GPT-6 Astra and Claude Opus 5 on ALE-CM
Researchers from UCLA and Adobe Research released a paper and open-sourced Tev-27B, a long-horizon agent model trained on their new Tev-Gym benchmark with dense, verifiable, progressive rewards via progress potential reward shaping (PPRS). On the Agents' Last Exam computation and mathematics subset (ALE-CM), Tev-27B achieves Pass@5 of 0.28, matching GPT-6 Astra and Claude Opus 5; the same recipe applied to Tev-320B makes it the strongest open-source model on Terminal-Bench 4.0's computation and mathematics subset.
1 reports · 1 sources
Renmin, Fudan Universities Propose CoworkOS for Persistent AI Coworkers
A joint team from Renmin University and Fudan University proposed CoworkOS, a system architecture for persistent, complex-task AI coworkers aligned with DeepSeek's Super Agent concept. It combines a three-layer collaboration architecture, shared application environments, and persistent work state with asynchronous execution. In tests across 12 real-world benchmarks and 6 delivery scenarios, CoworkOS performed comparably to DeepSeek Harness and Codex, and organized five iterative rounds of Qwen3.6-35B-A3B post-training, raising average scores from 33.19 to 42.95.
DiffuSpace releases open-source diffusion LLM Clover-35B-A3B-Preview
DiffuSpace, the startup with the largest funding round for diffusion language models, released the open-source diffusion model Clover-35B-A3B-Preview. The company claims it matches or surpasses autoregressive models of similar size on agentic coding and tool-use benchmarks while achieving faster generation, demonstrating that high speed and high performance can coexist.

Tencent unveils Hunyuan Hy4: 770B-parameter open-weight model with native vision and computer-use
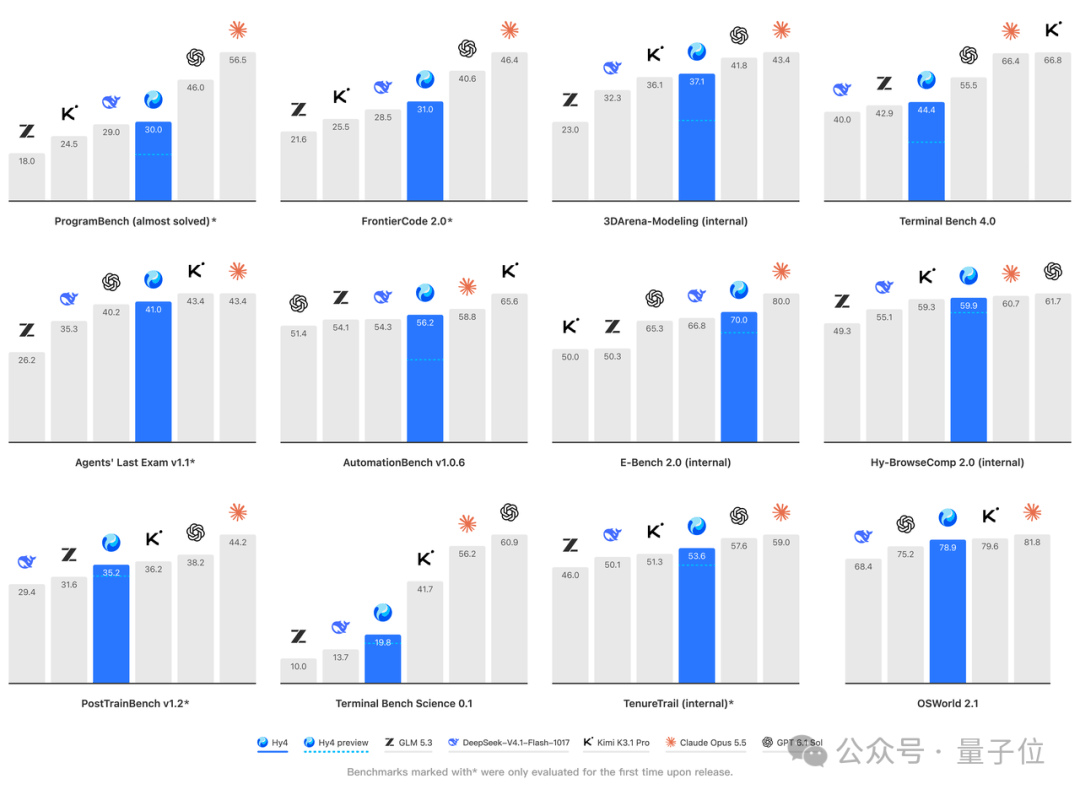
Tencent released Hunyuan Hy4, a 770B-parameter model with 49B active parameters, introducing native vision and computer-use capabilities for the first time. The model is integrated into WorkBuddy and other products, with weights to be open-sourced soon. Hy4 demonstrates high-fidelity visual understanding, such as locating 2-meter roof components in a 2.8-billion-pixel aerial image.
1 reports · 1 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe