StarSkirmish Bench refreshed with flagship LLM results for StarCraft BW coding
A developer refreshed StarSkirmish Bench, a benchmark where LLMs play StarCraft: Brood War by writing code, adding results from flagship models of OpenAI, Anthropic, Google, and Muse. The update provides a new comparison point for code-driven game-playing capabilities across major AI labs.
Coverage timeline
Hacker News__cayenne__
I've refreshed StarSkirmish Bench, a benchmark where LLMs play StarCraft BW by writing code, with results from the flagship models of OpenAI, Anthropic, Google, and Muse
Related stories
Google unveils Gemini 4 Argon, limits early access to cyber defenders
Google DeepMind announced Gemini 4 Argon, its next frontier model, on September 30, 2026, with initial access restricted to a set of trusted cybersecurity defenders via the Fairwind Program. The model features a 1M-token output limit, priced at $2/1M input and $10/1M output tokens initially, rising later, and reportedly outperforms GPT-6 Astra on coding and knowledge benchmarks. Internal skepticism exists, with some employees claiming real-world coding struggles, which Google disputes.
10 reports · 7 sources1691 points · 1177 comments

Google launches Gemini 4 Argon frontier model with API rollout
Google DeepMind has released Gemini 4 Argon, the first frontier model in the Gemini 4 series, claiming it outperforms rivals like GPT-6 Astra and Claude Opus 5.5 across benchmarks in coding, cybersecurity, science, finance, and law. The model is available globally via the Gemini API, to Google AI Pro subscribers in the Gemini app and AI Mode, and in Antigravity for Ultra users. Launch pricing is $2 per million input tokens and $10 per million output tokens, with a 50% discount until November 30, after which prices double on December 1.
8 reports · 6 sources1459 points · 1038 comments

BenchShield Framework Detects Reward Hacking in LLM-Agent Evaluations
Researchers from Dartmouth, UC Berkeley, and BenchFlow AI introduced BenchShield, a framework for detecting reward hacking in LLM-agent evaluation infrastructure. It extends checks to the entire scoring process, using static analysis to find exploit paths and runtime evidence to determine if agents attempted or used them. The paper highlights a case where a Lean proof verifier gave full marks to an incorrect proof due to disabled kernel type checking.
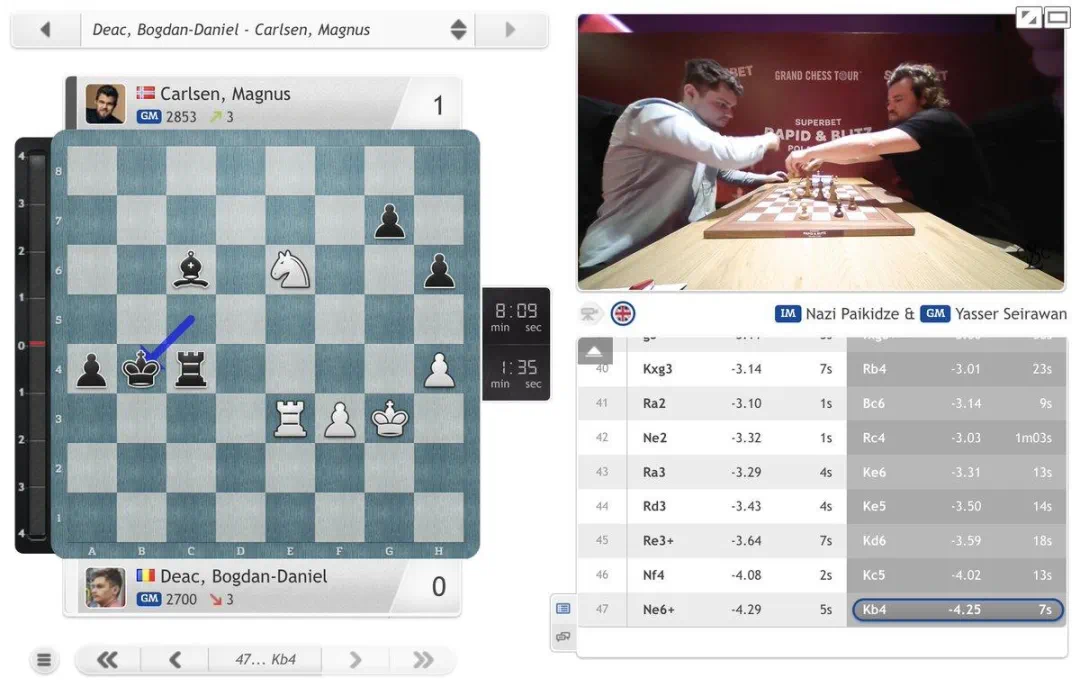
Princeton's QUEEN: 4B Chess Model Plays at Grandmaster Level and Explains Moves
Princeton University's Chen Danqi team released QUEEN, an open-source chess model with about 4 billion parameters that plays at the level of a typical grandmaster and explains its moves in natural language. The model, detailed in an arXiv paper, aims to bridge the gap between strong but silent chess engines and fluent but weak language models.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe