World Labs unveils Atlas, a multimodal world model with pixel-level camera control and 3D reconstruction
World Labs, founded by Fei-Fei Li, released Atlas, described as the world's first multimodal world model. It generates images and videos with pixel-level camera control, reconstructs 3D scenes from one to dozens of images, and supports spatiotemporal simulation for robotics and VFX. Atlas is trained from scratch on text, image, video, and 3D data, and is currently available to select partners, not open-sourced.
Coverage timeline
Techmeme
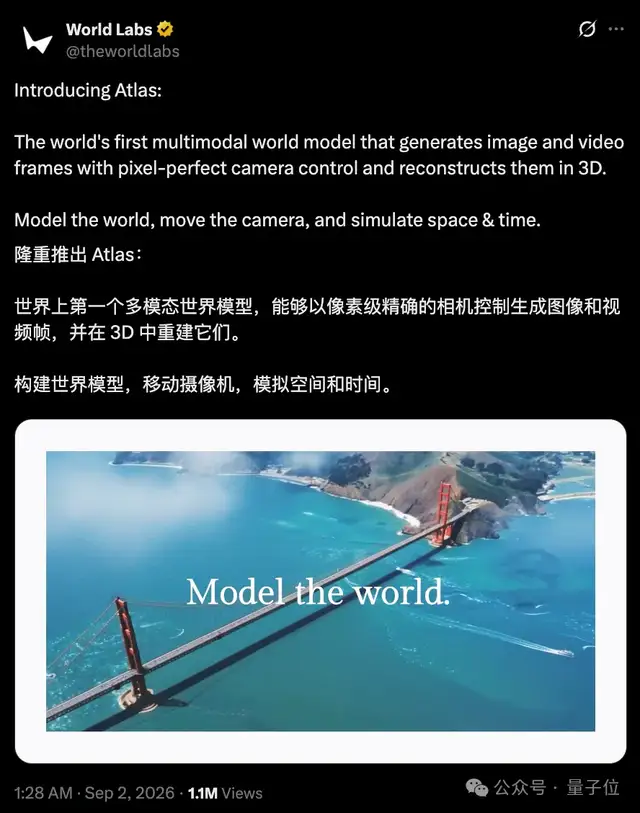
World Labs : Fei-Fei Li's World Labs unveils Atlas, a multimodal world model that generates image/video frames with pixel-perfect camera control and reconstructs them in 3D — World models generate, reconstruct, and simulate any possible world. They understand how worlds appear, behave …

量子位量子位
李飞飞发布:全球首个多模态世界模型 鱼羊 2026-09-02 09:07:13 来源: 量子位 一张图补全3D世界,还能给机器人造训练场 鱼羊 发自 凹非寺 量子位 | 公众号 QbitAI 「全球首个」 多模态世界模型 ,来了! 来自李飞飞World Labs。 World Labs对这个名为 Atlas 的新一代世界模型,用词可谓毫不克制,「全球首个」之外,slogan也明确强调出,这一次,可不只是生成一段可互动视频了哟: 建模世界,移动相机,模拟空间和时间。 就是说,Atlas能够以像素级的相机控制生成图像和视频帧,并完成3D重建。并且 空间 和 时间 都能理解。 李飞飞本人将其视作World Labs的「里程碑式」成果,直接一手置顶: Atlas为 从视觉特效到机器人 的众多应用场景打开了大门。 飞飞高徒、英伟达机器人主管Jim Fan也来捧场,指出:这是机器人领域Real-to-Sim的一大步。 具体来说,Atlas是一个 多模态自回归扩散Transformer ,它的能力包括: 相机控制生成 :仅需一张图片,Atlas即可生成具有像素级相机控制的图片和视频,最高可输出1分钟、1440p的视频。 空间重建 :Atlas可以基于一张到数十张输入图像,重建真实世界场景。既可以生成新视角下的图像帧,也能输出显式3D表示,其效果超过当前专门针对3D重建训练的最先进模型。 时空模拟 :Atlas可以根据输入视频同时建模空间和时间,可以转换已有视频中的观察视角,制作具有戏剧性的视觉效果,同时支持机器人Real-to-Sim工作流。 图像生成 :Atlas可以根据文本生成图片和360°全景图,能够遵循复杂Prompt、准确渲染文字,并生成大量不同的视觉风格。 对于 机器人模拟 ,仅需喂Atlas几张照片,它就能生成逼真的RGB和深度数据。这样一来,机器人就能在更多不同的模拟空间中进行训练和测试。 从头训练的多模态世界模型 技术细节上,Atlas是一个 全能模型 (omni model)。 它的目标,是在一个统一的模型架构中,同时处理多任务、多种输入和输出数据。 与此同时, 空间控制是整个模型的核心 。 为了实现这些目标,李飞飞团队设计了一种全新的基础架构,来作为未来世界模型的基础—— 多模态自回归扩散 Transformer 。 文本、图像、视频、3D数据……各种输入
机器之心机器之心
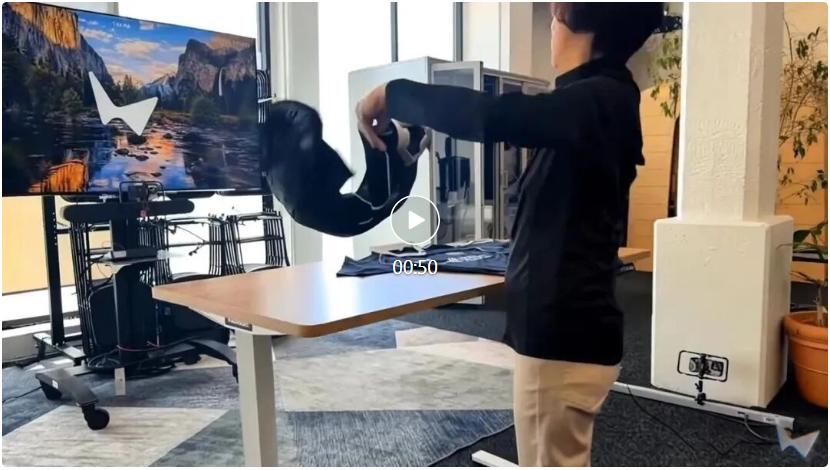
编辑|Panda 今天,李飞飞创业公司 World Labs 发布了新一代世界模型 Atlas 。其中一个示例是它生成的画面:李飞飞在办公室里叠衣服,效果极为真实。 李飞飞本人也开玩笑转发说:「我们办公室里确实真的在叠衣服!」 那么,Altas 究竟是什么?又是如何让数字世界的李飞飞分身如此拟真地叠衣服的? 一个模型,四种模态 World Labs 把 Atlas 称作 omni model (全模态模型),从零开始预训练,原生处理 文本、图像、视频 和 3D 四种数据。 官方 𝕏 上的表述是「 世界上第一个能以像素级相机控制生成图像与视频帧、并将其重建为 3D 的多模态世界模型 」。 这里,我们可以看到 Atlas 的四大能力: 相机可控生成 ,从一到六张参考图出发,按用户指定的机位和角度生成新视角,最高输出 1440p、时长最长 1 分钟的视频。 空间重建 ,从一张到几十张输入图重建真实场景,既输出新视角的图像帧,也输出点云和 3D 高斯泼溅这样的显式 3D 结果。 时空模拟 ,从输入视频中同时建模空间与时间,用于视频重构图和机器人的 Real-to-Sim 流程。 图像生成 ,包括文生图和 360 度全景图。 Atlas 目前不开源,仅向少数合作伙伴开放早期访问申请,后续将驱动 Marble 及 World Labs 的其他产品。 核心设计:空间上下文 Atlas 最核心的设计,World Labs 称之为 空间上下文(spatial context) 。 Atlas 是一种多模态自回归扩散 Transformer。其输入在三维空间中进行 grounded,以形成空间上下文,并基于该上下文生成多模态输出。 类比一下大语言模型:LLM 把输入编码成 context,再基于 context 生成后续 token。Atlas 的流程相同,区别在于,进入 context 的每一张图像都被锚定在三维空间中的一个具体位置——它带着 相机位姿 一起进来。 这个改动带来的直接后果是相机不再靠文字描述。过去让视频模型「向左推轨」「升降镜头」,只能把这些电影术语写进提示词里,模型理解到什么程度是个黑箱。 Atlas 把相机几何做成了原生输入类型 。 World Labs 表示这能让创作者「坐进导演椅,而不是在拉老虎机的拉杆」。 更有意思的是对上下文的编排。你可以往空间上下文里放
Related stories
AMD to acquire World Labs for $8.2B; Fei-Fei Li to become EVP and chief scientist
AMD announced an all-stock acquisition of World Labs, the AI research lab co-founded by Fei-Fei Li, for approximately $8.2 billion. Li will join AMD as executive vice president and chief scientist, reporting to CEO Lisa Su, and the deal is expected to close by the end of the year. World Labs, launched in 2024 and valued at $1 billion within months, released its first commercial product, the world generation model Marble, in 2025.
4 reports · 4 sources

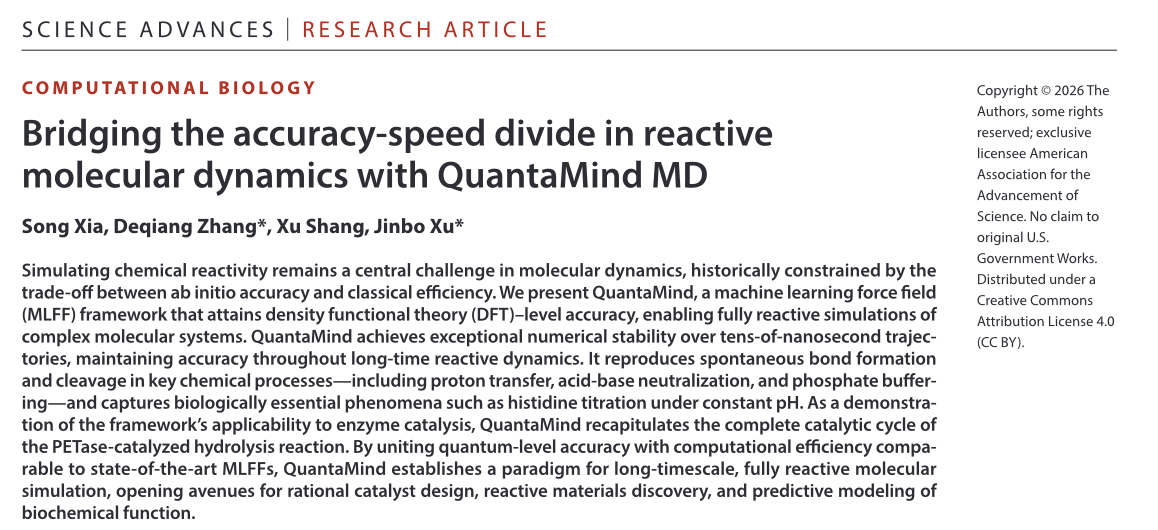
QuantaMind reactive MD platform published in Science Advances, scales to 100k atoms and 100ns
Molecular Heart's reactive atom modeling platform QuantaMind was published in Science Advances, claiming to push reactive molecular dynamics with near-DFT accuracy to tens of thousands of atoms and tens of nanoseconds, with extended tests reaching 100,000 atoms and 100 nanoseconds. The work addresses the long-standing trade-off between accuracy, speed, and scale in simulating chemical bond breaking and formation in large biomolecular systems.
1 reports · 1 sources
Chinese AI outlet surveys divergent world model definitions from Li, LeCun, Zhu
A Chinese AI outlet surveyed competing definitions of world models from Fei-Fei Li, Yann LeCun, and Jun Zhu, noting the term lacks consensus in 2026. Li's World Labs categorizes models as renderers, simulators, and planners; LeCun advocates learning predictable world structures in abstract latent spaces; Zhu's framework defines core capabilities from first principles and proposes a five-level roadmap.

JD Research Institute Open-Sources Interactive Audiovisual World Model JoyAI-EchoWM
At the JDD conference on September 9, JD Research Institute released and open-sourced JoyAI-EchoWM, an interactive audiovisual world model that generates video, ambient sound, music, and speech in a unified framework and responds to user operations in real time. It also upgraded the long-form audiovisual generation model to JoyAI-Echo 1.5. In evaluations on 158 WBench Navigation cases, JoyAI-EchoWM scored 81.7 on average, leading in consistency (89.8) and interactivity (87.2).

News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe