JD Research Institute Open-Sources Interactive Audiovisual World Model JoyAI-EchoWM
At the JDD conference on September 9, JD Research Institute released and open-sourced JoyAI-EchoWM, an interactive audiovisual world model that generates video, ambient sound, music, and speech in a unified framework and responds to user operations in real time. It also upgraded the long-form audiovisual generation model to JoyAI-Echo 1.5. In evaluations on 158 WBench Navigation cases, JoyAI-EchoWM scored 81.7 on average, leading in consistency (89.8) and interactivity (87.2).
Coverage timeline
机器之心机器之心
编辑|杜伟 进入到 2026 年,可交互世界生成面对一道更难的考题: AI 生成的世界能否经得起用户反复探索? 一扇门画得逼真,只是起点。往前走,它要自然靠近;穿过走廊再回头,它还应该留在原来的位置。用户每一次移动、转身和折返,都在检验模型是否有能力记住已经生成的世界。 世界模型的竞争开始从画面质量延伸到持续交互中的可靠性。镜头要听从指令,场景要保持连贯,生成速度还要跟得上操作。这些能力需要同时成立,任何一处掉链子,都可能打断探索。 近一年来的技术进展,让这条主线更加清晰。谷歌 DeepMind 的 Genie 3 展示了实时探索与分钟级一致性,英伟达 SANA-WM 将分钟级生成、精确相机控制与更高效率结合了起来,World Labs 的 Atlas 通过空间上下文支持沿指定相机轨迹生成新视角,维持场景的几何关系。 当探索进一步触及到视听体验,新的问题随之出现:用户改变路线或者切换视角时,脚步声、环境声和人物说话声,是否能够与画面一起连贯地延续?因此,对于面向沉浸式内容的世界模型,视听生成与交互控制的结合更加值得关注。 9 月 9 日,在京东全球科技探索者大会(JDD)上,京东探索研究院发布 JoyAI-Echo 系列最新进展:超长音视频生成模型升级至 JoyAI-Echo 1.5; 同时发布并开源面向可交互视听世界生成的 JoyAI-EchoWM 。 该模型延续了此前 JoyAI-Echo 的原生音视频生成能力,在同一套框架中可以生成视频以及环境音、音乐和语音,同时能够实时响应用户操作。 现在,第一人称视角下,用户可以直接在场景中移动和探索;切换到第三人称视角,摄像机运动与主体运动也能保持协同。经过多轮、长时操作之后,整体画面、空间关系、主体状态依然能够很好地延续。 JoyAI-EchoWM 创造了一个真正可进入、可操控、可探索的视听一体化世界 。 在相关论文报告的 158 个 WBench Navigation 案例评测中,JoyAI-EchoWM 取得了 81.7 的最高平均分,并在一致性(89.8)和交互性(87.2)等指标上位于前列。同时四步因果流式版本 EchoWM-Flash 的平均分为 81.0,交互得分为 87.9,表明减少采样步数后,模型仍具备较强的导航响应能力。 相较于同一评测中的其他模型,Genie 3 强调实时探索与分钟级世界一致性;Li

Related stories
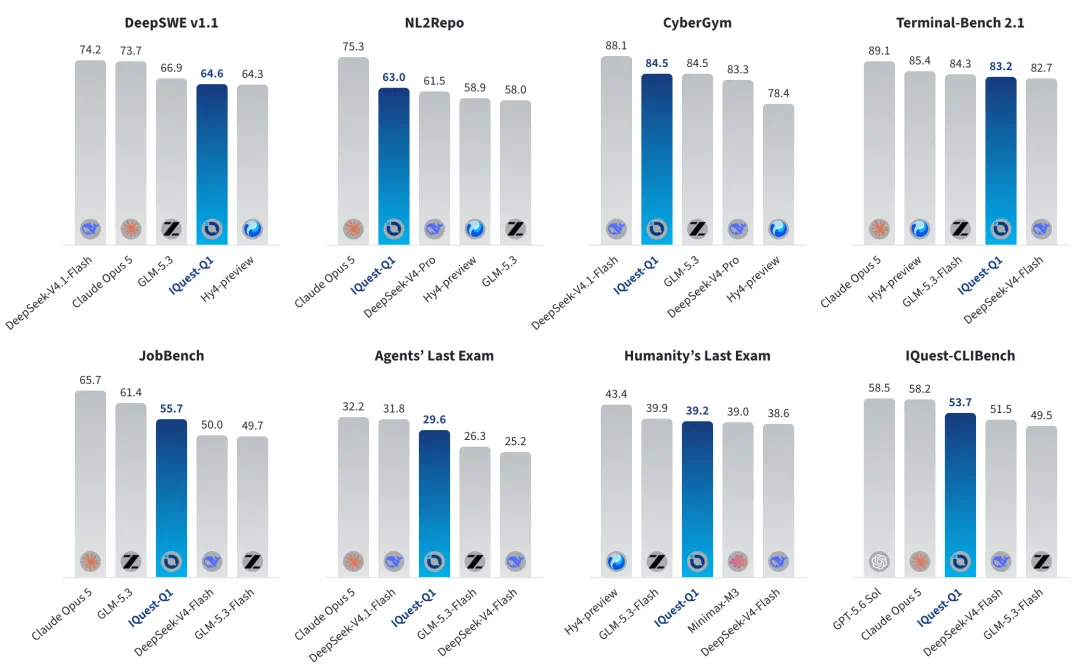
Zhizhi Innovation open-sources IQuest-Q1, 320B-param sparse MoE coding model
Chinese research institute Zhizhi Innovation released IQuest-Q1, a sparse MoE model with ~320B total parameters and ~15B active parameters, focused on coding, software engineering, and complex agentic tasks. The model shows balanced performance across benchmarks including NL2Repo, CyberGym, Terminal-Bench 2.1, DeepSWE v1.1, and JobBench, with weights and blog published on GitHub and Hugging Face.
1 reports · 1 sources
Current Robotics Unveils CurrentWorld-0, an Interactive World Simulator
Current Robotics released CurrentWorld-0, an interactive world simulator that models cross-embodiment, multi-view, and multimodal physical interactions for robot learning and evaluation. It is the team's second work after the humanoid whole-body manipulation model Curr-0, and is described as a data-driven alternative to traditional physics engines, capable of simulating flexible objects and fluids.
2 reports · 2 sources
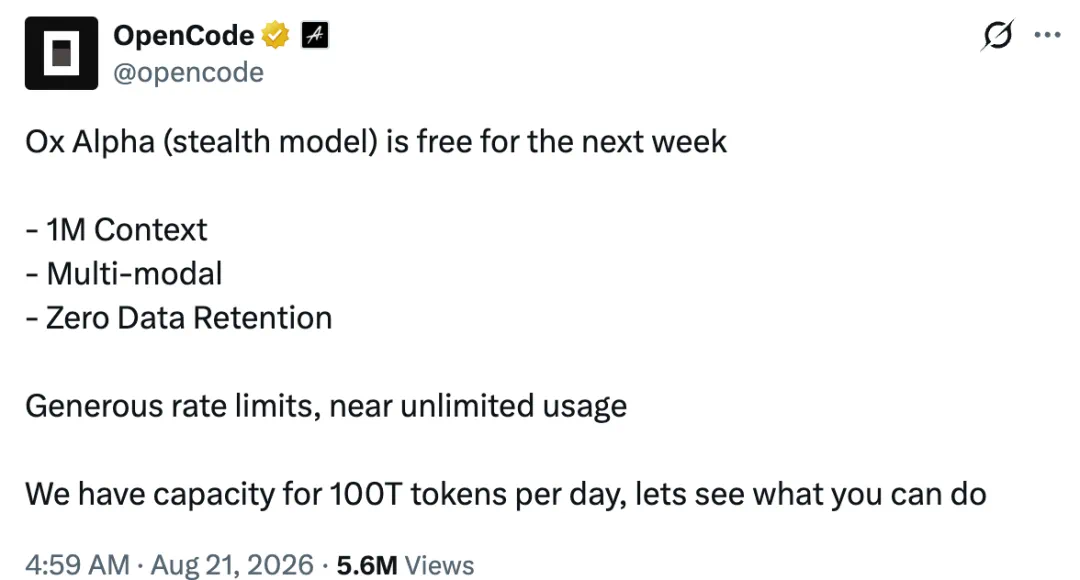
Z.ai confirms Ox Alpha is GLM-5.3 Flash, releases open weights
Z.ai confirmed that the anonymous model 'Ox Alpha', which went viral on OpenRouter, is a new iteration of its GLM series, specifically GLM-5.3 Flash, and released its weights on Hugging Face under a new license. The model, a 320B-parameter natively multimodal model running on domestic chips, topped OpenRouter's leaderboard and ended DeepSeek's 56-day streak on OpenCode. The license requires companies with over $10B in revenue to pass a security review.
9 reports · 4 sources801 points · 281 comments
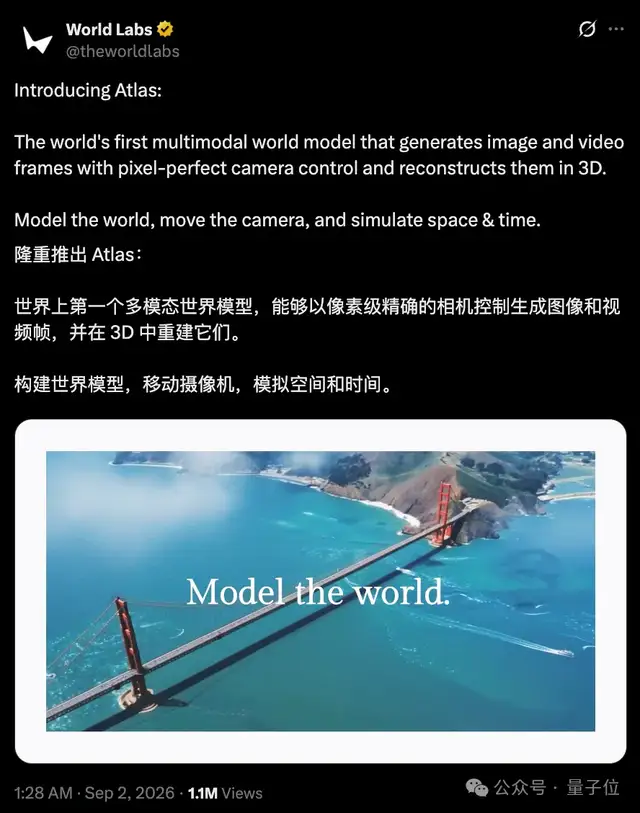
World Labs unveils Atlas, a multimodal world model with pixel-level camera control and 3D reconstruction
World Labs, founded by Fei-Fei Li, released Atlas, described as the world's first multimodal world model. It generates images and videos with pixel-level camera control, reconstructs 3D scenes from one to dozens of images, and supports spatiotemporal simulation for robotics and VFX. Atlas is trained from scratch on text, image, video, and 3D data, and is currently available to select partners, not open-sourced.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe