FlashStates Hybrid Cache Management Boosts Prefill Throughput Up to 3.14x vs vLLM
Researchers from Together AI, UIUC, and UT Austin propose FlashStates, a hybrid state cache management system for mixed-architecture LLMs that combine full attention with linear layers. On NVIDIA B200 GPUs, replaying real Claude Code traces, FlashStates achieves up to 3.14x prefill throughput over vLLM and reduces p90 time-to-first-token (TTFT) by up to 88.4%, with benefits persisting when integrated with a 512GiB Mooncake CPU cache.
Coverage timeline
机器之心机器之心
Kimi Delta Attention(KDA)、Gated DeltaNet(GDN)、Mamba-2 等线性注意力与状态空间层,正在成为开源大模型的常见组件。Kimi K3.1 Pro、GLM-5.3-Flash、Qwen3.8-Flash-Next、Nemotron 3 Super 都采用了「全注意力 + 线性层」的混合架构,以换取更快的解码和更小的 KV Cache。 但在编程 Agent 这类多轮、长上下文负载中,混合模型的前缀缓存管理比纯 Transformer 要更加复杂。来自 Together AI、UIUC 与 UT Austin 的研究团队提出 FlashStates,重新设计了混合架构模型的 KV 和状态缓存管理。在英伟达 B200 GPU 上回放真实 Claude Code 轨迹时,FlashStates 的预填充(prefill)吞吐最高达到 vLLM 的 3.14 倍,p90 首 token 延迟(TTFT)最多降低 88.4%。接入 512GiB 的 Mooncake CPU 缓存后,收益依然显著,并且已经支持分布式存储与跨节点的混合状态复用。 论文标题:FlashStates: Unlocking Flexible Hybrid State Management for Agentic LLM Inference 论文链接:https://www.alphaxiv.org/abs/2611.FlashState 代码:https://github.com/FutureMLS-Lab/FlashStates 项目主页:https://FlashStates.ai 作者介绍 本文由 Together AI、伊利诺伊大学厄巴纳-香槟分校(UIUC)与得克萨斯大学奥斯汀分校(UT Austin)合作完成 。共同第一作者为 Chenxi Li(Together AI)与 Weili Xu(UIUC),其他作者包括 Tianyi Zhang、Jue Wang、Zhongzhu Zhou(Together AI)与通讯作者 Chenfeng Xu(UT Austin)。 Together AI 于 2022 年 6 月创立,由 Flash Attention 作者 Tri Dao、斯坦福大模型研究中心主任 Percy Liang、芝加哥大学副教授
Related stories
PKU Researchers Propose MapFlow to Reuse Attention Maps Across LLMs, Cutting Prefill Latency 15-20%
Researchers at Peking University's PKU-DAIR lab propose MapFlow, a method that reuses attention maps as intermediate states across different LLMs to avoid recomputing context when switching models. In evaluations, MapFlow reduces prefill latency by 15-20% and boosts throughput by up to 25% under a P90 first-token latency constraint in multi-turn routing scenarios, while maintaining generation quality. The paper has been accepted at SIGMOD 2027 and the code is open-sourced.
1 reports · 1 sources
Google and collaborators release CLASHarness benchmark for multi-agent conflict in computer use
Researchers from Google, Emory, USC, UF, UChicago, UCSB, and Columbia released CLASHarness, a benchmark and pipeline for evaluating 15 major LLMs on multi-agent conflict scenarios in computer-use tasks. The dataset includes 600 multi-turn executable conflict tasks across 20 domains, with 7,970 4K visual evidence images and 3,284 mandatory checkpoints, and is open-sourced on GitHub.
Fudan team compares hybrid LLM architectures mixing full attention with sliding-window and gated linear attention
Fudan University's OpenMOSS team released a paper, 'Mechanics of Long-Context Hybrid Models', systematically comparing hybrid architectures that mix full attention with sliding-window attention (SWA) and gated linear attention (GLA/GDN) for long-context LLMs. Experiments at 376M, 776M, 1B, and 3B scales show that mixing NoPE attention with position-biased attention (RoPE, SWA, GLA/GDN) enhances length extrapolation and long-context training. The team found that hybrid placement improves long-context performance.
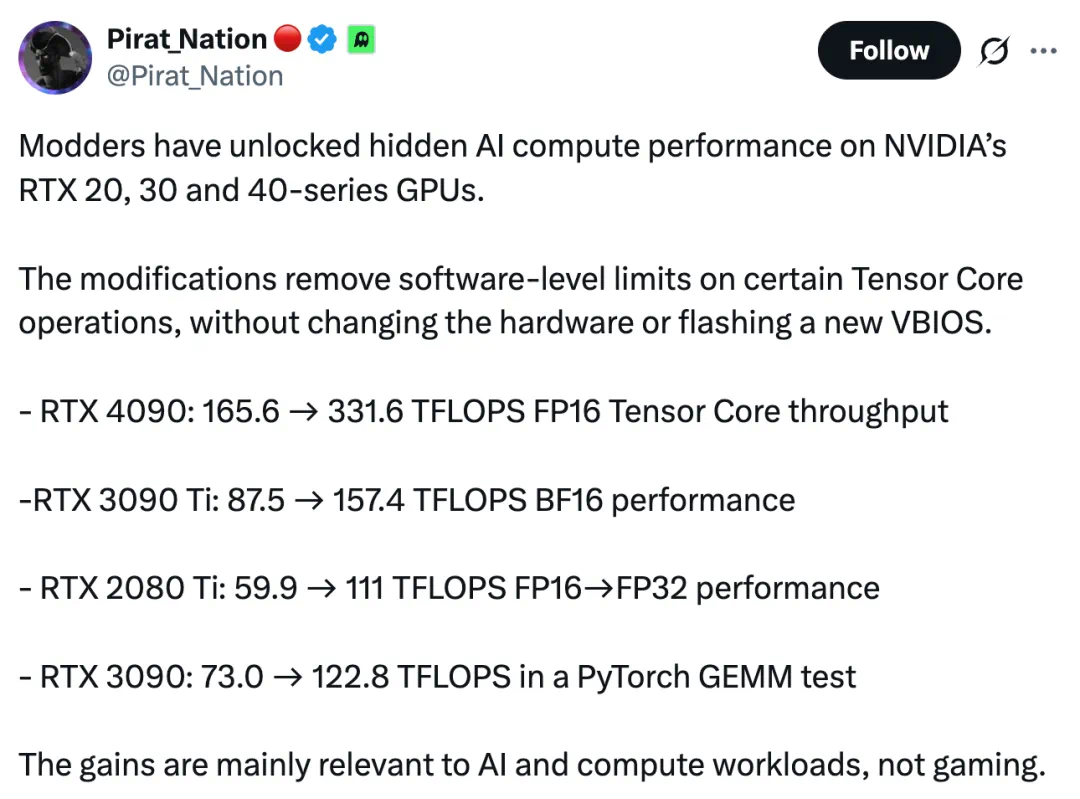
Open-source projects unlock hidden Tensor Core throughput on GeForce GPUs, doubling RTX 4090 performance
Open-source developers released projects on GitHub that unlock higher Tensor Core throughput on NVIDIA GeForce GPUs by modifying boot-time configuration, without driver swaps or BIOS flashes. Tests reportedly doubled the FP16/FP32 and BF16/FP32 throughput of an RTX 4090 from about 165 TFLOPS to over 330 TFLOPS, with gains also observed on RTX 3090 Ti, RTX 4070 Ti SUPER, and RTX 2080 Ti. The projects target RTX 20, 30, and 40 series, with some experiments done on Windows 11.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe